US English


7 Data Scientist VI Resume Templates with Example
By Ria · Last Updated On October 2, 2026
Resume Example Page 1

This guide shows you how to build a Data Scientist VI resume that is clear, focused, and easy to review. You will learn how to organize strong evidence, compare professional formats, and make important qualifications easy to find.

A strong resume for this role should connect advanced analysis with production delivery and technical leadership. Use concise experience bullets, clear skills sections, and accurate keywords for statistical modeling, machine learning, data engineering, SQL, Spark, Hive, Python, R, Scala, ETL and ELT, data quality, cloud operations, and technical mentoring.

The same complete resume is presented below in 7 ATS-friendly layouts. The examples show how different structures can organize experience, skills, education, projects, certifications, and measurable results while keeping the underlying evidence consistent.

What Makes a Great Data Scientist VI Resume in 2026

A strong Data Scientist VI resume is clear, evidence-based, and easy to scan. It should show advanced analytical work, production judgment, and technical leadership through focused sections and concise bullets.

Match important terms to the role when they are supported by your background, including statistical modeling, machine learning, Python, SQL, Spark, Hive, ETL and ELT, data quality, production operations, and technical mentoring.

The examples shown below are intentionally detailed to demonstrate a range of experiences, skills, accomplishments and relevant keywords. We prefer detailed resumes as they provide more context to the hiring managers and also help the ATS systems identify relevant qualifications and score your resume better for a match. But the length of a resume is an individual choice. If you want a one page resume, just keep the most relevant experience and information for the job. Note: Resume examples are for educational purposes only. Use only information that accurately reflects your experience and qualifications. References to real organizations do not imply affiliation or endorsement.

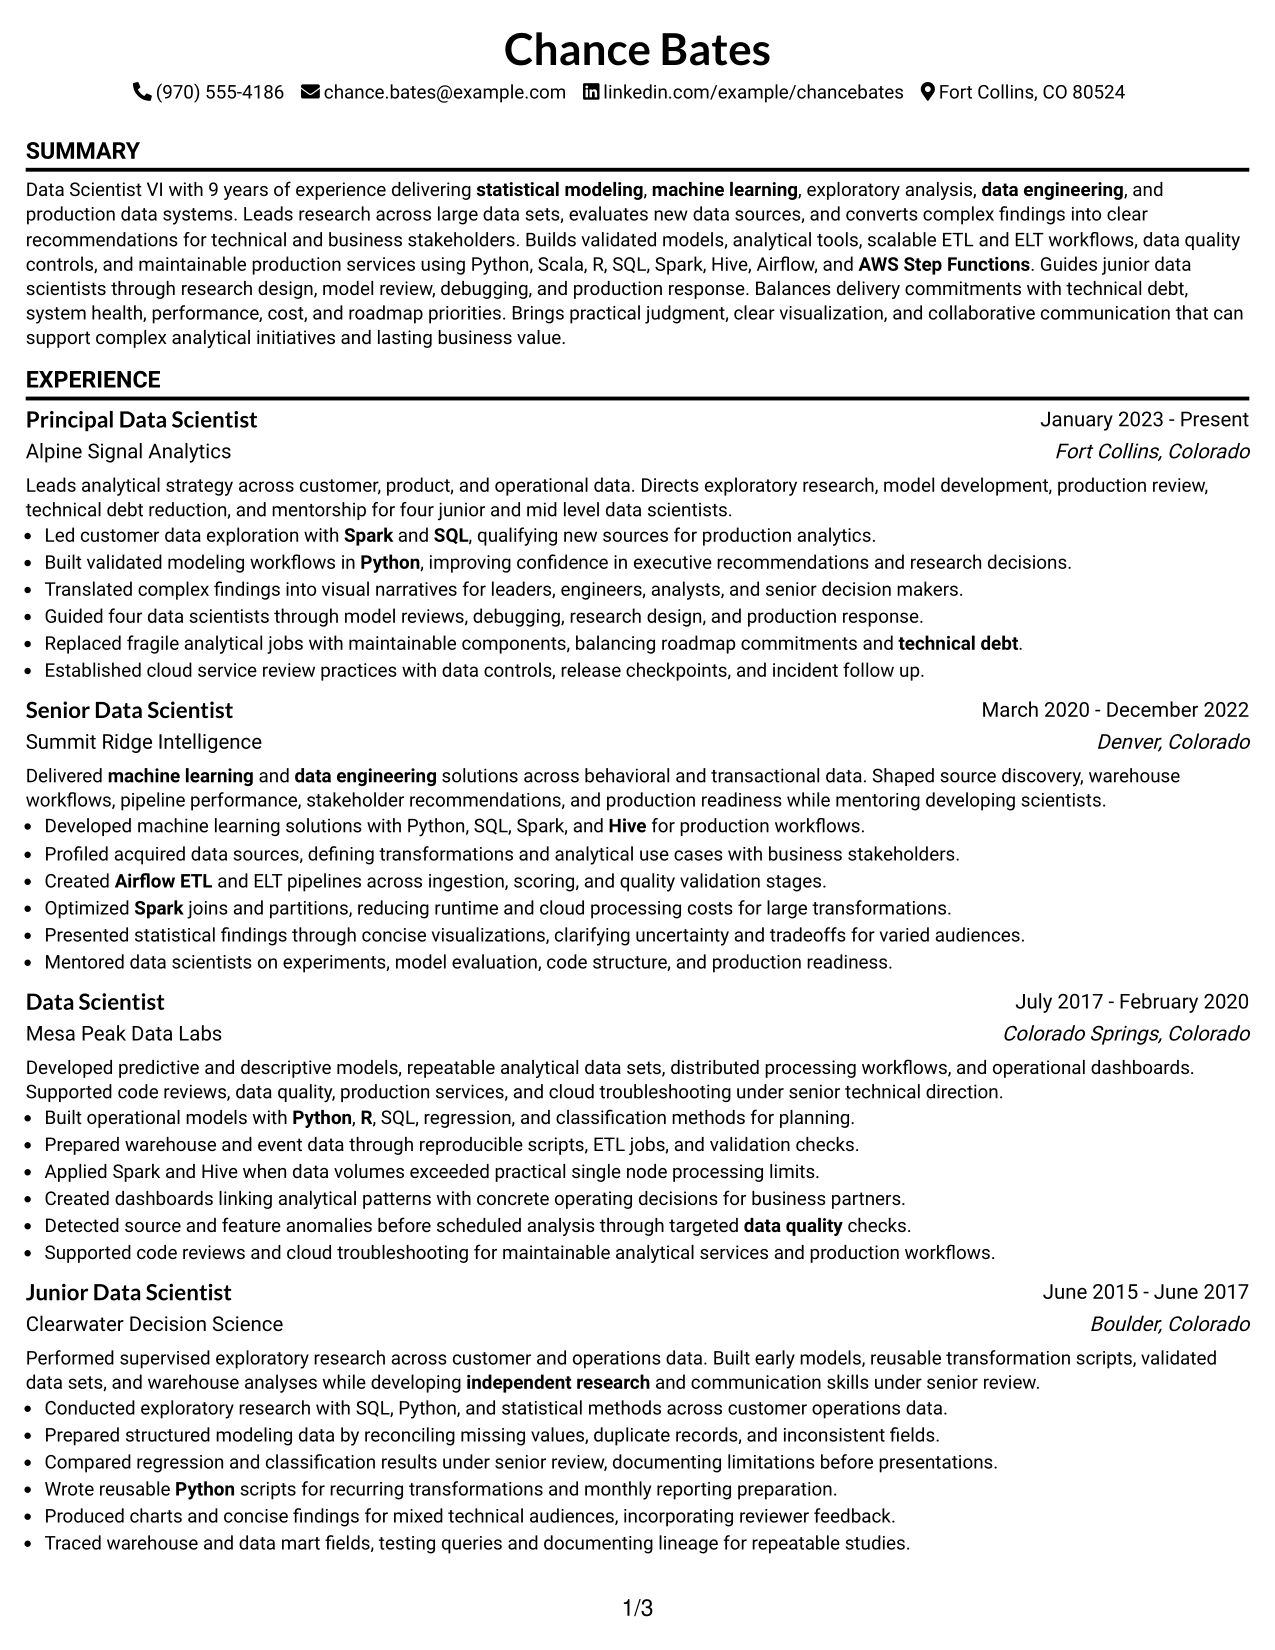
#1 Simple One Column Format Resume Example

The Simple One Column Format keeps a direct reading order, helping recruiters scan each resume section from top to bottom.
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • Linear section flow makes career progression easy to follow from role to role.
  • Full-width space gives experience and achievements room for clear, readable detail.
  • Consistent section order helps reviewers locate skills, education, projects, and credentials.

Best For

  • Detailed career histories
  • Strong chronological experience
  • Text-heavy achievement bullets
  • Straightforward recruiter scanning
  • Traditional U.S. applications

Resume Keywords

  • Data Scientist VI
  • statistical modeling
  • machine learning
  • Python
  • R
  • Scala
  • SQL
  • Spark
  • Hive
  • data engineering
  • Data Architecture
  • Data Warehouses
  • data mart
  • ETL
  • ELT
See all keywords
 

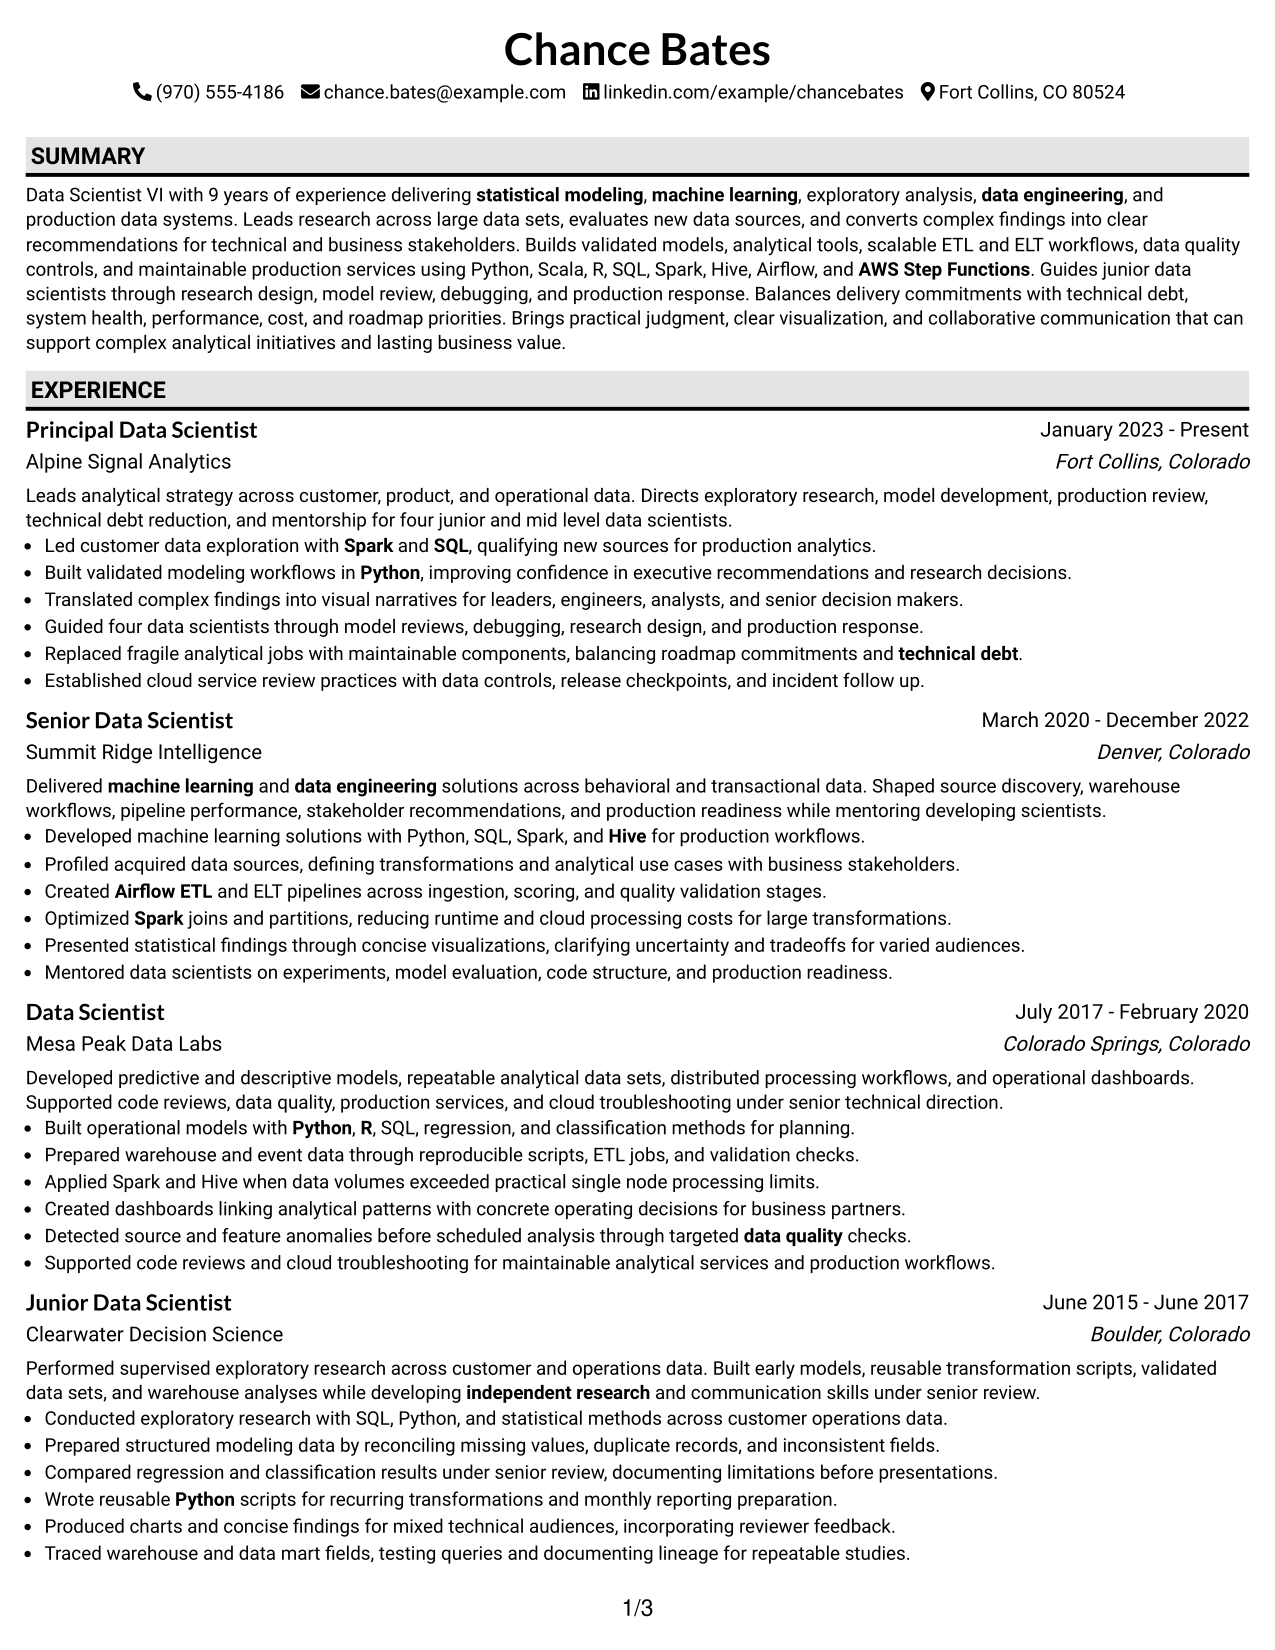
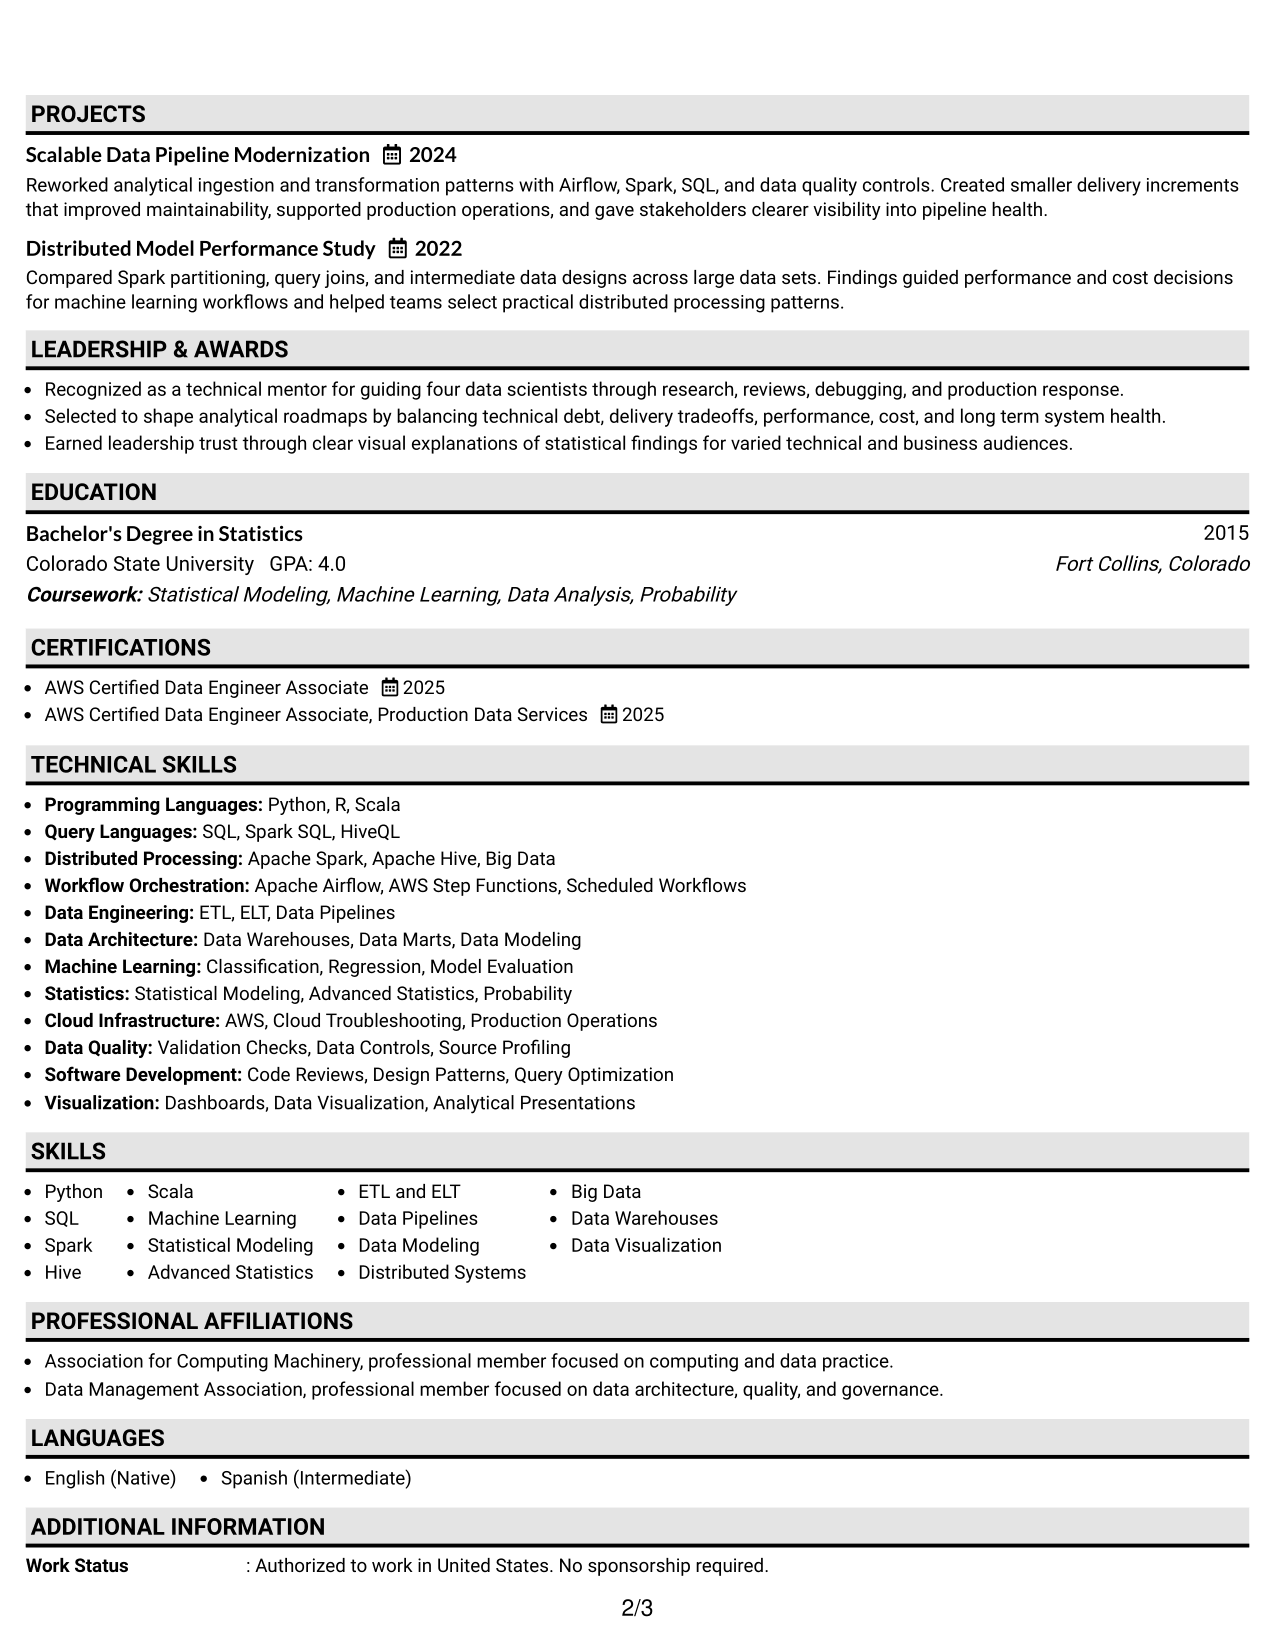
#2 Plain One Column with Shaded Labels Resume Example

The Plain One Column with Shaded Labels Format uses clear section labels to help recruiters move quickly through a single reading path.
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • Shaded labels separate major sections, making experience and skills easier to locate.
  • Single-column reading keeps achievements in a steady order without side-to-side movement.
  • Clear section boundaries help education and credentials remain distinct from work history.

Best For

  • Long technical resumes
  • Frequent section switching
  • Clear visual section breaks
  • Chronological work histories
  • Readers who prefer labeled sections
 

#3 One Column Format with Photo Right Resume Example

The One Column Format with Photo Right keeps the body in one clear sequence while a right-side header photo adds personal identification.
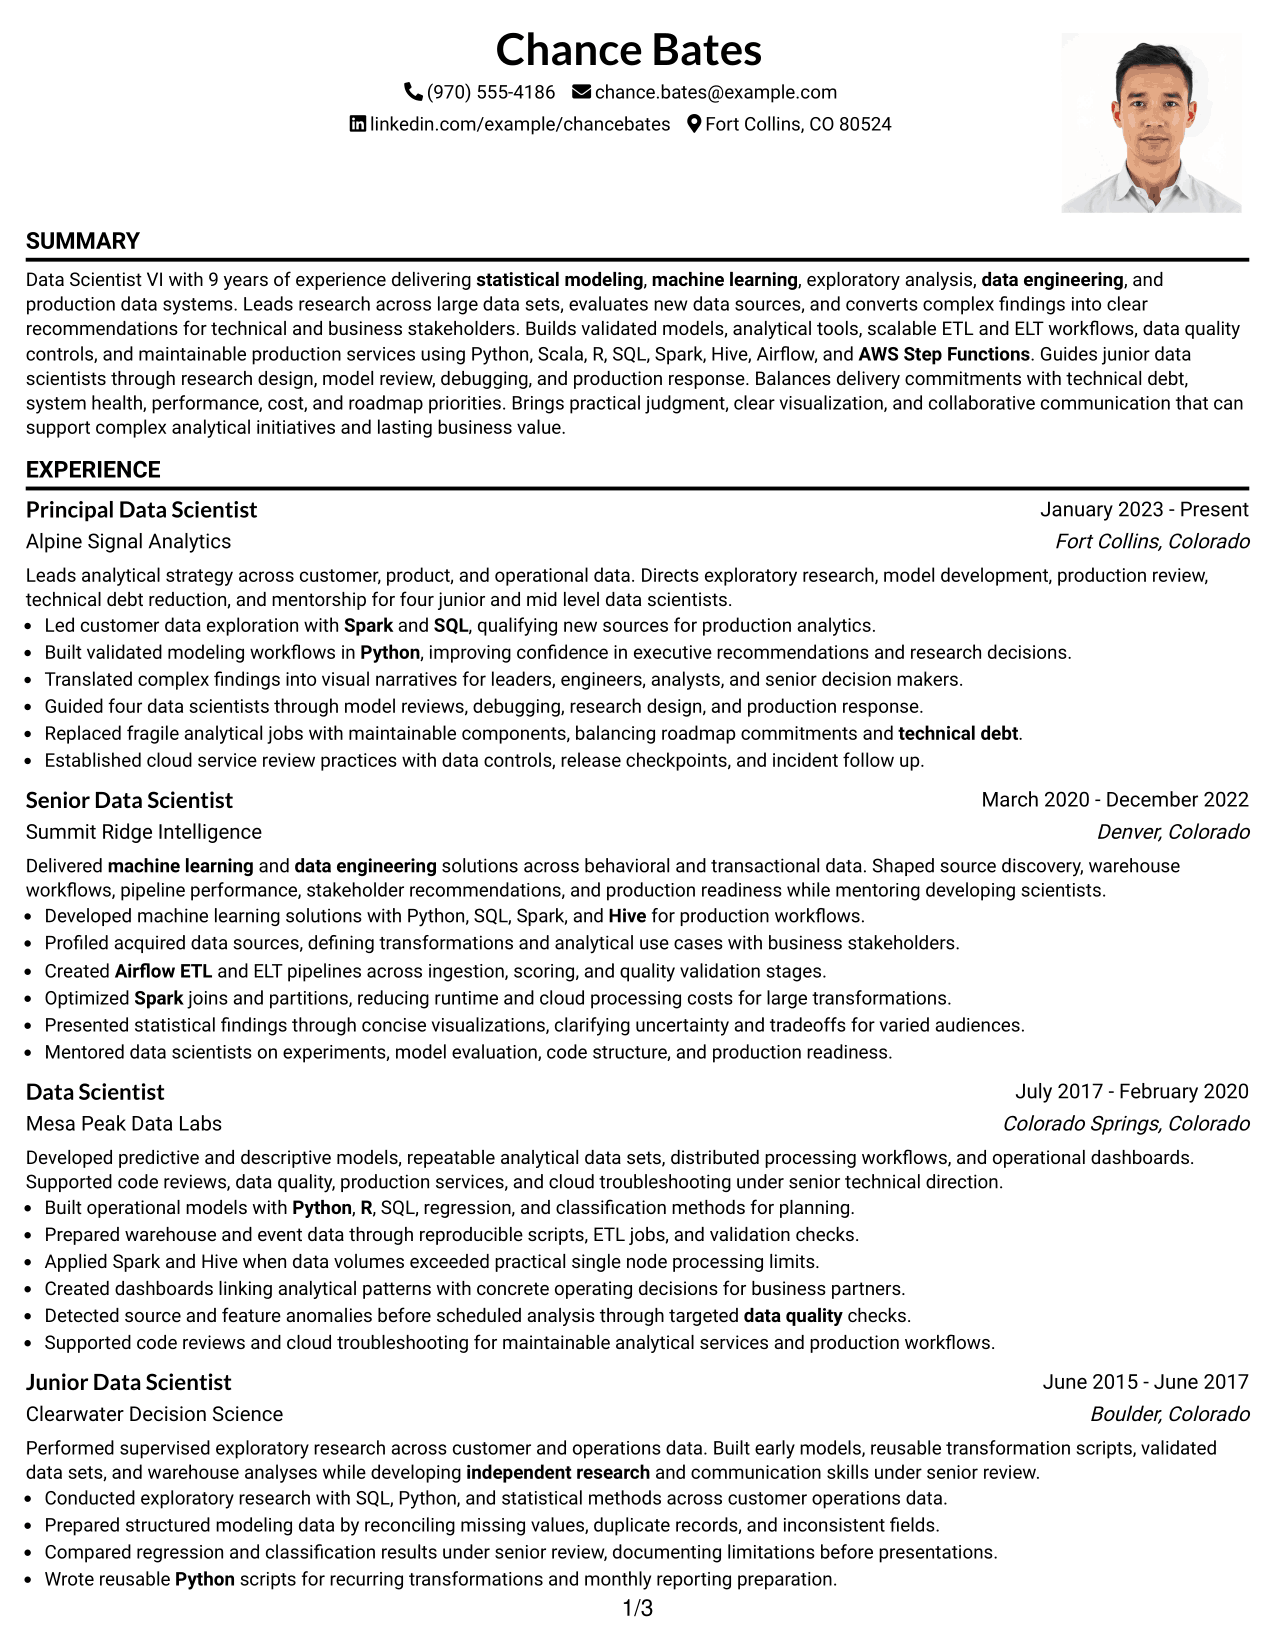
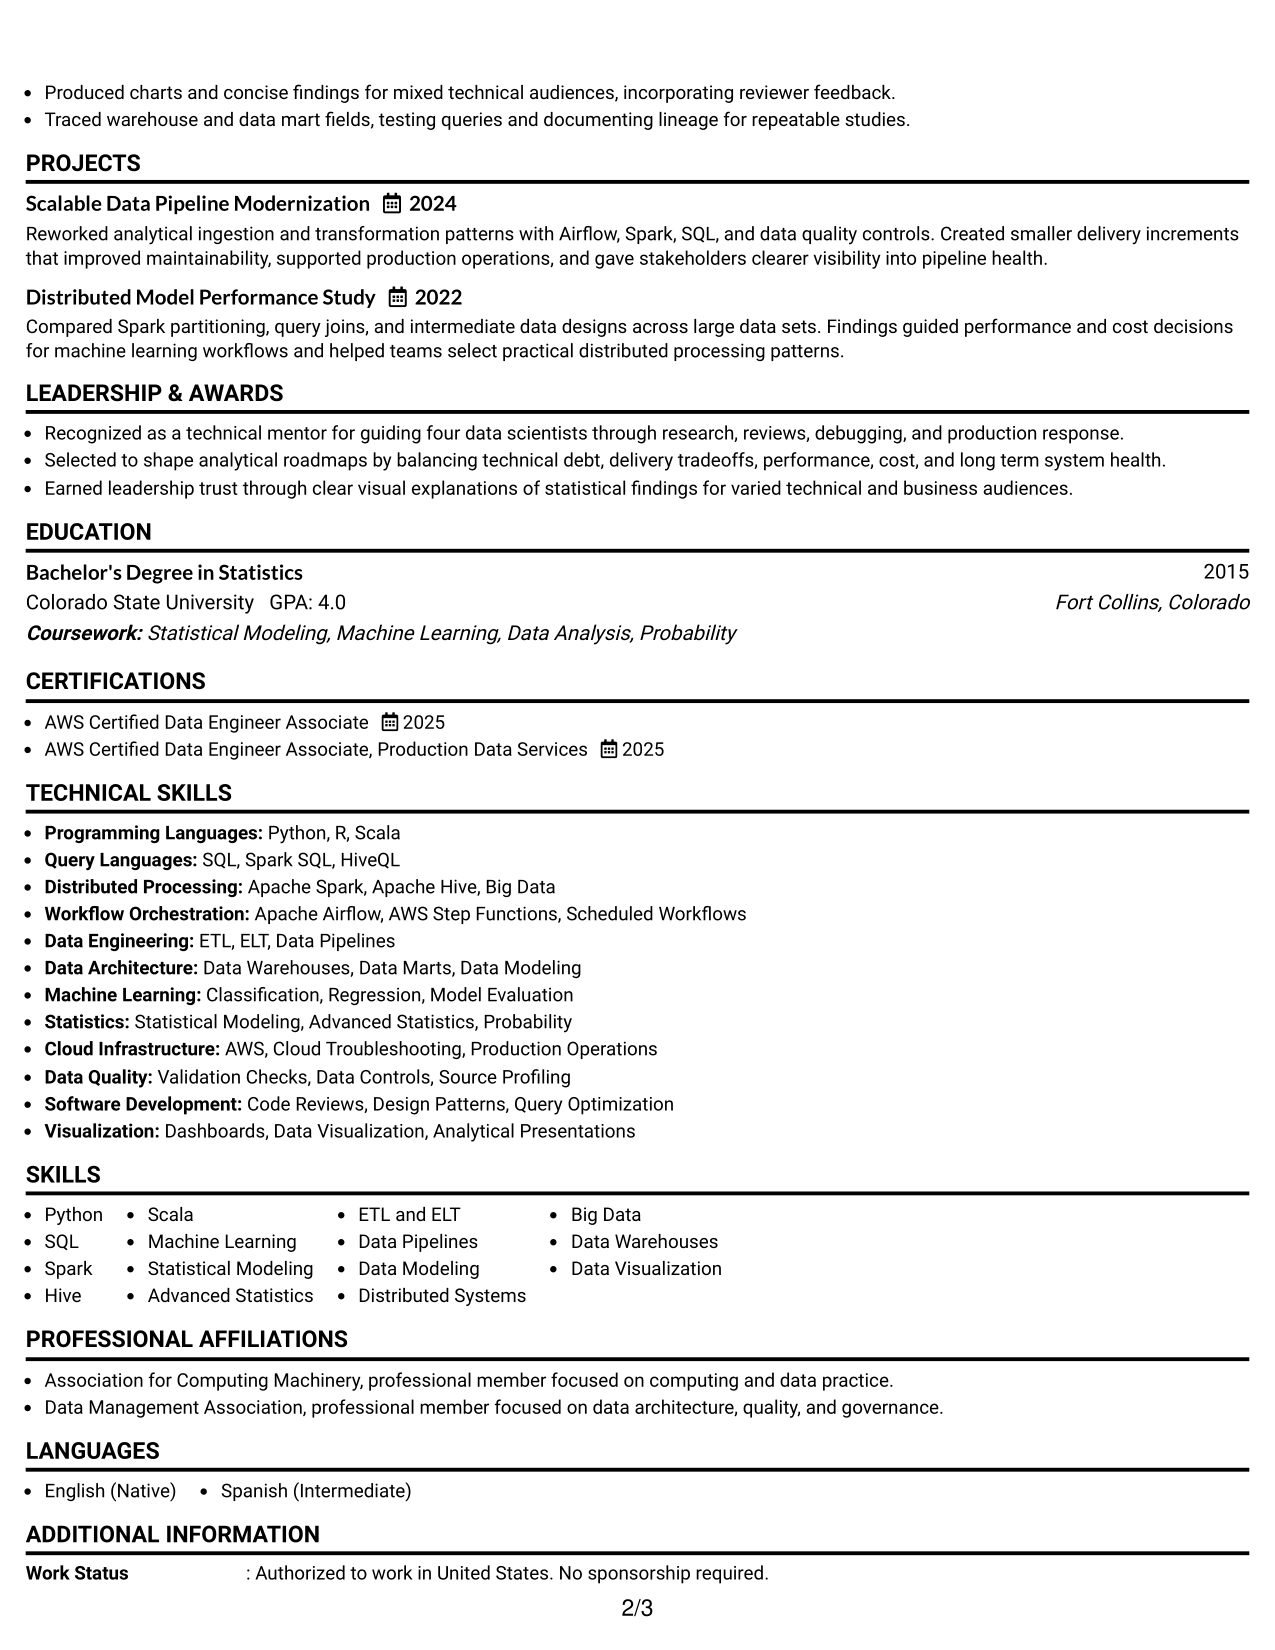
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • One-column body keeps work history and achievements in a predictable reading sequence.
  • Header photo stays separate from body sections, preserving clear content organization below.
  • Full-width sections provide space for skills, projects, education, and credentials.

Best For

  • Regions where photos are customary
  • Applications allowing professional photos
  • Full-width experience sections
  • Resume content with several supporting sections
  • Readers who value a clear top-to-bottom flow
 

#4 Clean Two Column Sidebar Format Resume Example

The Clean Two Column Sidebar Format separates supporting details from the main content, helping recruiters scan related information in parallel.
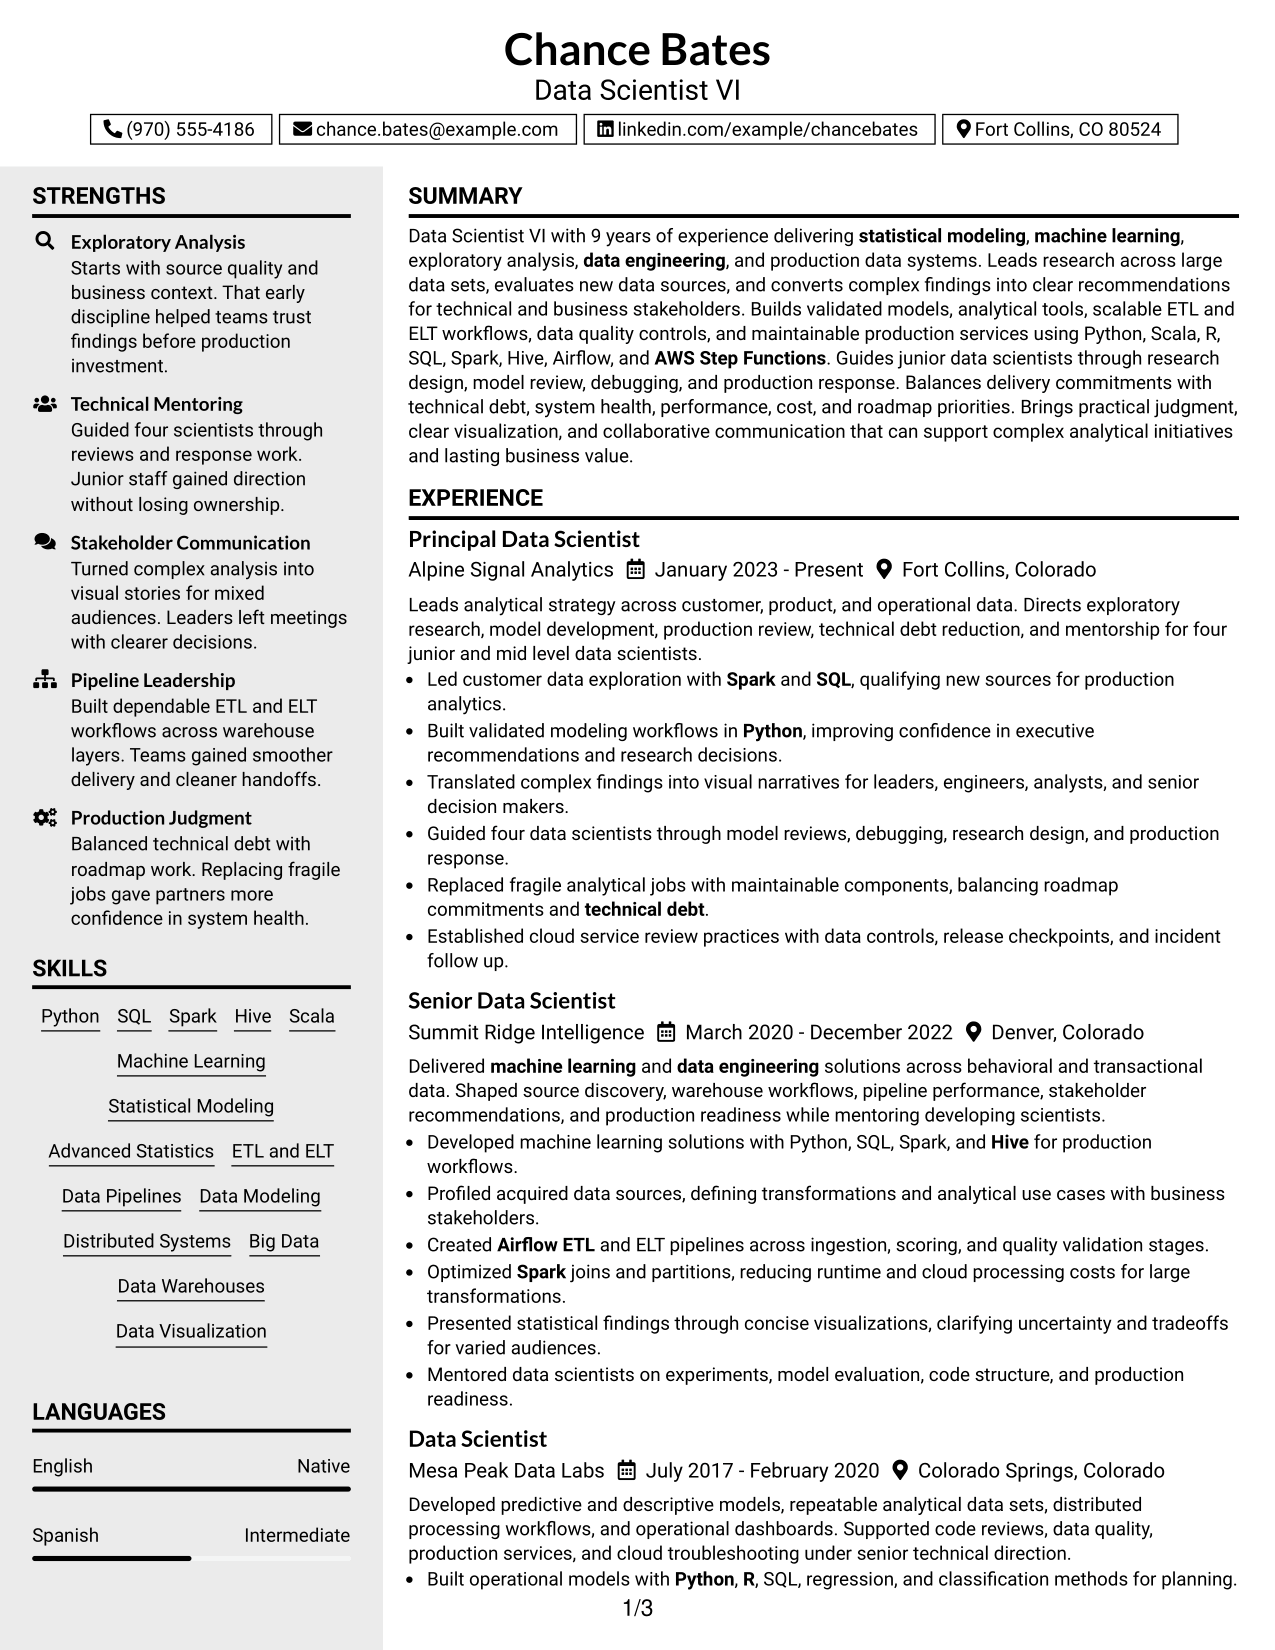
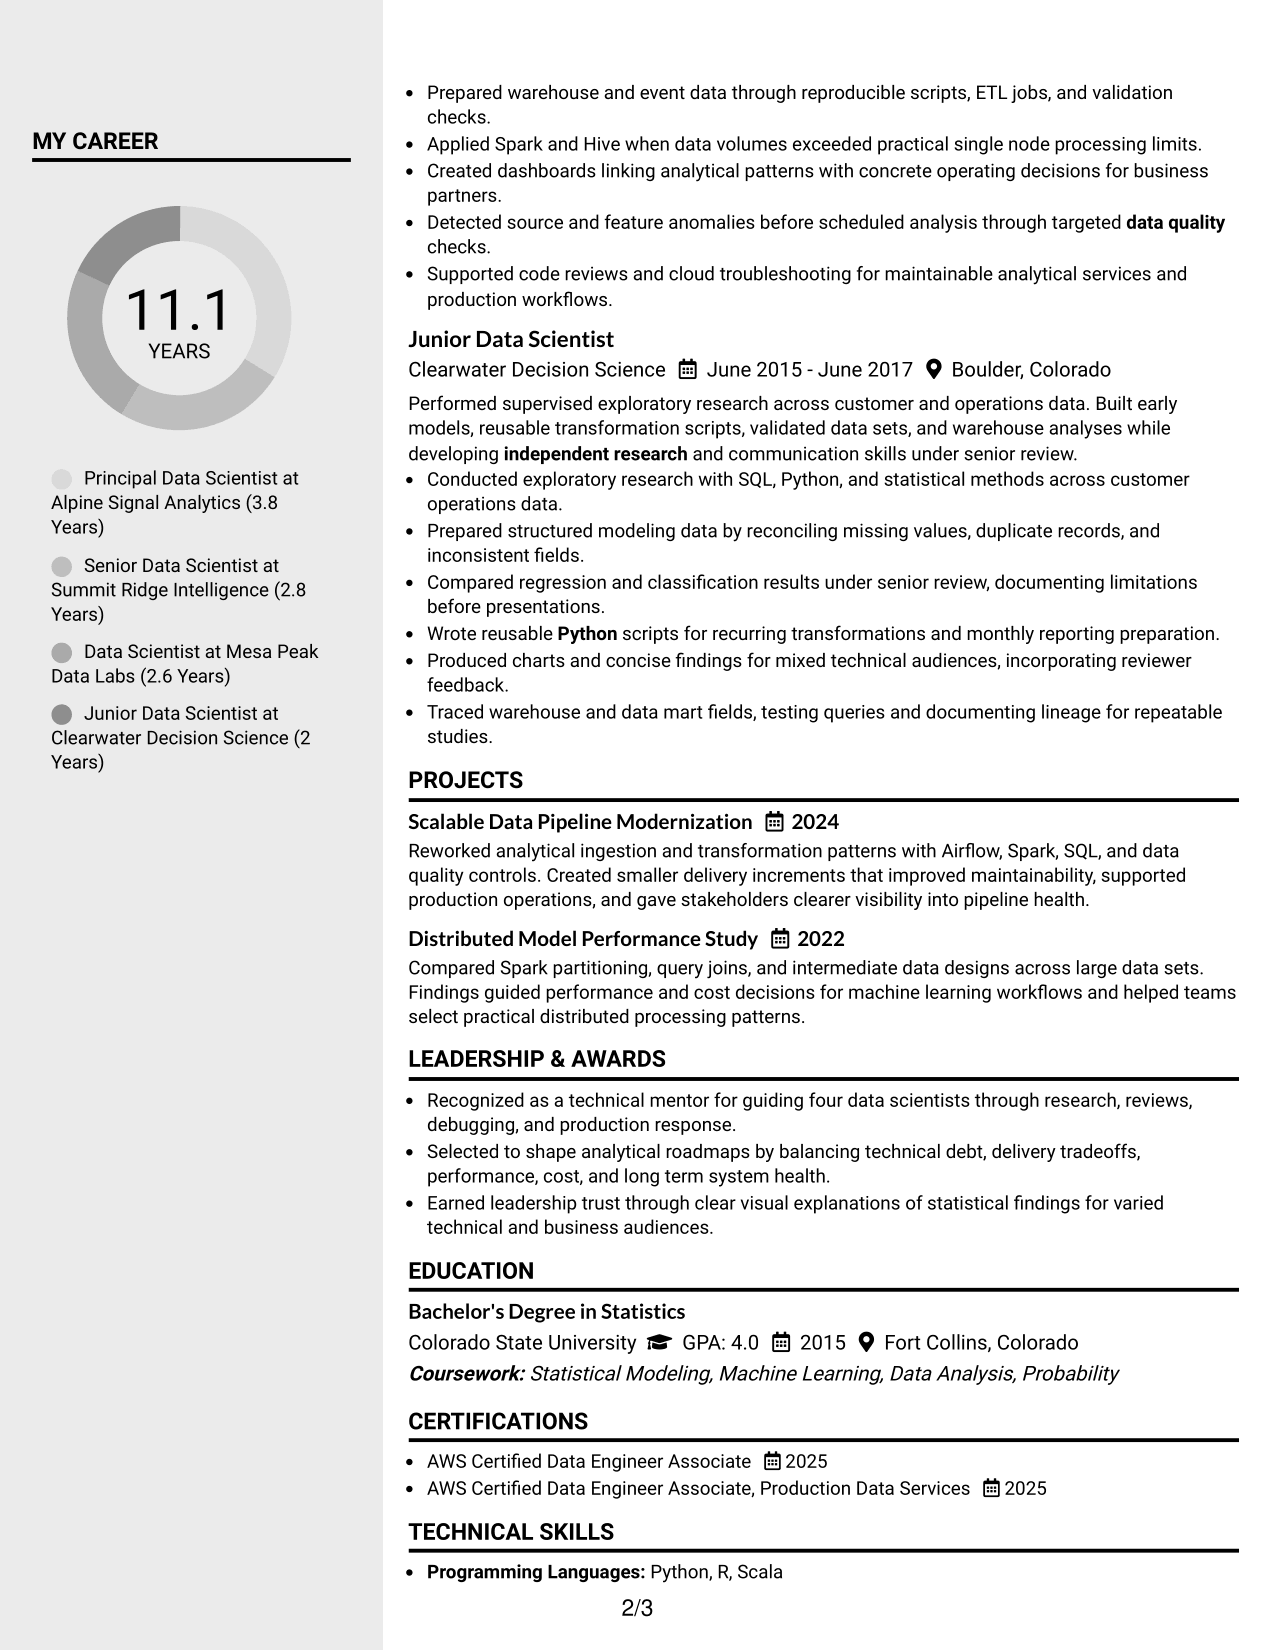
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • Two-column structure separates supporting details from the main experience narrative.
  • Sidebar organization makes skills and credentials easier to find without interrupting work history.
  • Main column gives career progression and achievements a clear, continuous reading path.

Best For

  • Broad technical skill sets
  • Compact supporting credentials
  • Experience-led resumes
  • Readers comparing skills with work history
  • Balanced use of page width


#5 Two Column Format Resume Example

The Two Column Format divides the resume into parallel content areas, helping recruiters compare major qualifications without losing section structure.
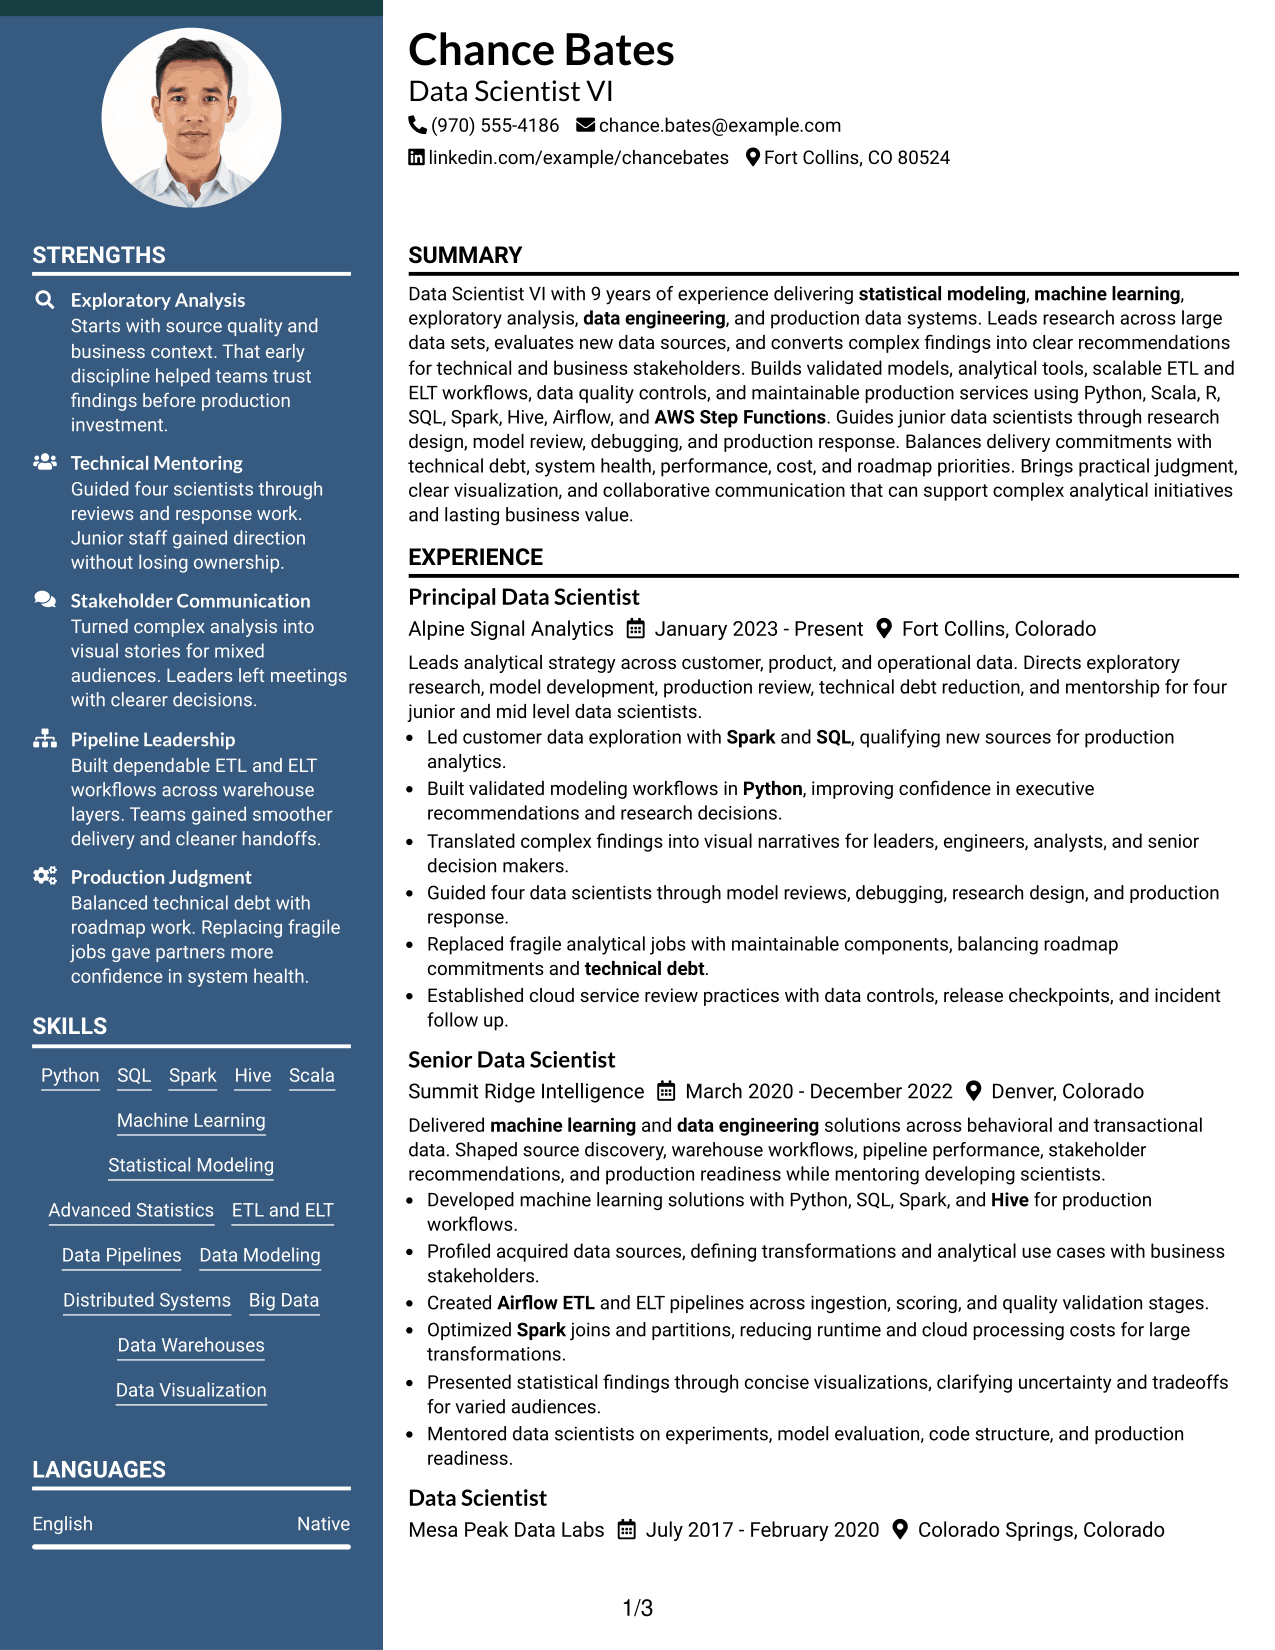
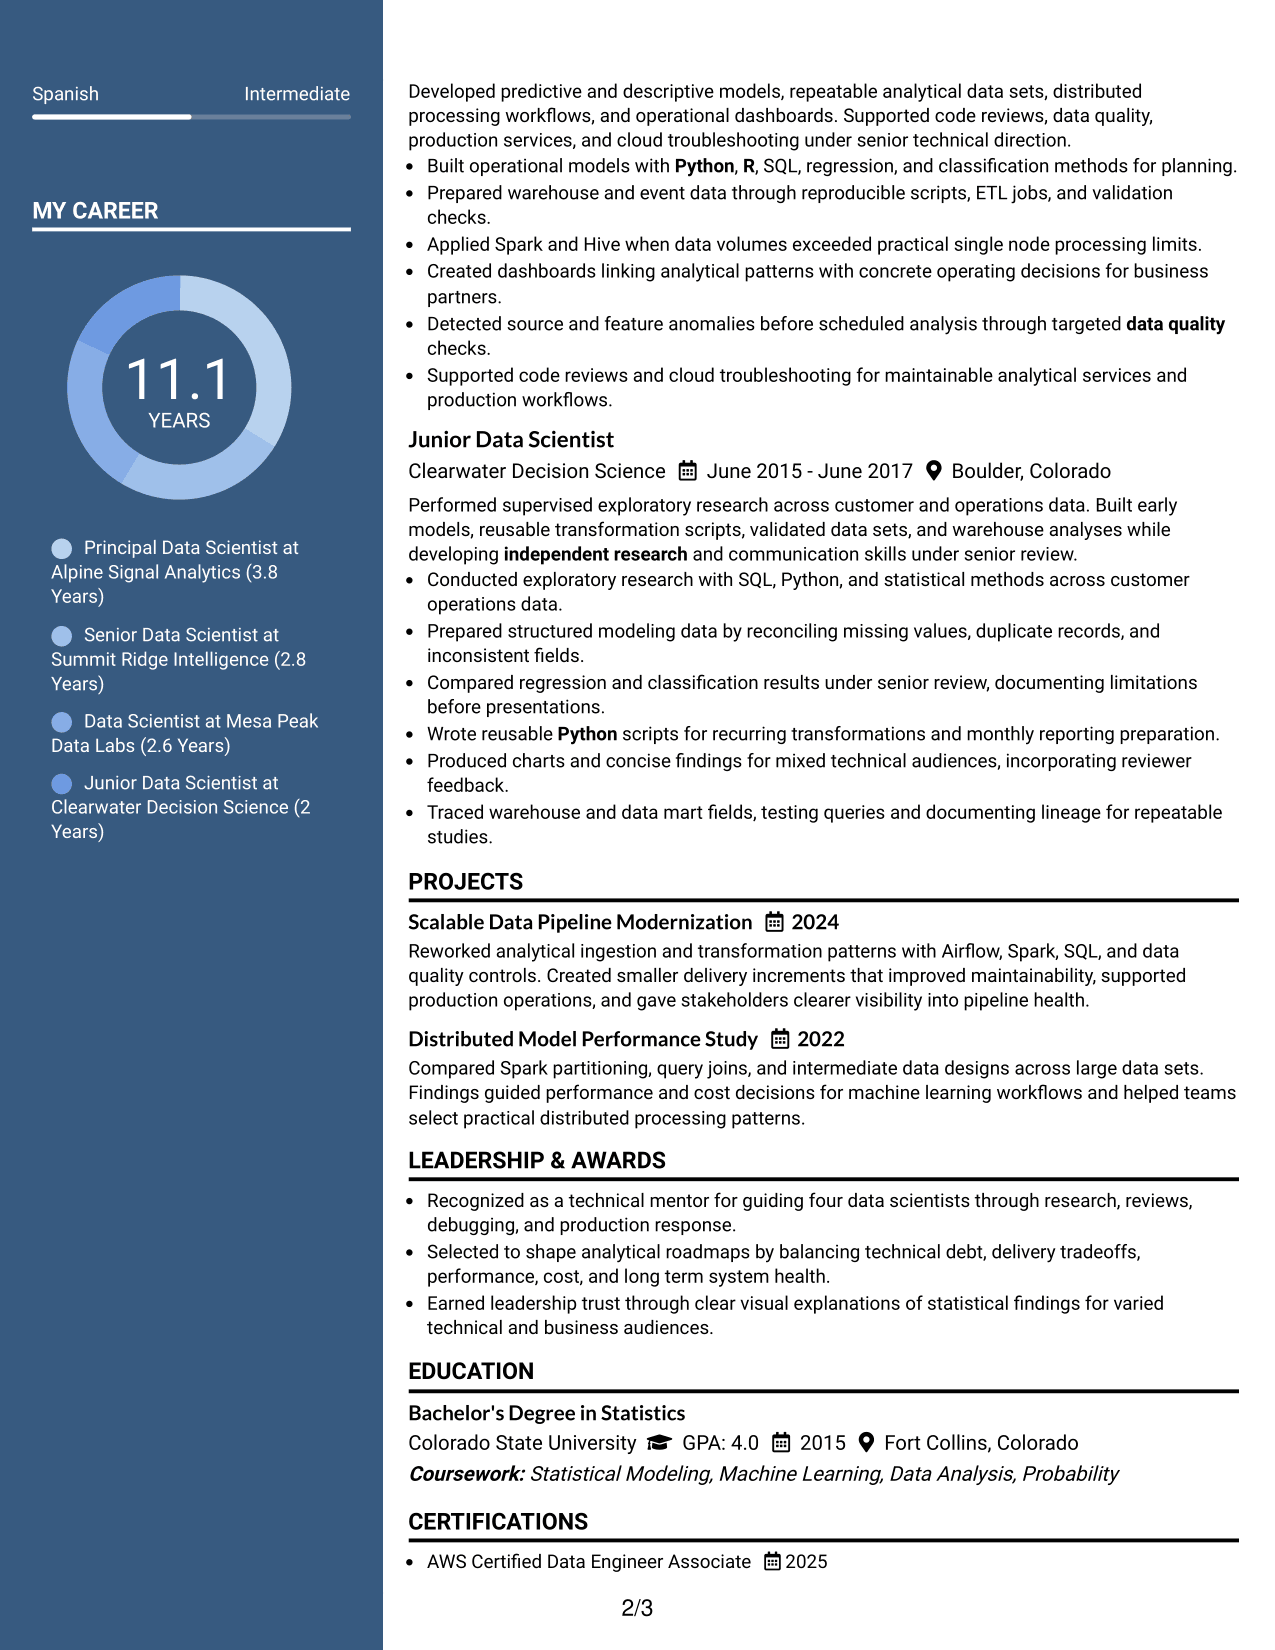
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • Parallel columns let experience and supporting qualifications share space without merging sections.
  • Section grouping helps reviewers compare achievements with skills and education efficiently.
  • Balanced content areas suit resumes with substantial experience and several supporting categories.

Best For

  • Dense professional experience
  • Several supporting resume sections
  • Side-by-side qualification review
  • Balanced technical and career content
  • Compact visual organization
 

#6 Photo Header Two Column Format Resume Example

The Photo Header Two Column Format pairs a photo-based header with two body columns, helping recruiters scan grouped resume content below.
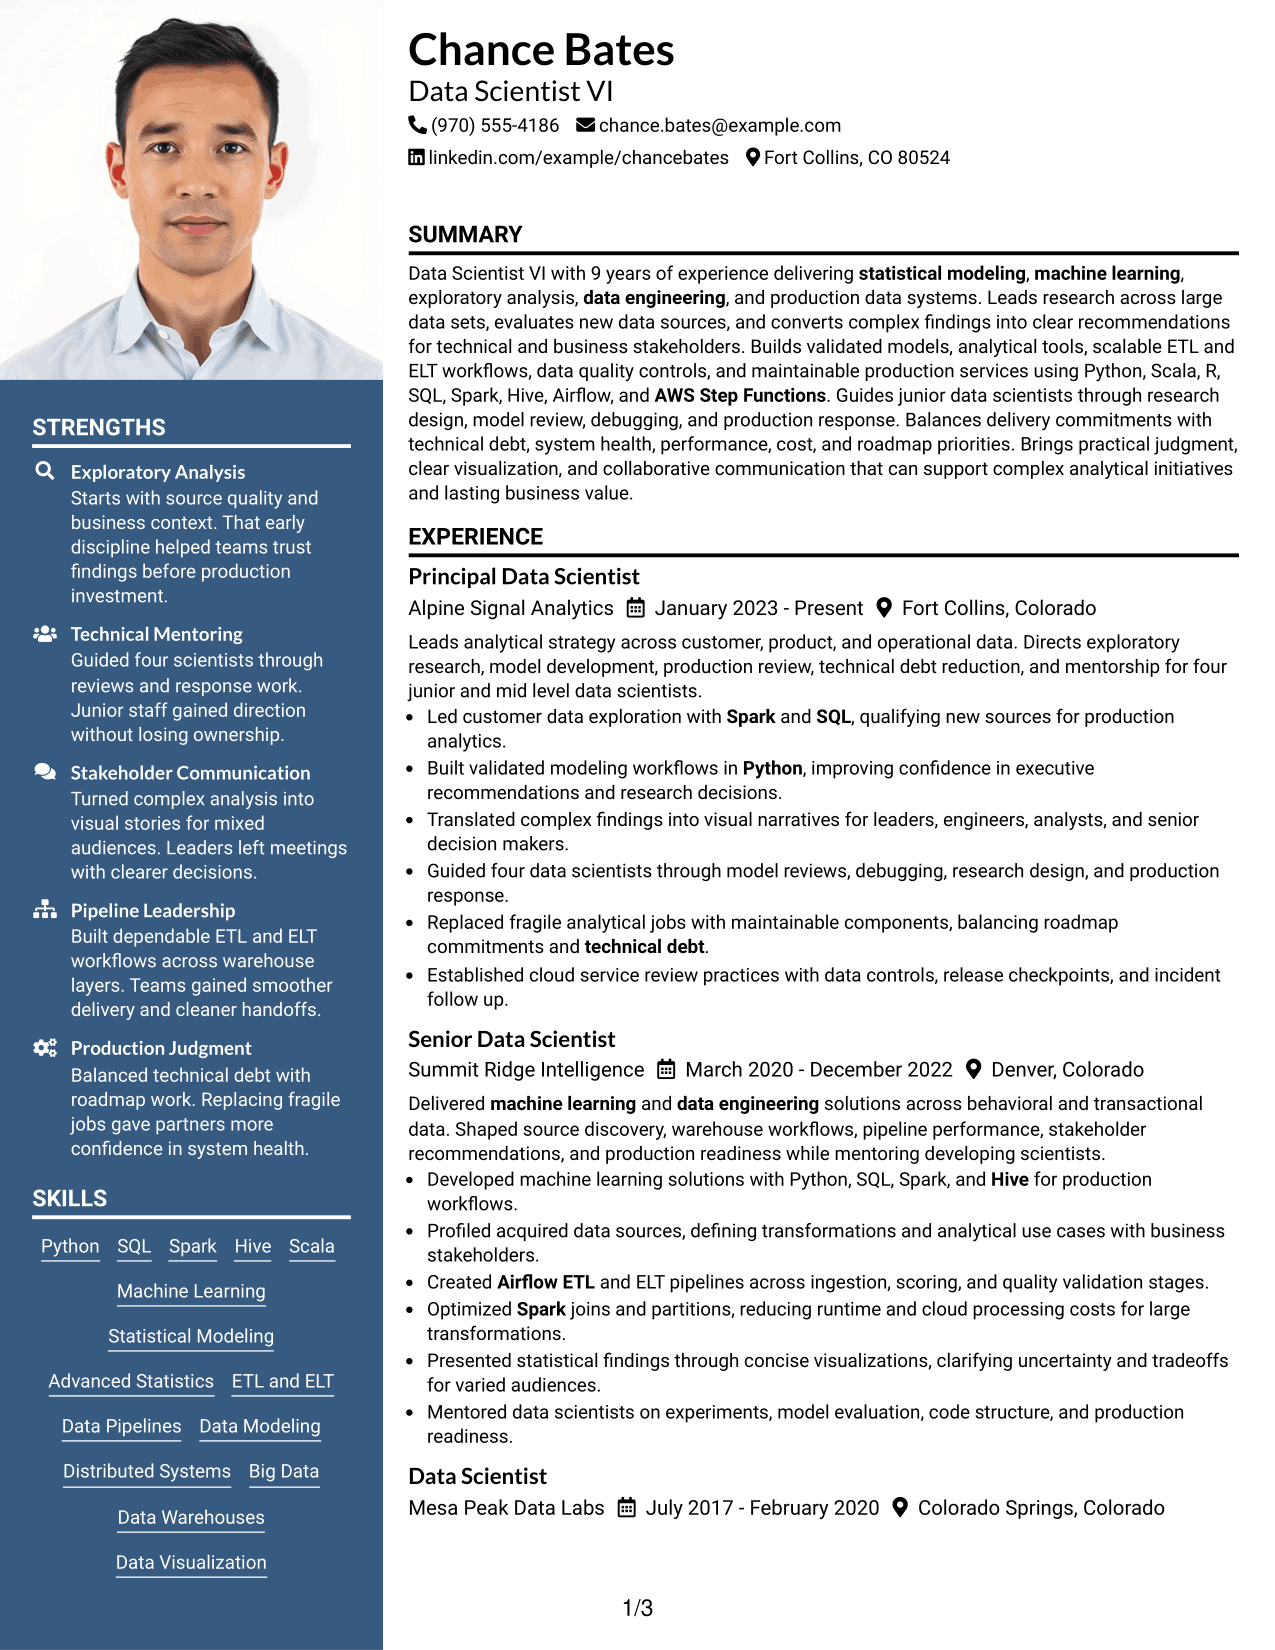
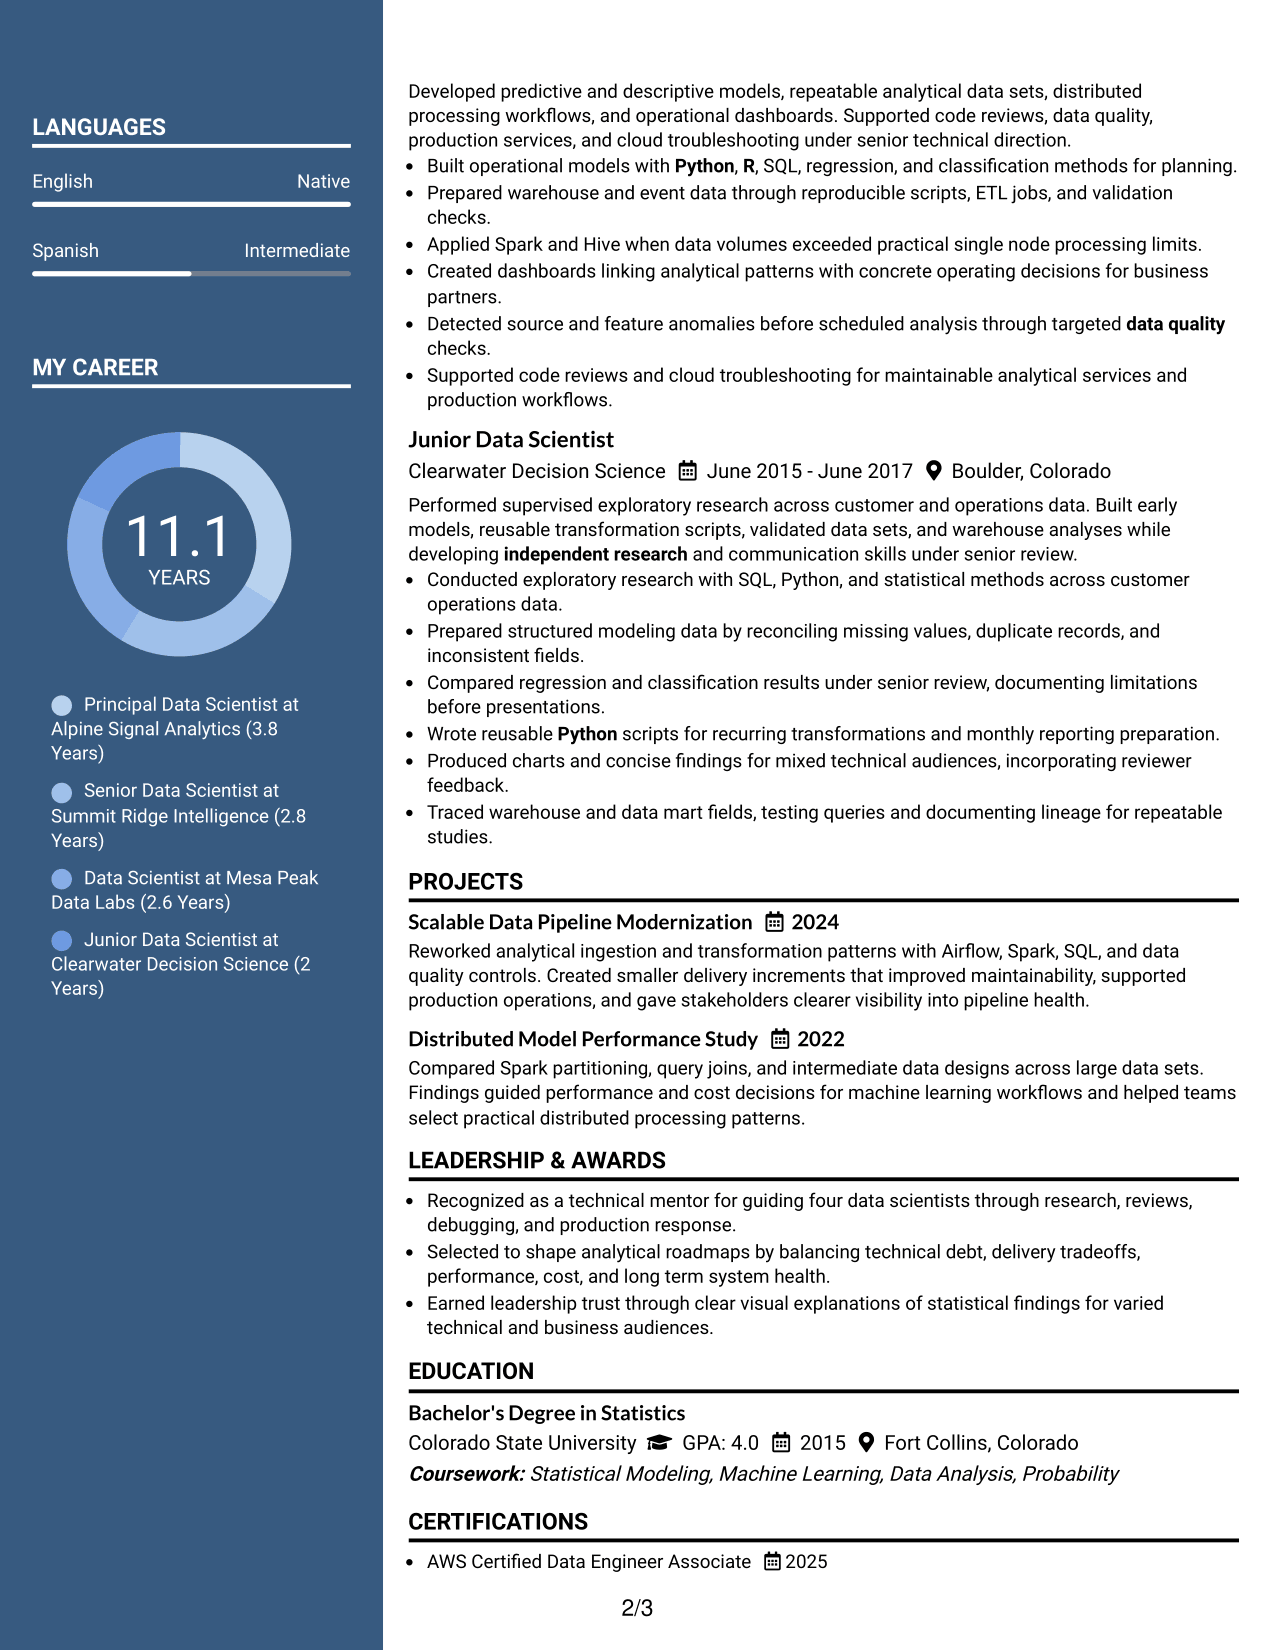
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • Two body columns separate major content groups while keeping experience easy to review.
  • Photo header identifies the person without changing the organization of achievements below.
  • Grouped sections help skills, education, and credentials remain easy to locate.

Best For

  • Markets where resume photos are standard
  • Applications requesting a professional photo
  • Two-column content grouping
  • Resumes with multiple supporting sections
  • Readers scanning both experience and credentials
 

#7 Simple Two Column Format Resume Example

The Simple Two Column Format uses a restrained two-column structure to help recruiters separate core experience from supporting resume sections.
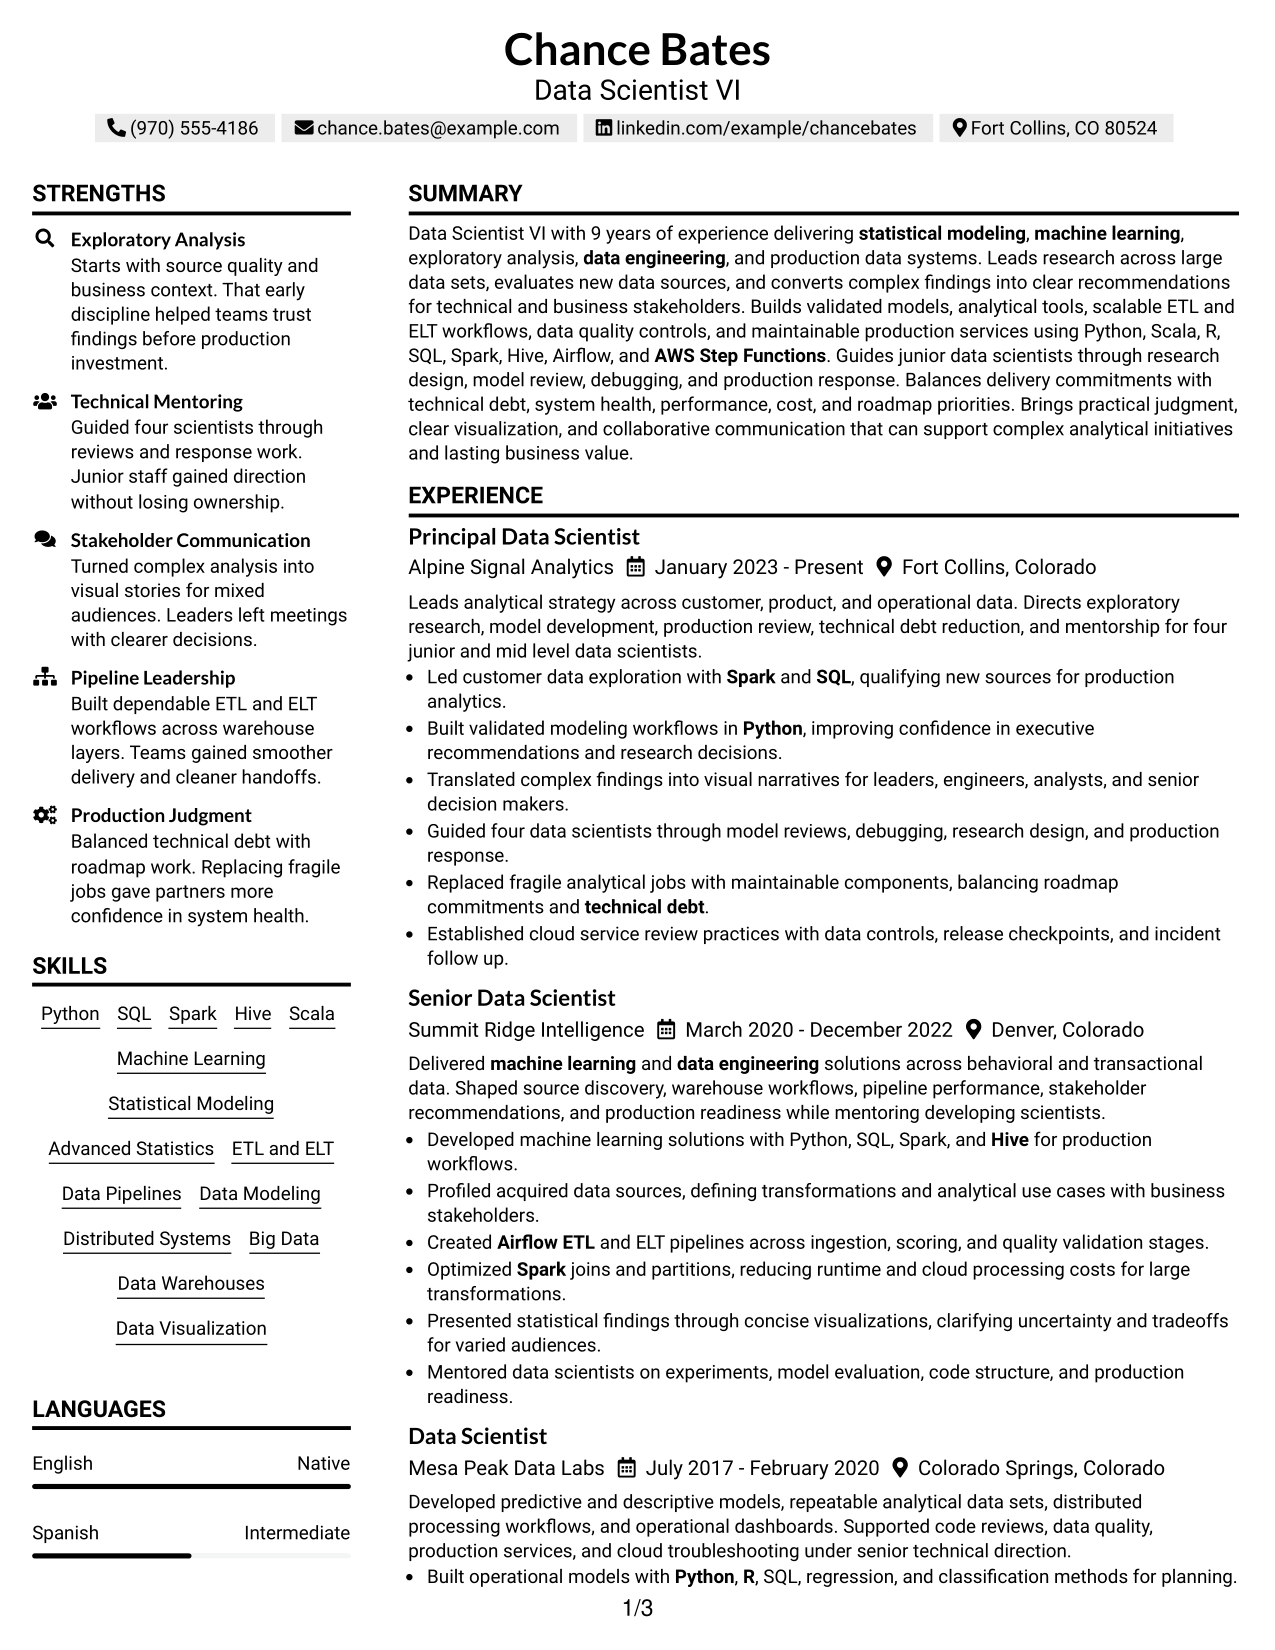
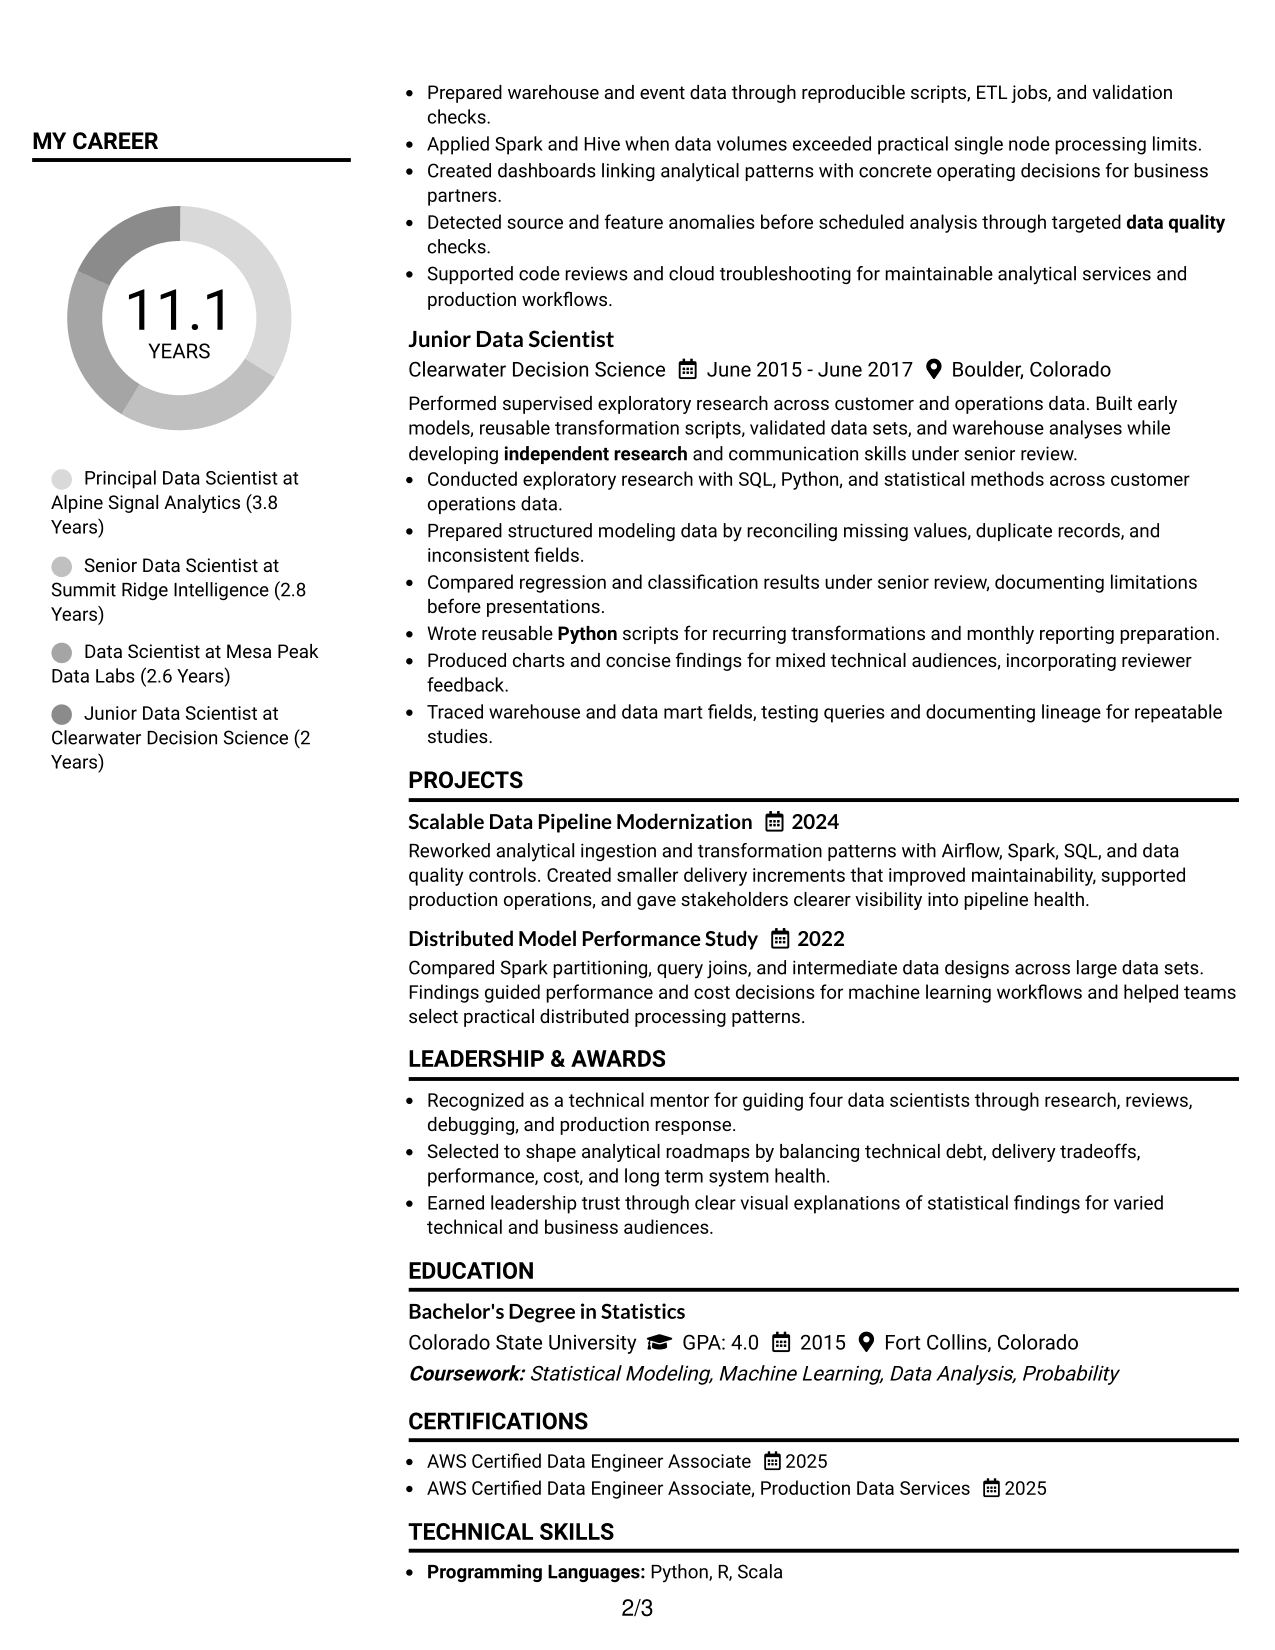
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • Simple column division keeps experience prominent while supporting sections stay easy to scan.
  • Separate content areas reduce crowding between achievements, skills, education, and credentials.
  • Clear two-column hierarchy helps reviewers move between career evidence and supporting information.

Best For

  • Clean two-column organization
  • Experience with broad supporting details
  • Fast section-to-section scanning
  • Mixed career and technical evidence
  • Applications favoring restrained design


Why Build Your Data Scientist VI Resume with ResumeInMinutes

ResumeInMinutes helps you turn complex analytical and technical work into a resume with clear sections, concise bullets, and role-focused keywords.

  • ATS-friendly section structure
  • Keyword-focused resume content
  • Experience and achievement organization
  • Skills and tools grouping
  • Free PDF resume previews
  • Resume customization support

You can use the builder to refine your summary, experience, projects, education, certifications, and technical skills while keeping the document readable for both recruiters and technical reviewers.


See Also


Frequently Asked Questions

Are these Data Scientist VI resume templates ATS-friendly?

Yes. The layouts use clear headings and standard resume sections that support straightforward parsing. Your results still depend on using accurate text, relevant keywords, and simple formatting.

Are these different resumes?

No. This guide shows one complete Data Scientist VI resume in different visual formats so you can compare structure without changing the underlying qualifications.

What should a Data Scientist VI resume include?

Include a focused summary, relevant experience, technical skills, education, projects, certifications, and strong evidence of advanced analysis, model development, data engineering, production work, and technical guidance.

Which keywords are useful for a Data Scientist VI resume?

Use terms that are true for your background and match the role, such as statistical modeling, machine learning, Python, R, Scala, SQL, Spark, Hive, ETL, ELT, data quality, data modeling, distributed systems, and production operations.

How should I show senior-level data science work?

Use concise bullets that explain the problem, your technical action, and the result. Show independent analysis, production responsibility, stakeholder communication, mentoring, technical debt decisions, and system health when those points are supported by your experience.

Should I include projects if I already have extensive experience?

Projects can still help when they show work that is especially relevant to the target role. Keep them brief and use them to add evidence that is not already clear in the experience section.

Should I include a photo on my resume?

For U.S. applications, a no-photo resume is usually the safer choice. Use a photo only when it is appropriate for the country, region, or application context.

Can I customize these resume templates?

Yes. You can adjust the resume text, section order, design style, and PDF format while keeping the content aligned with the Data Scientist VI role.
ATS score 80%

How we calculate this score

  • Keywords: 60% of the total. AI extracts keywords from your job description. If you do not provide one, a standard job description for the title matching your resume is used. This is not a match to a specific vacancy.
  • Text-based resume: 20%. The text resume assessed here receives 100 for this part.
  • Resume quality: 20%. We start at 100 and subtract points for issues found by our resume checks, down to a minimum of zero.
  • Keyword coverage = 100 × (confirmed matches + 0.8 × possible matches) ÷ total keywords, rounded and capped at 100. Possible matches still need checking. Saved generation audits use their saved keyword percentage.
  • Final score = 60% of keyword coverage + 20% of the text score + 20% of the quality score, rounded to a whole number. Without keywords, no overall ATS score is available.

What this score means

Our scores are estimates, not employer ratings. They may contain errors and do not guarantee accurate parsing, a ranking, an interview, or a job. Check your document against the employer’s requirements. You are responsible for relying on this score.

Terms and Conditions

Score weights: Keywords 60% · Text based resume 20% · Resume quality 20%

Live keyword match: 32 of 48 (67%) · Resume quality: 100%

Resume quality 100% · Weight 20% · Issues (0)

Details
  • ✓Name present: Chance Bates
  • ✓Email format: chance.bates@example.com
  • ✓Phone format: (970) 555-4186
  • ✓Experience 1: Job title: Principal Data Scientist
  • ✓Experience 1: Company name: Alpine Signal Analytics
  • ✓Experience 1: Employment dates: January 2023 - Present
  • ✓Experience 1: Description or achievements: Present
  • ✓Experience 2: Job title: Senior Data Scientist
  • ✓Experience 2: Company name: Summit Ridge Intelligence
  • ✓Experience 2: Employment dates: March 2020 - December 2022
  • ✓Experience 2: Description or achievements: Present
  • ✓Experience 3: Job title: Data Scientist
  • ✓Experience 3: Company name: Mesa Peak Data Labs
  • ✓Experience 3: Employment dates: July 2017 - February 2020
  • ✓Experience 3: Description or achievements: Present
  • ✓Experience 4: Job title: Junior Data Scientist
  • ✓Experience 4: Company name: Clearwater Decision Science
  • ✓Experience 4: Employment dates: June 2015 - June 2017
  • ✓Experience 4: Description or achievements: Present
  • ✓No placeholder fields
  • ✓No repeated achievement bullets
  • ✓No empty bullets

No issues found by the current checks.

Text Based Resume 100% · Weight 20%

Parsed text
Chance Bates
(970) 555-4186
chance.bates@example.com
linkedin.com/example/chancebates
Fort Collins, CO 80524
SUMMARY
Data Scientist VI with 9 years of experience delivering statistical modeling, machine learning, exploratory analysis, data engineering, and production data systems. Leads research across large data sets, evaluates new data sources, and converts complex findings into clear recommendations for technical and business stakeholders. Builds validated models, analytical tools, scalable ETL and ELT workflows, data quality controls, and maintainable production services using Python, Scala, R, SQL, Spark, Hive, Airflow, and AWS Step Functions. Guides junior data scientists through research design, model review, debugging, and production response. Balances delivery commitments with technical debt, system health, performance, cost, and roadmap priorities. Brings practical judgment, clear visualization, and collaborative communication that can support complex analytical initiatives and lasting business value.
EXPERIENCE
Principal Data Scientist
Alpine Signal Analytics
January 2023 - Present
Fort Collins, Colorado
Leads analytical strategy across customer, product, and operational data. Directs exploratory research, model development, production review, technical debt reduction, and mentorship for four junior and mid level data scientists.
Led customer data exploration with Spark and SQL, qualifying new sources for production analytics.
Built validated modeling workflows in Python, improving confidence in executive recommendations and research decisions.
Translated complex findings into visual narratives for leaders, engineers, analysts, and senior decision makers.
Guided four data scientists through model reviews, debugging, research design, and production response.
Replaced fragile analytical jobs with maintainable components, balancing roadmap commitments and technical debt.
Established cloud service review practices with data controls, release checkpoints, and incident follow up.
Senior Data Scientist
Summit Ridge Intelligence
March 2020 - December 2022
Denver, Colorado
Delivered machine learning and data engineering solutions across behavioral and transactional data. Shaped source discovery, warehouse workflows, pipeline performance, stakeholder recommendations, and production readiness while mentoring developing scientists.
Developed machine learning solutions with Python, SQL, Spark, and Hive for production workflows.
Profiled acquired data sources, defining transformations and analytical use cases with business stakeholders.
Created Airflow ETL and ELT pipelines across ingestion, scoring, and quality validation stages.
Optimized Spark joins and partitions, reducing runtime and cloud processing costs for large transformations.
Presented statistical findings through concise visualizations, clarifying uncertainty and tradeoffs for varied audiences.
Mentored data scientists on experiments, model evaluation, code structure, and production readiness.
Data Scientist
Mesa Peak Data Labs
July 2017 - February 2020
Colorado Springs, Colorado
Developed predictive and descriptive models, repeatable analytical data sets, distributed processing workflows, and operational dashboards. Supported code reviews, data quality, production services, and cloud troubleshooting under senior technical direction.
Built operational models with Python, R, SQL, regression, and classification methods for planning.
Prepared warehouse and event data through reproducible scripts, ETL jobs, and validation checks.
Applied Spark and Hive when data volumes exceeded practical single node processing limits.
Created dashboards linking analytical patterns with concrete operating decisions for business partners.
Detected source and feature anomalies before scheduled analysis through targeted data quality checks.
Supported code reviews and cloud troubleshooting for maintainable analytical services and production workflows.
Junior Data Scientist
Clearwater Decision Science
June 2015 - June 2017
Boulder, Colorado
Performed supervised exploratory research across customer and operations data. Built early models, reusable transformation scripts, validated data sets, and warehouse analyses while developing independent research and communication skills under senior review.
Conducted exploratory research with SQL, Python, and statistical methods across customer operations data.
Prepared structured modeling data by reconciling missing values, duplicate records, and inconsistent fields.
Compared regression and classification results under senior review, documenting limitations before presentations.
Wrote reusable Python scripts for recurring transformations and monthly reporting preparation.
Produced charts and concise findings for mixed technical audiences, incorporating reviewer feedback.
Traced warehouse and data mart fields, testing queries and documenting lineage for repeatable studies.
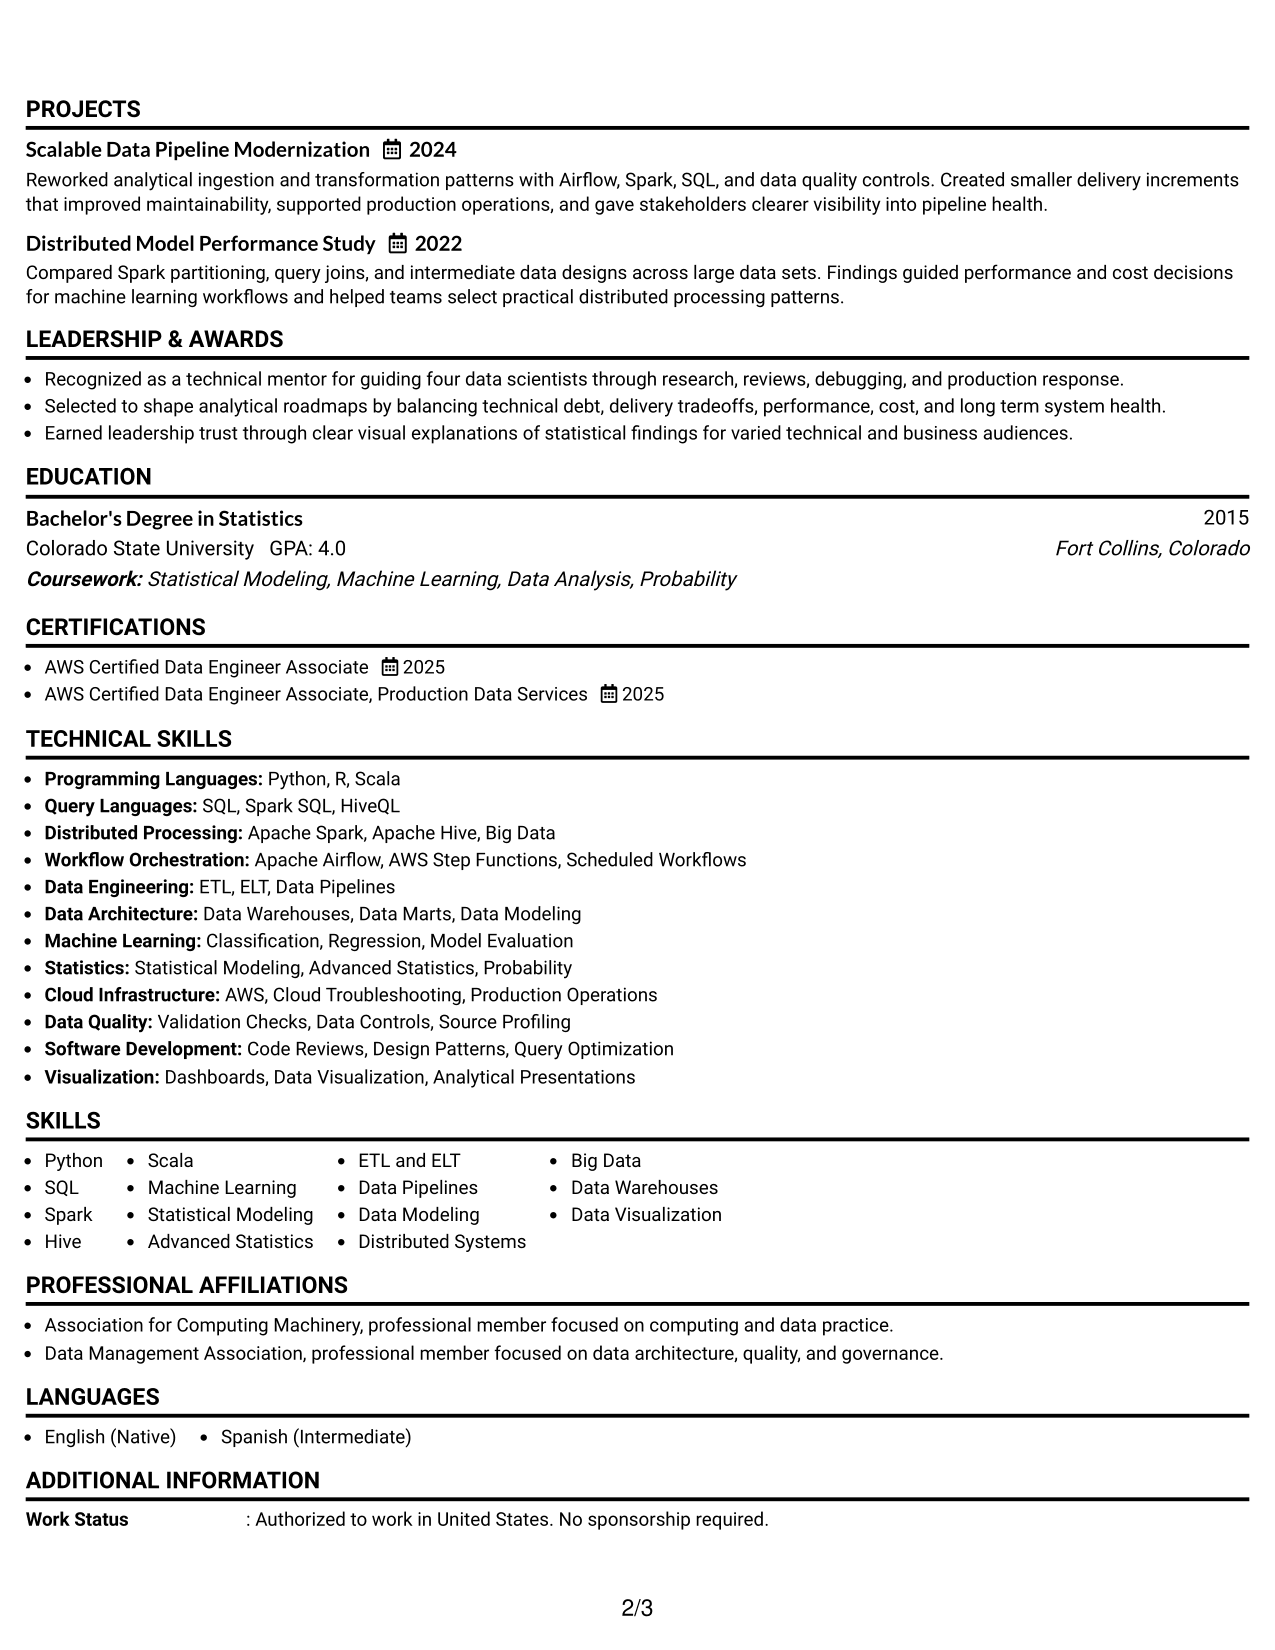
PROJECTS
Scalable Data Pipeline Modernization
2024
Reworked analytical ingestion and transformation patterns with Airflow, Spark, SQL, and data quality controls. Created smaller delivery increments that improved maintainability, supported production operations, and gave stakeholders clearer visibility into pipeline health.
Distributed Model Performance Study
2022
Compared Spark partitioning, query joins, and intermediate data designs across large data sets. Findings guided performance and cost decisions for machine learning workflows and helped teams select practical distributed processing patterns.
LEADERSHIP & AWARDS
Recognized as a technical mentor for guiding four data scientists through research, reviews, debugging, and production response.
Selected to shape analytical roadmaps by balancing technical debt, delivery tradeoffs, performance, cost, and long term system health.
Earned leadership trust through clear visual explanations of statistical findings for varied technical and business audiences.
EDUCATION
Bachelor's Degree in Statistics
Colorado State University
GPA: 4.0
2015
Fort Collins, Colorado
Coursework: Statistical Modeling, Machine Learning, Data Analysis, Probability
CERTIFICATIONS
AWS Certified Data Engineer Associate
2025
AWS Certified Data Engineer Associate, Production Data Services
2025
TECHNICAL SKILLS
Programming Languages: Python, R, Scala
Query Languages: SQL, Spark SQL, HiveQL
Distributed Processing: Apache Spark, Apache Hive, Big Data
Workflow Orchestration: Apache Airflow, AWS Step Functions, Scheduled Workflows
Data Engineering: ETL, ELT, Data Pipelines
Data Architecture: Data Warehouses, Data Marts, Data Modeling
Machine Learning: Classification, Regression, Model Evaluation
Statistics: Statistical Modeling, Advanced Statistics, Probability
Cloud Infrastructure: AWS, Cloud Troubleshooting, Production Operations
Data Quality: Validation Checks, Data Controls, Source Profiling
Software Development: Code Reviews, Design Patterns, Query Optimization
Visualization: Dashboards, Data Visualization, Analytical Presentations
SKILLS
Python
SQL
Spark
Hive
Scala
Machine Learning
Statistical Modeling
Advanced Statistics
ETL and ELT
Data Pipelines
Data Modeling
Distributed Systems
Big Data
Data Warehouses
Data Visualization
PROFESSIONAL AFFILIATIONS
Association for Computing Machinery, professional member focused on computing and data practice.
Data Management Association, professional member focused on data architecture, quality, and governance.
LANGUAGES
English (Native)
Spanish (Intermediate)
ADDITIONAL INFORMATION
Work Status
: Authorized to work in United States. No sponsorship required.
REFERENCES
AVAILABLE ON REQUEST

Matched keywords (32)

  • Data Scientist VI
  • statistical modeling
  • machine learning
  • Python
  • R
  • Scala
  • SQL
  • Spark
  • Hive
  • data engineering
  • Data Architecture
  • Data Warehouses
  • data mart
  • ETL
  • ELT
  • Airflow
  • AWS Step Functions
  • Data Pipeline
  • Data Modeling
  • Distributed Systems
  • Big Data
  • data quality
  • Data Visualization
  • Cloud Infrastructure
  • production operations
  • Advanced Statistics
  • large data sets
  • Programming
  • technical debt
  • independent research
  • Query Optimization
  • Orchestration

Missing keywords (16)

  • exploratory data analysis
  • model validation
  • software design patterns
  • technical mentoring
  • advanced mathematics
  • machine learning algorithms
  • scripting
  • code synthesis
  • technology roadmaps
  • stakeholder communication
  • statistical techniques
  • performance optimization
  • cost efficiency
  • software development methodologies
  • production software
  • data transformation
Disclaimer: All names, images, contact information, employment histories, achievements, security clearances, military credentials, and other qualifications shown in this content are fictional and used for illustrative purposes only. Any resemblance to actual persons, living or deceased, is purely coincidental.

Resume and cover-letter examples and recommendations in this article reflect general best practices and professional experience and are provided for guidance only. Results may vary based on role, industry, region, and hiring organization.

Content Accuracy and Verification: To the fullest extent permitted by applicable law, we do not represent or warrant that resume or cover-letter guidance, examples, recommendations, or related information are accurate, complete, current, error-free, or suitable for any particular purpose. You are responsible for independently reviewing and verifying the information before relying on it.

ATS and Cover-Letter Scores: ATS scores are estimates calculated using our own formula, informed by publicly available guidance on resume formatting and keyword matching. They are not scores issued or endorsed by an ATS provider or employer. Cover-letter scores are also our own assessments. Parsing, weighting, screening criteria, and results vary between systems, employers, job descriptions, and document formats. No score guarantees successful parsing, a particular ranking, an interview, or employment. Use scores as general guidance and independently check your documents against the employer’s requirements. To the fullest extent permitted by applicable law, we accept no liability for errors in scores or parsing, or losses arising from reliance on these assessments. Nothing in this notice excludes liability or limits consumer rights that cannot lawfully be excluded or limited.

Terms and Conditions
 
> JP 1 1
PDF Footer and Margins Setup
The margins are applied to the document, and the footer shows up in the preview and the PDF

Footer Font Settings

Are you applying for a specific job
so we can tailor your resume to it?
Are you applying for a specific job
so we can tailor your cover letter to it?
Type your details as text to generate a personalized resume Type your details as text to generate a personalized cover letter
Website link found! Ready to create resume from:
Drag the into the box to verify you're human.
Drop here

My Resumes

Displaying {number_of_files} files (out of {total_of_all_files} total)
Name File Type Last Modified: Description:

Rename File

Filename already exists!

Delete Files

Warning: This action is irreversible. Once you click submit, the files will be permanently deleted.

Heading text
Upload From Computer Upload
Select From Existing
LinkedIn
Drag & Drop files anywhere in this tab, or

Uploaded Files

Delete Name Last Updated Use This File
Select this to use the file for generating your resume and cover letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

My Files

Resumes or cover letters you create will appear here. No files available yet.
Delete Name Last Updated Use This File
Select this to use the file for generating your resume and cover letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

Add LinkedIn Profile PDF

You can download your LinkedIn profile as a PDF by opening linkedin.com in a web browser, clicking your profile photo, selecting the “More” or “Resources” button, and choosing “Save to PDF.” You can then attach the PDF using the Upload From Computer tab.

Paste Your LinkedIn Profile Text

If you have copied the LinkedIn profile text, paste it below. See how to copy your profile from LinkedIn

Select this to use the LinkedIn profile text for generating your resume and cover letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

Try these controls

<
>