US English


7 Software Engineer - Query Engines Resume Templates with Example
By Ria · Last Updated On September 29, 2026
Resume Example Page 1

This guide shows you how to build a Software Engineer - Query Engines resume that is clear, focused, and easy to review. You will learn how to organize strong evidence and compare professional resume formats.

Give priority to experience that shows query planning, optimization, execution, distributed processing, storage work, and performance analysis. Use concise bullets, clear section headings, and specific technical terms that match work you can support.

The same complete resume is presented in 7 ATS-friendly layouts so you can compare reading order, section organization, and visual structure. Each example includes format notes and free PDF downloads to help you choose a practical design.

What Makes a Great Software Engineer - Query Engines Resume in 2026

A strong resume makes complex systems work easy to scan. It should show clear experience, focused achievements, relevant skills, and evidence of careful engineering.

Use grounded keywords such as query planning, query optimization, execution engines, distributed processing, Apache DataFusion, Apache Spark, Apache Iceberg, profiling, benchmarking, and regression testing when they match your real work.

The examples shown below are intentionally detailed to demonstrate a range of experiences, skills, accomplishments and relevant keywords. We prefer detailed resumes as they provide more context to the hiring managers and also help the ATS systems identify relevant qualifications and score your resume better for a match. But the length of a resume is an individual choice. If you want a one page resume, just keep the most relevant experience and information for the job. Note: Resume examples are for educational purposes only. Use only information that accurately reflects your experience and qualifications. References to real organizations do not imply affiliation or endorsement.

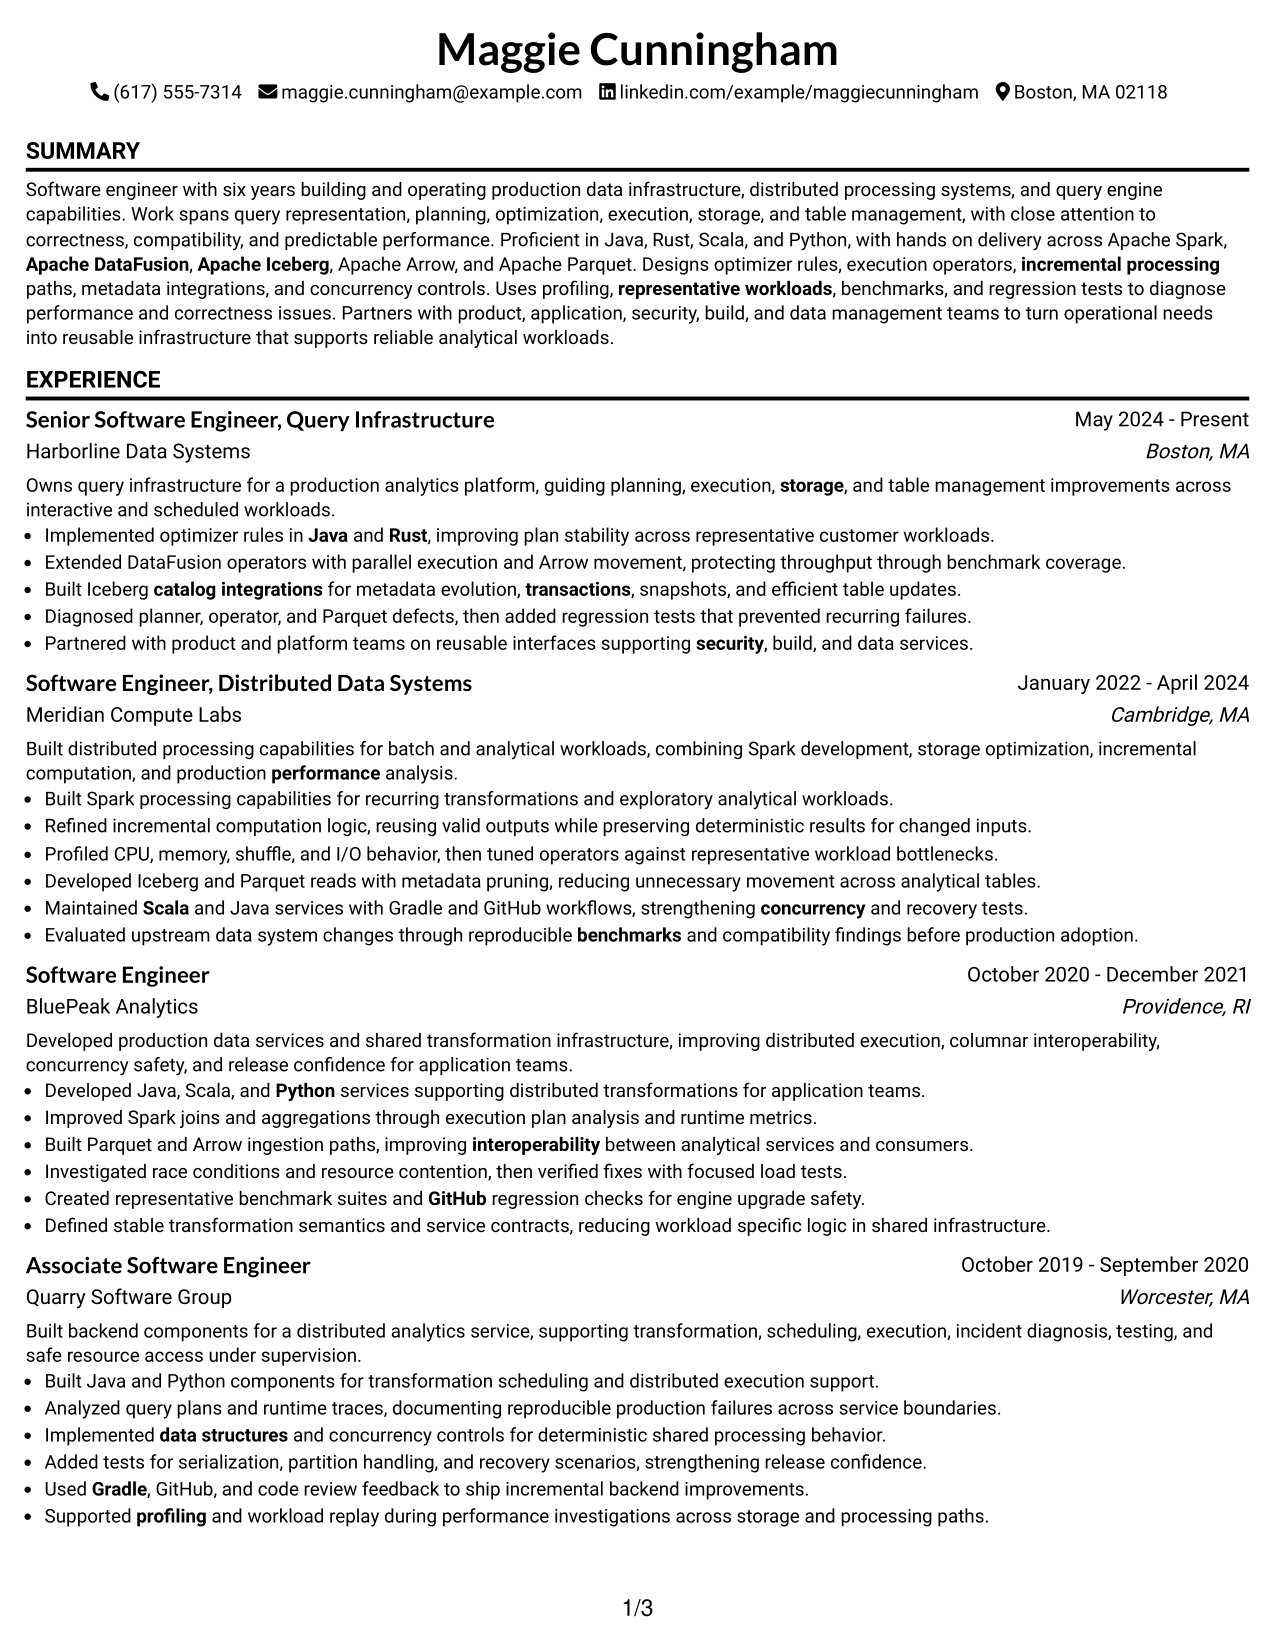
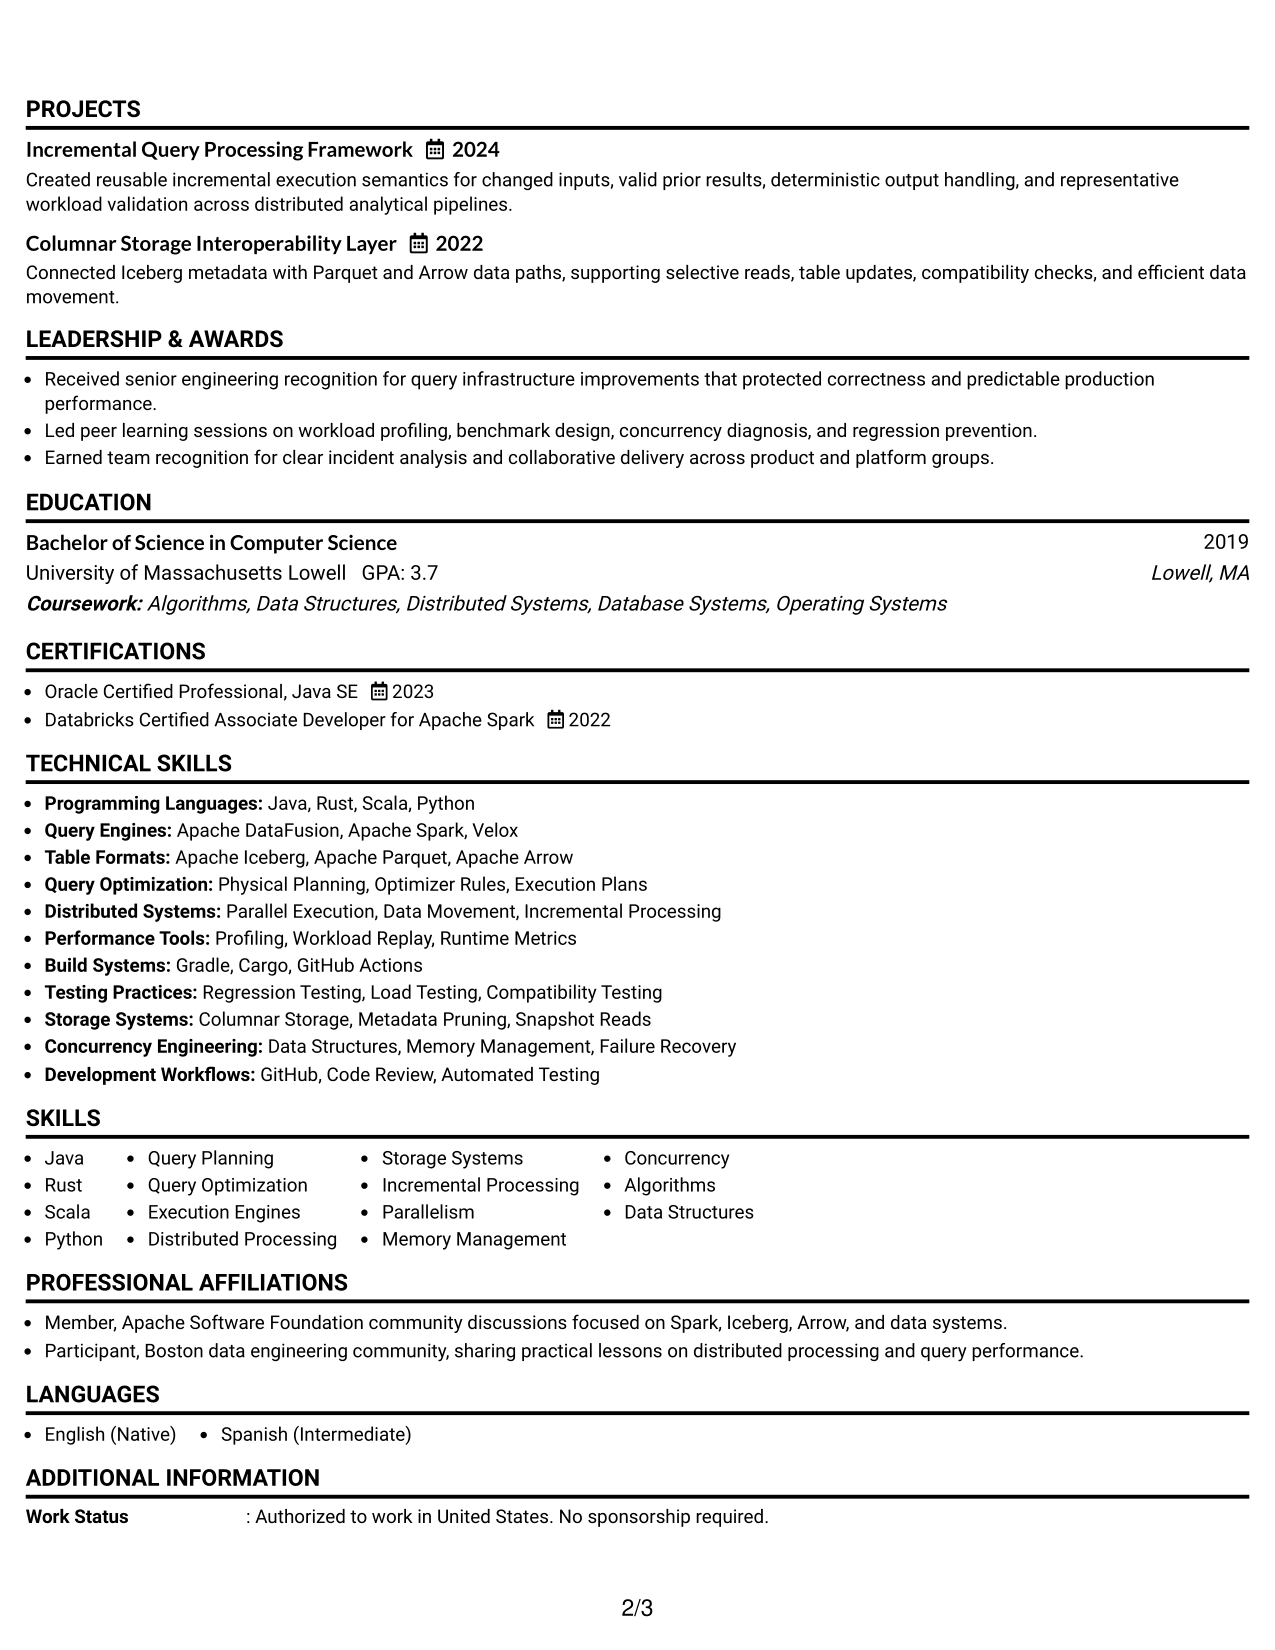
#1 Simple One Column Format Resume Example

A simple one-column reading order helps recruiters move from summary to experience, skills, and credentials without side-to-side scanning.
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • Linear reading keeps career progression and experience easy to follow.
  • Full-width sections give achievement bullets room for clear technical context.
  • Skills, education, and credentials remain distinct without competing side content.

Best For

  • Detailed technical experience
  • Straightforward recruiter scanning
  • Long achievement bullets
  • Clear chronological history
  • ATS-focused applications

Resume Keywords

  • query engine
  • Query Planning
  • Query Optimization
  • Execution Engines
  • Parallelism
  • Memory Management
  • data movement
  • Apache Iceberg
  • catalog integrations
  • transactions
  • interoperability
  • incremental processing
  • correctness
  • performance
  • storage
See all keywords
 

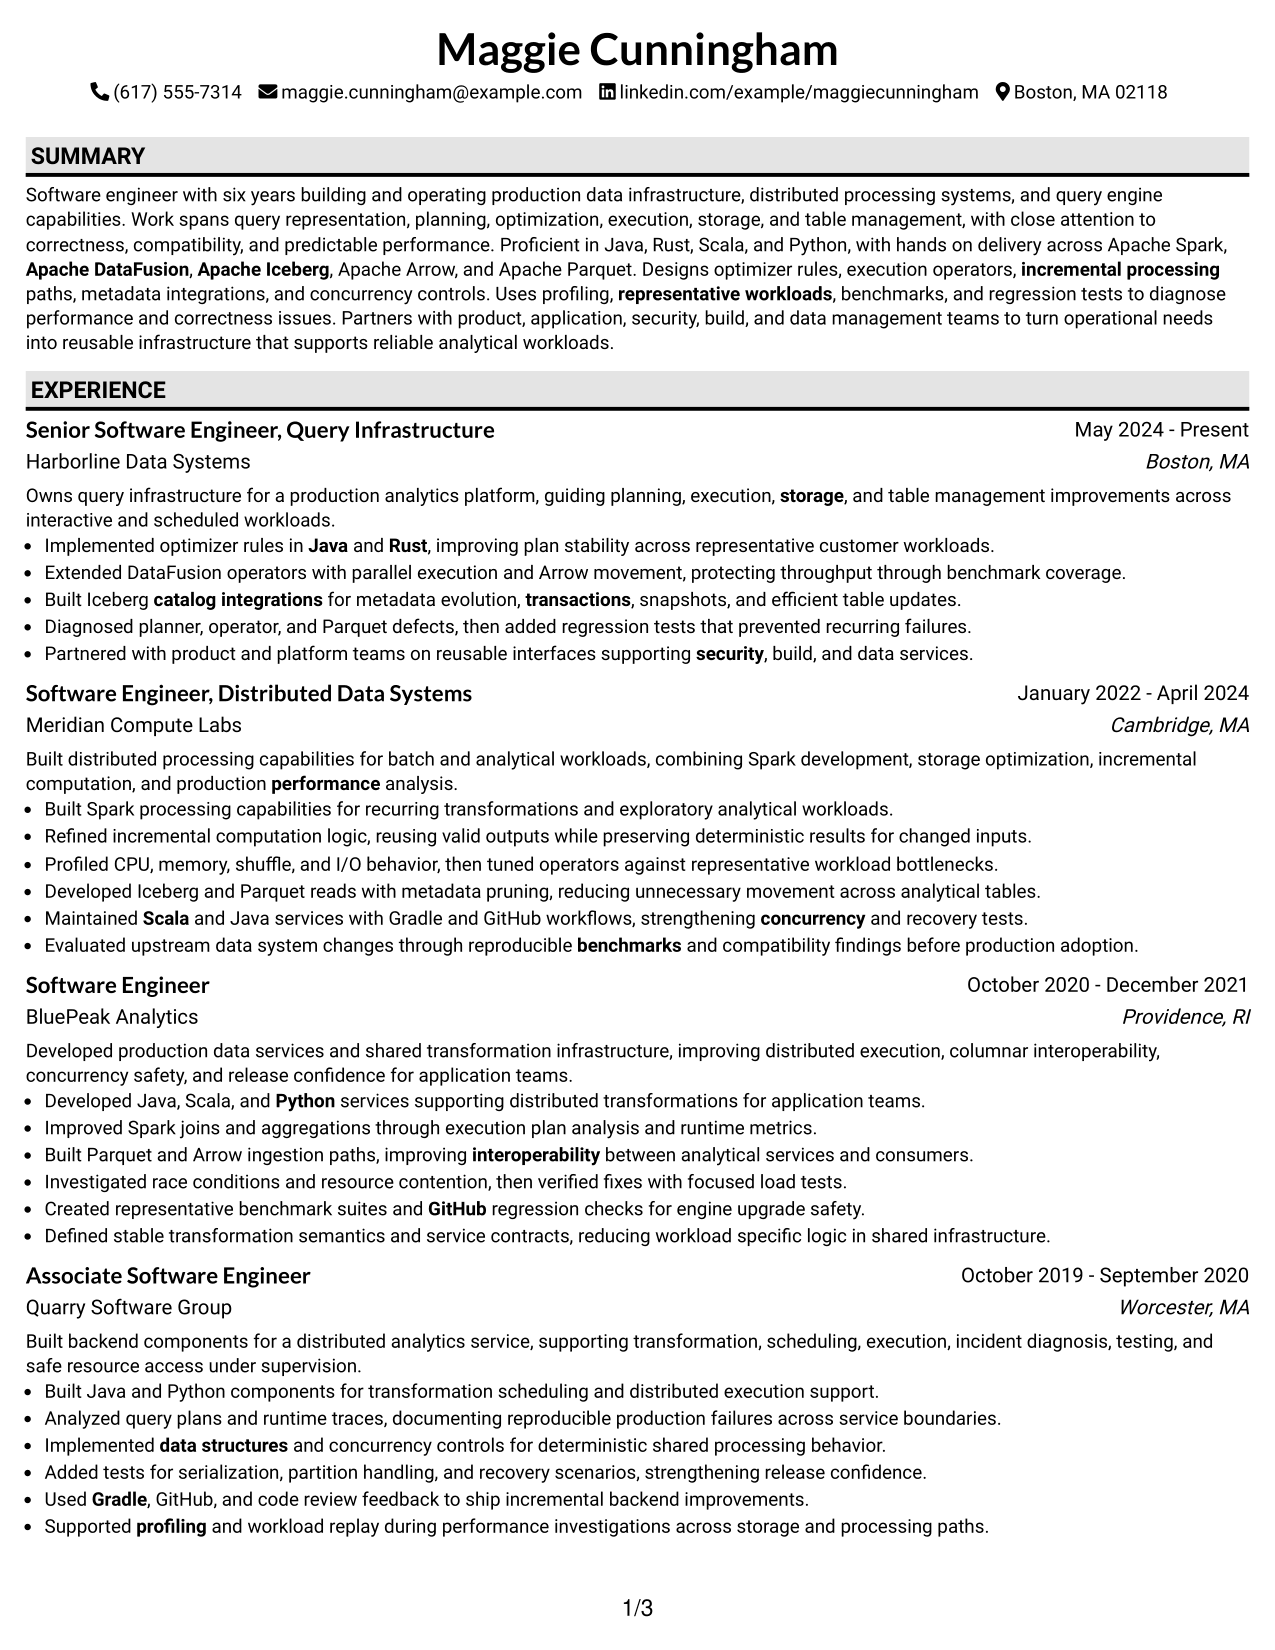
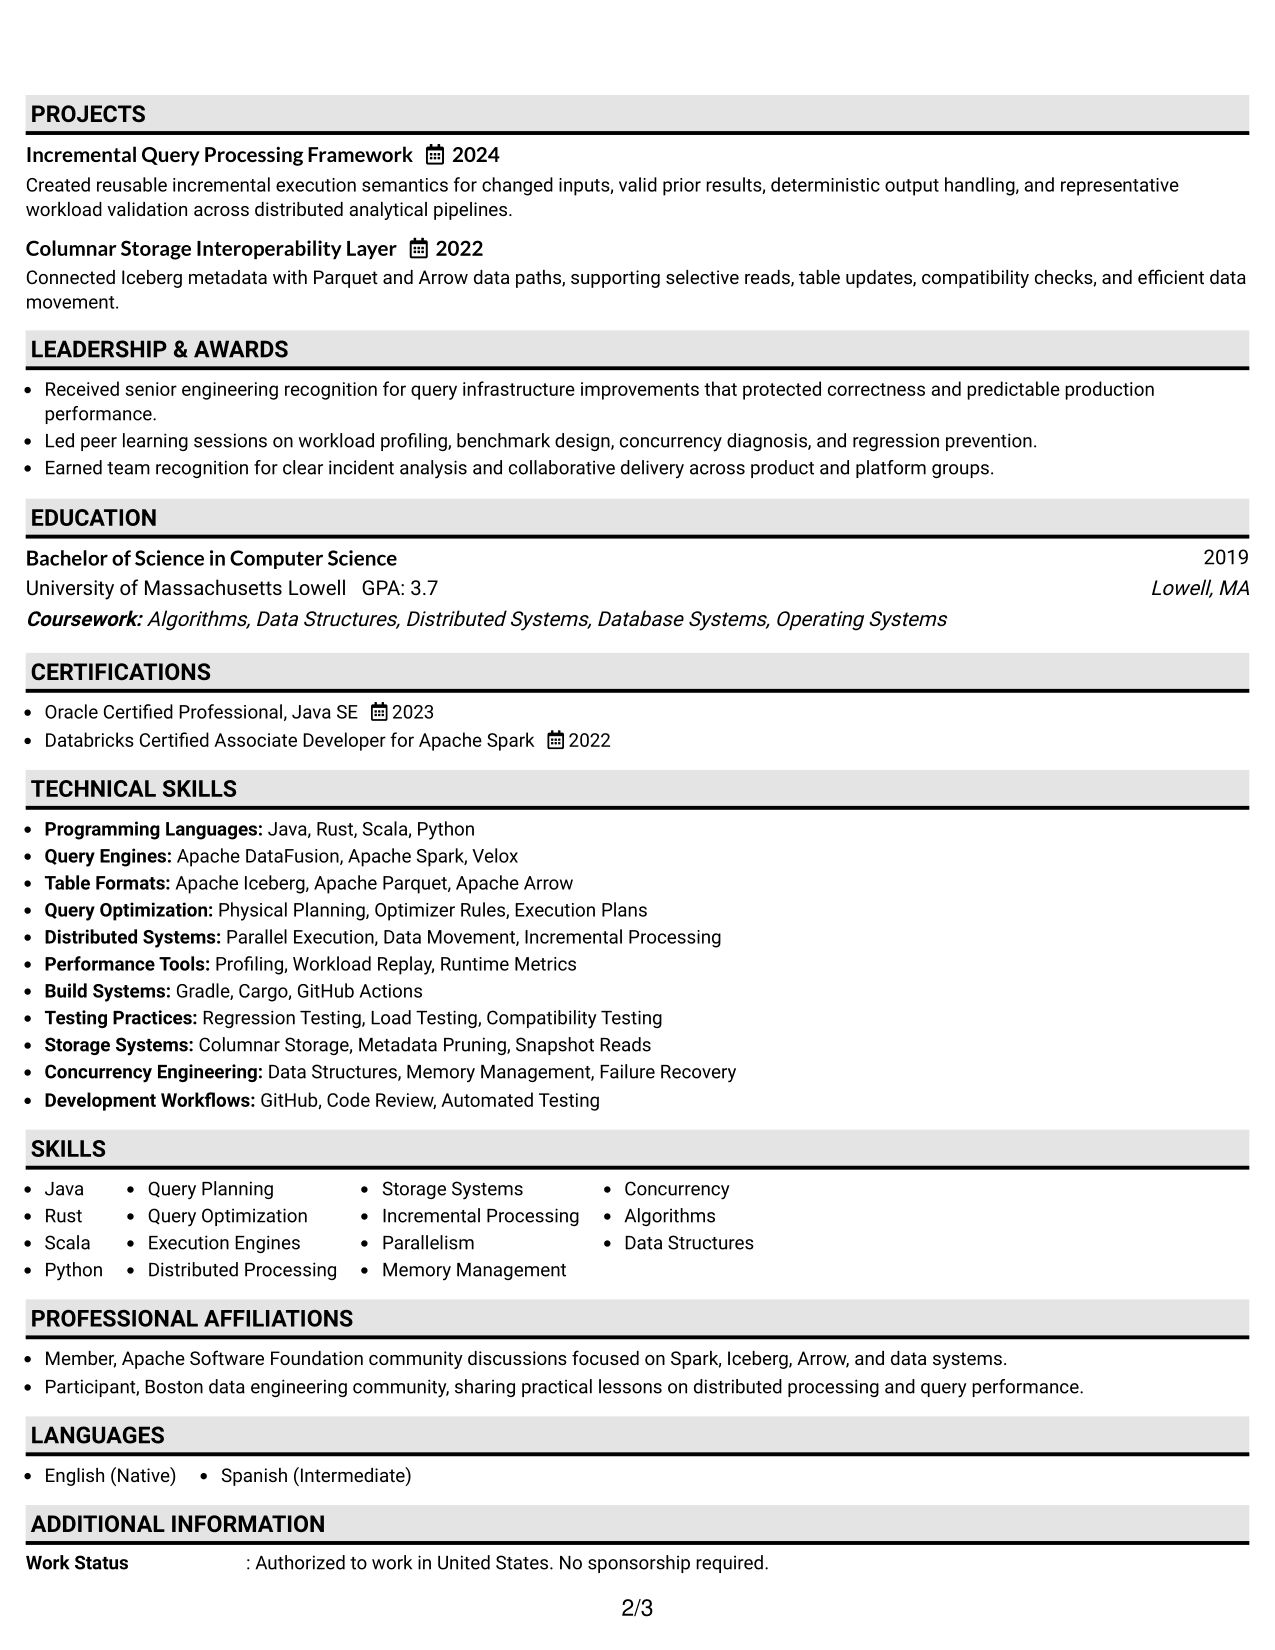
#2 Plain One Column with Shaded Labels Resume Example

Shaded section labels break a one-column resume into clear stops, helping recruiters locate major sections while keeping one reading path.
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • Shaded labels make experience, skills, and education sections easier to locate.
  • One reading path keeps achievements connected to the roles they support.
  • Clear section breaks help credentials stand apart from detailed career history.

Best For

  • Section-heavy technical resumes
  • Readers who value clear labels
  • Mixed experience and project content
  • Visible separation between sections
  • Traditional resume structure
 

#3 One Column Format with Photo Right Resume Example

A right-side profile photo adds a personal header element while the one-column body keeps recruiter scanning direct and sequential.
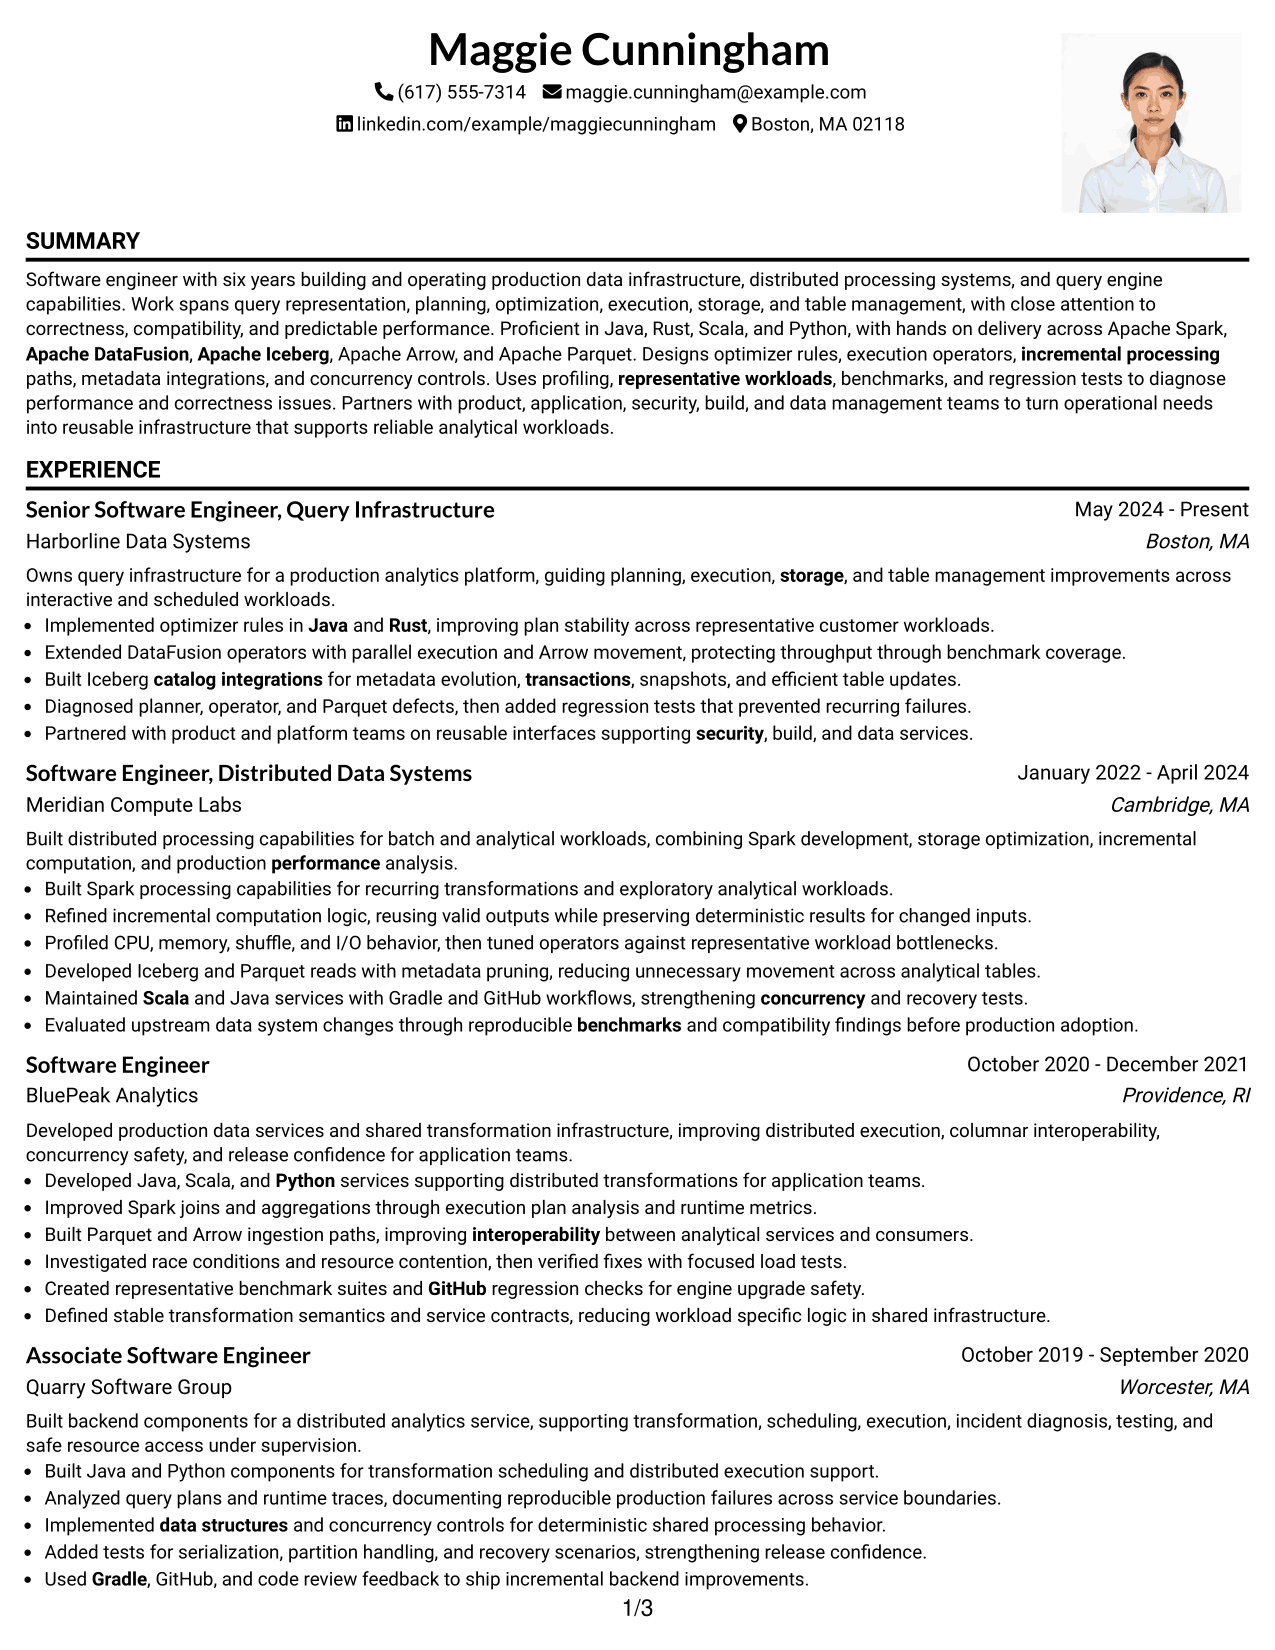
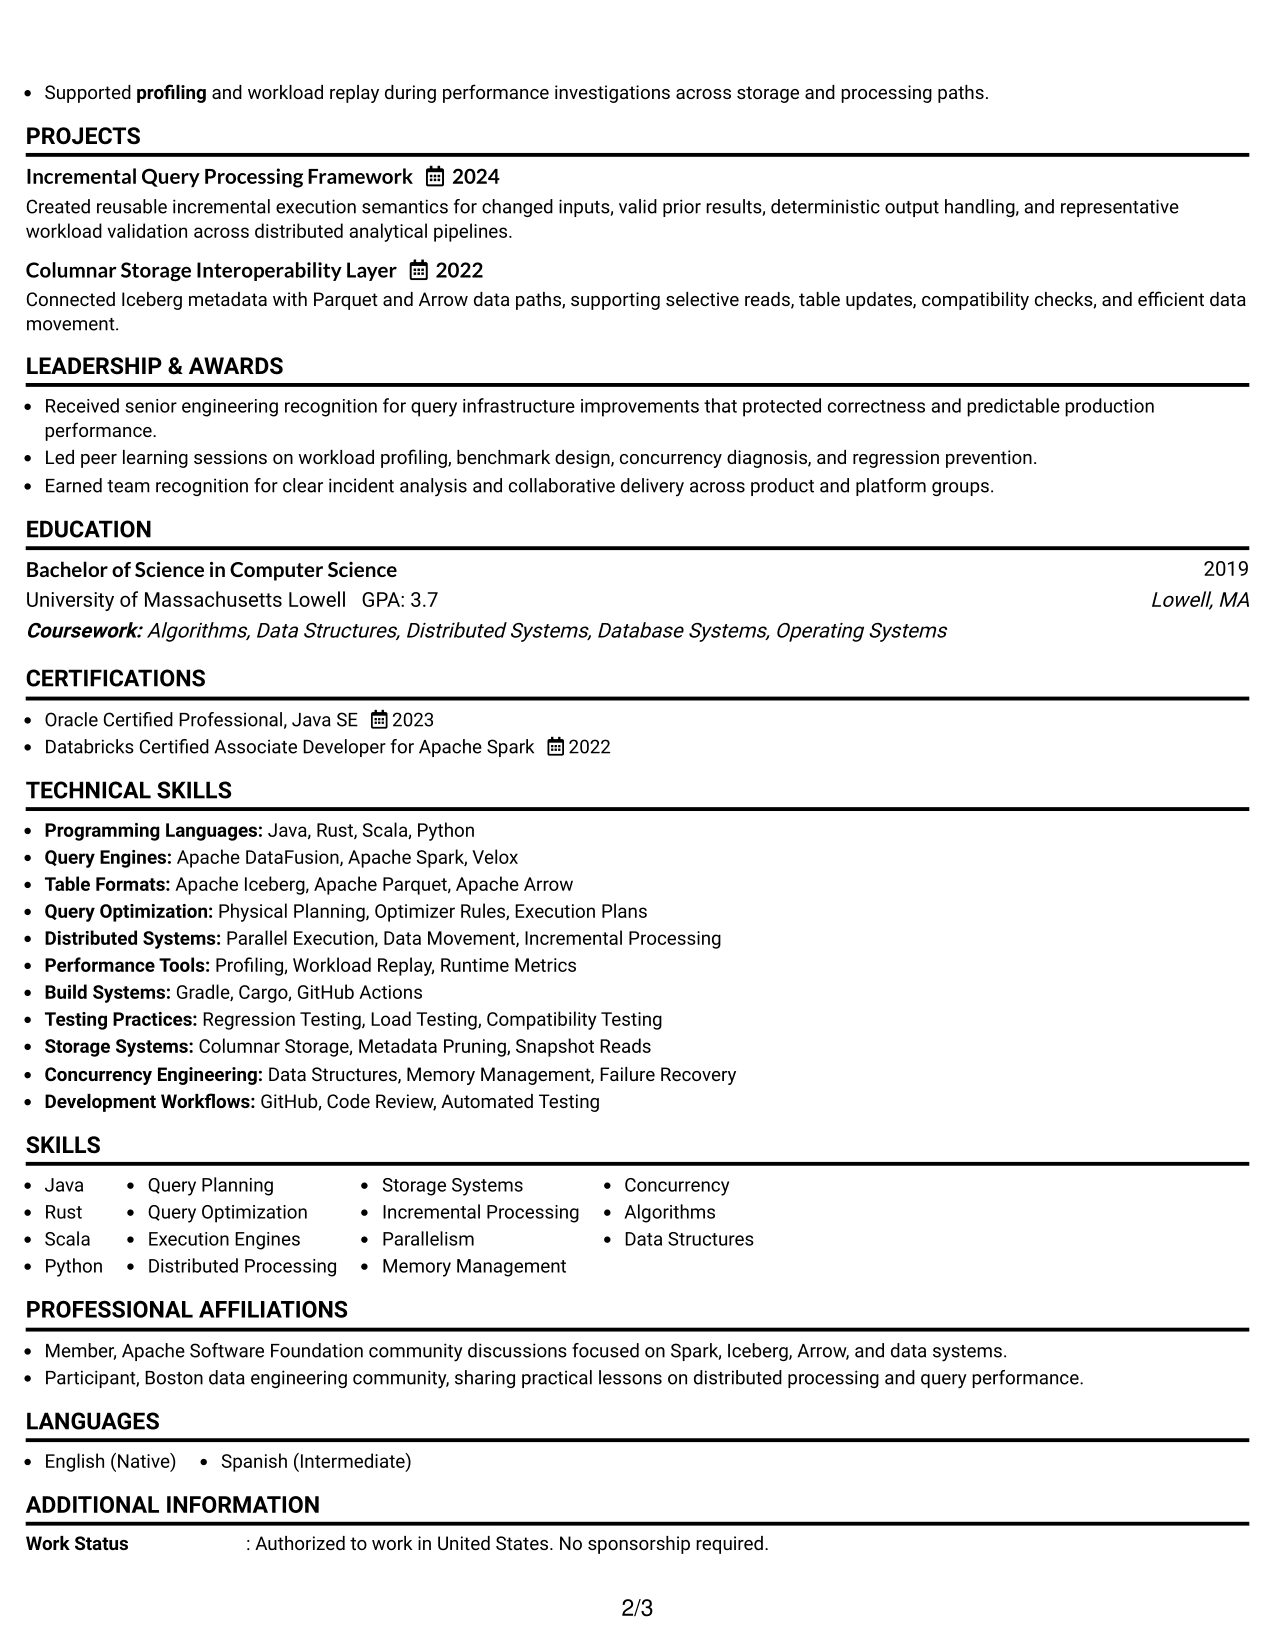
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • Sequential body sections keep experience and achievements in a predictable order.
  • The photo stays in the header, leaving career content in one flow.
  • Separate blocks preserve space for skills, education, and professional credentials.

Best For

  • Markets where resume photos are customary
  • Applications needing one reading path
  • Career histories with detailed bullets
  • Profiles with several credential sections
  • Readers preferring a personal header
 

#4 Clean Two Column Sidebar Format Resume Example

A clean sidebar creates a two-column structure that helps recruiters separate compact supporting details from the main career narrative.
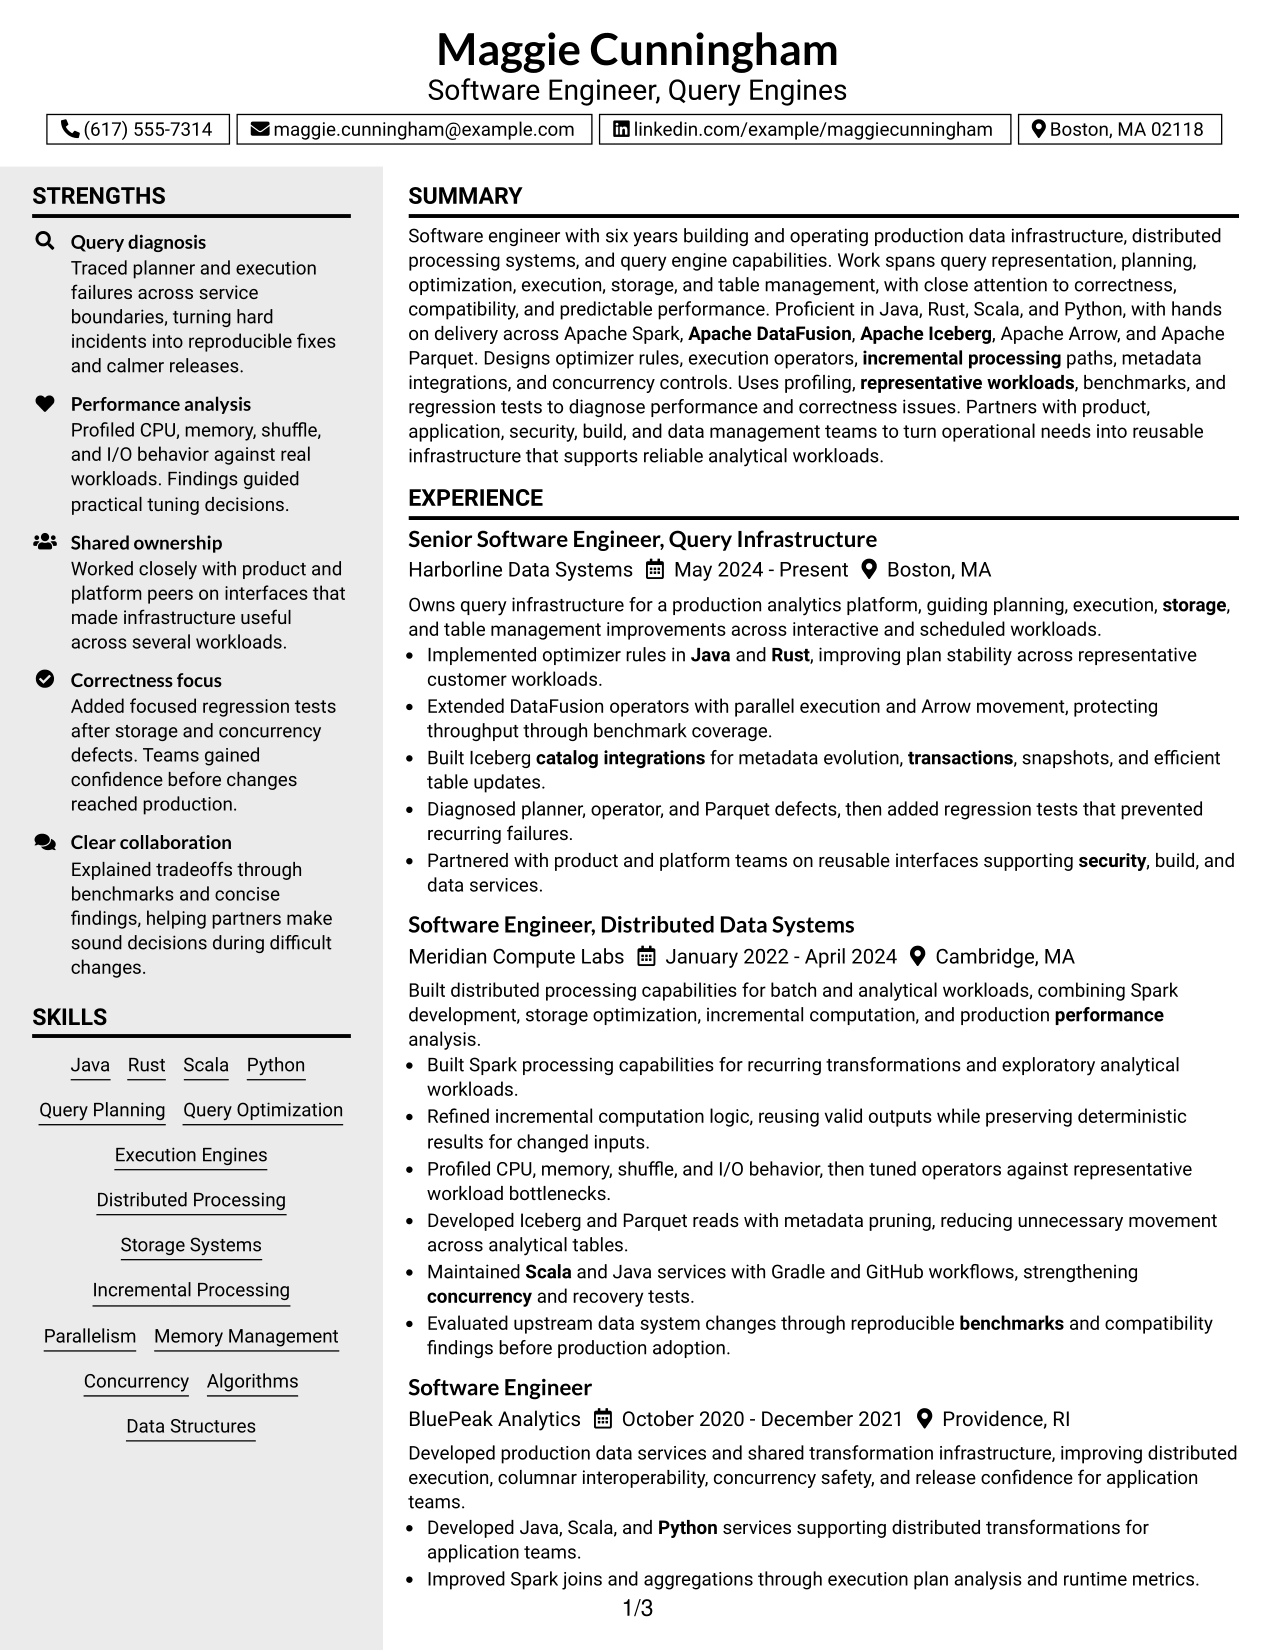
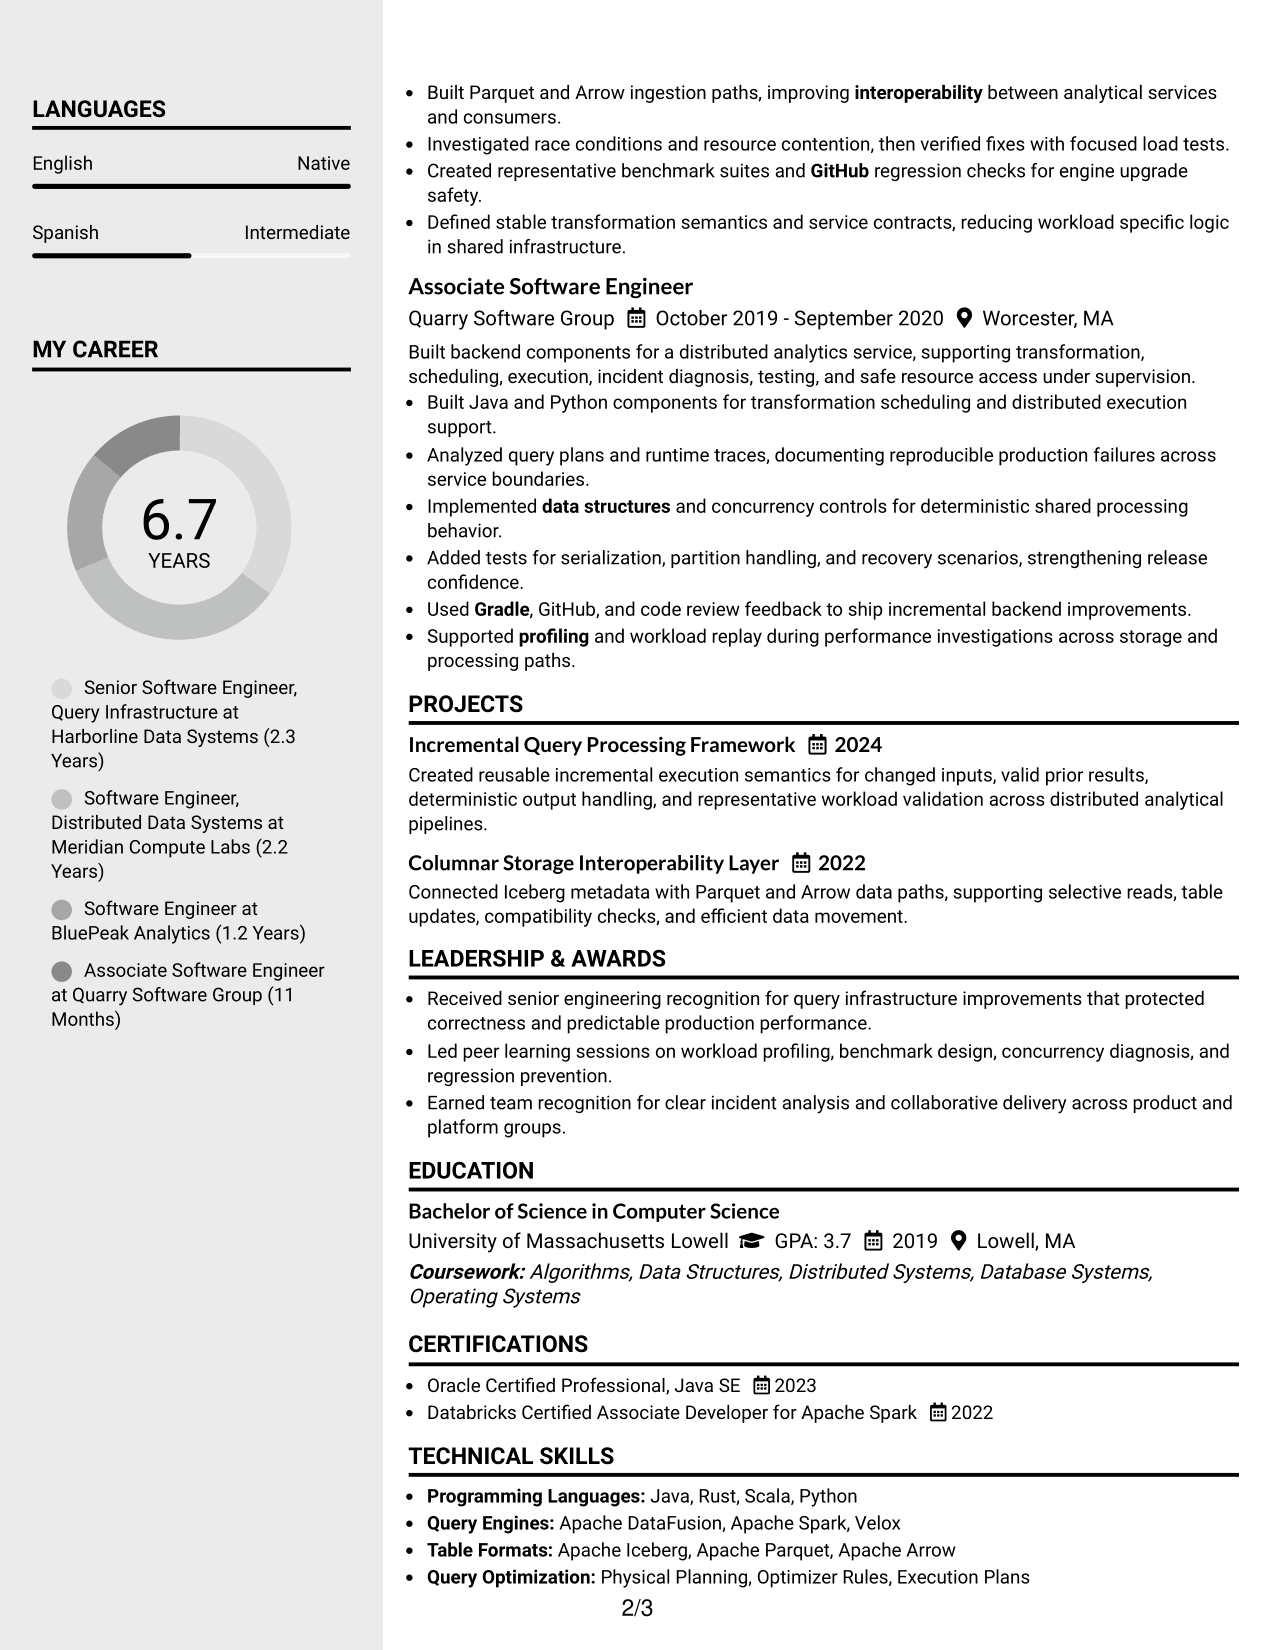
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • Two columns separate compact skills from longer experience and achievement content.
  • The sidebar gives supporting credentials a clear place beside career history.
  • Main-column space keeps role progression readable while secondary details stay accessible.

Best For

  • Dense skills sections
  • Compact supporting credentials
  • Experience needing wider main space
  • Quick reference during technical review
  • Balanced two-column organization


#5 Two Column Format Resume Example

A balanced two-column body lets recruiters compare career evidence with supporting sections without losing the overall reading order.
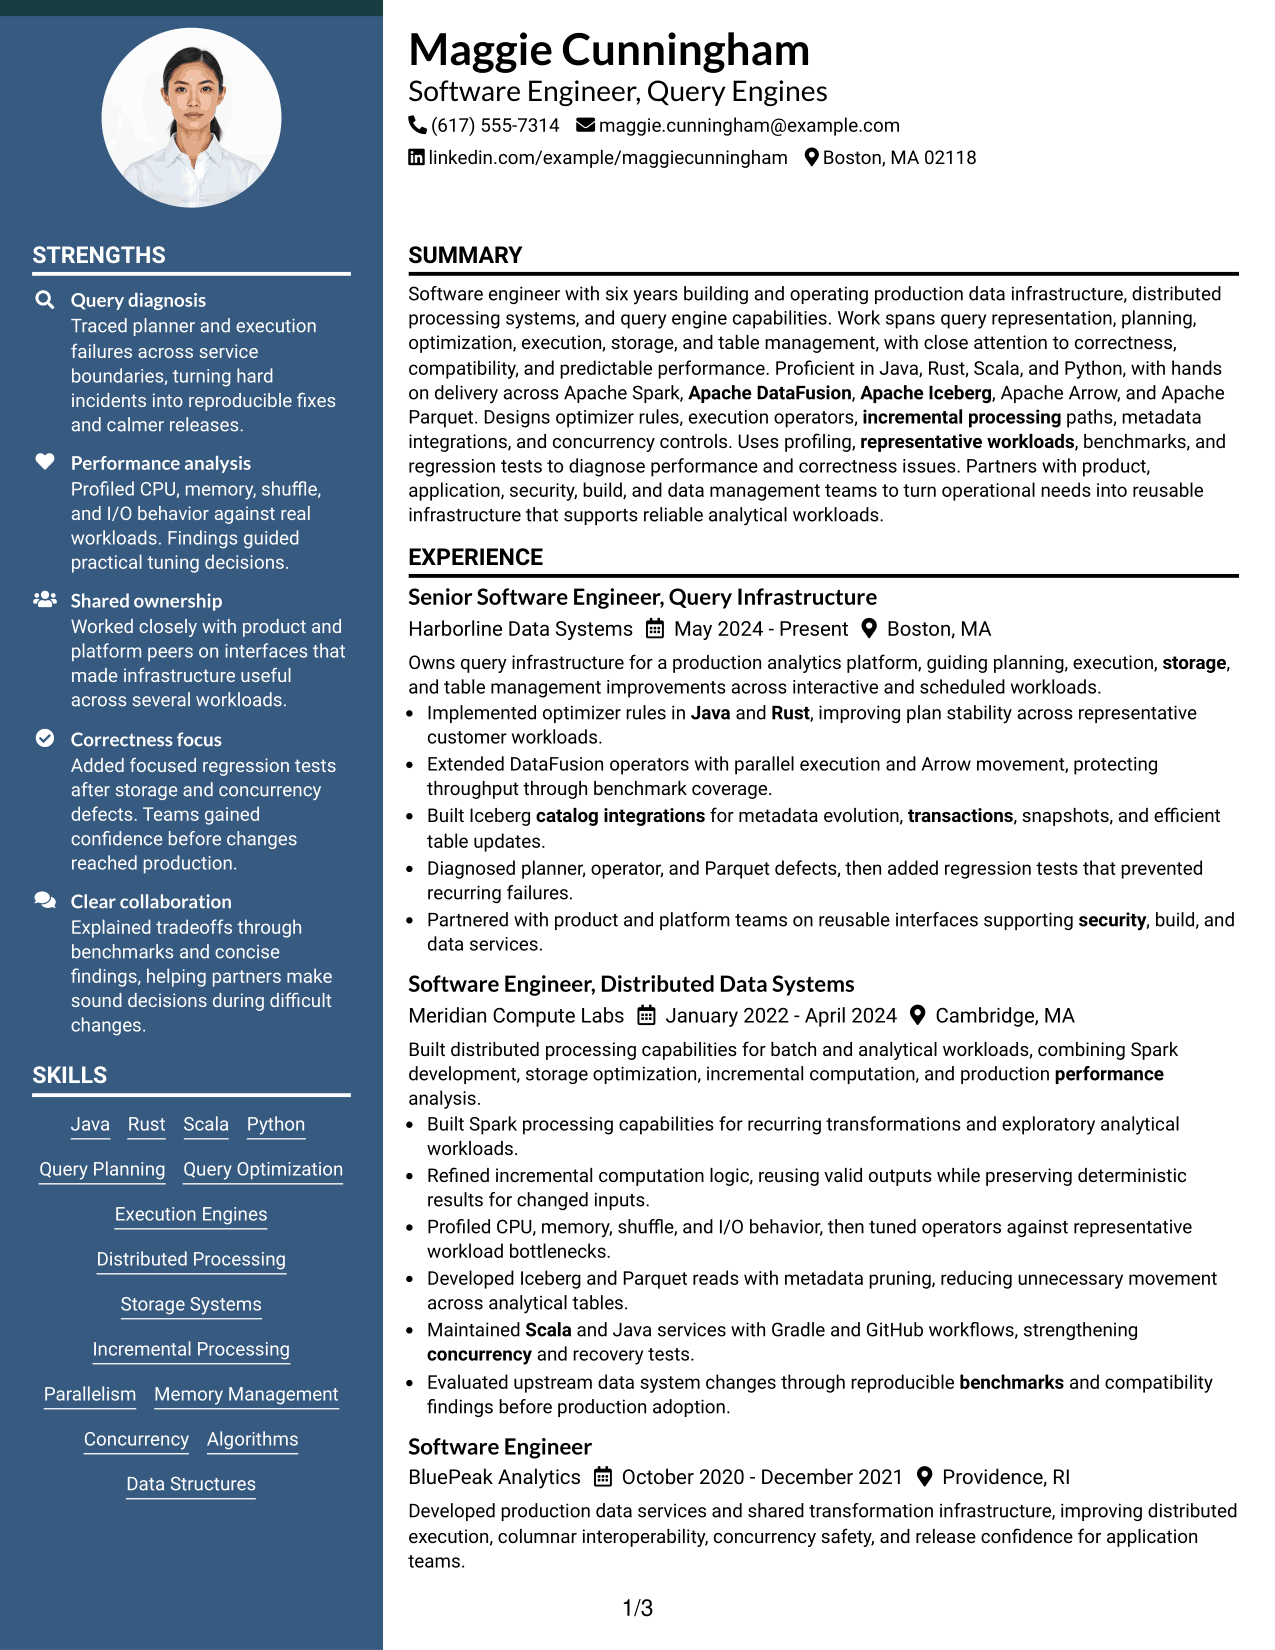
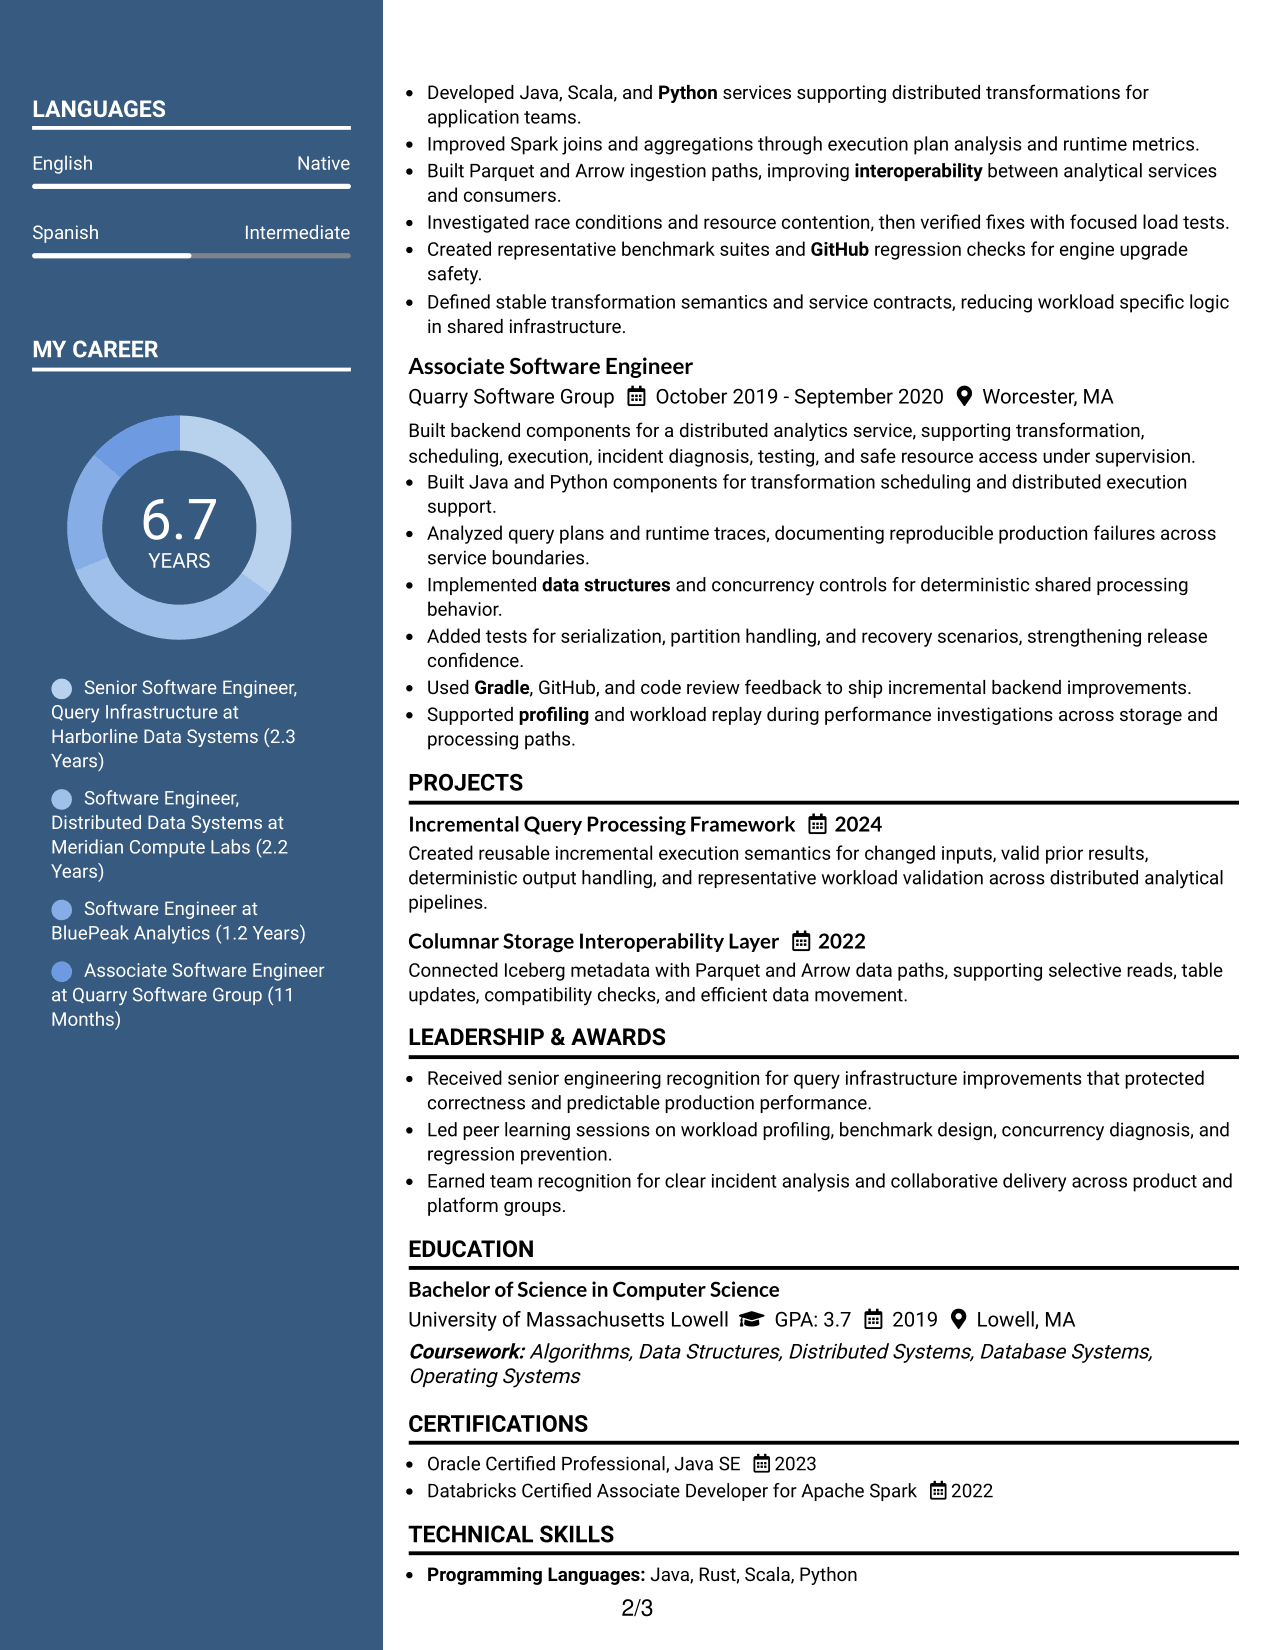
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • Parallel columns make experience and supporting sections visible within the same view.
  • Section separation helps reviewers compare achievements with broader skills and credentials.
  • Balanced space suits a resume with substantial career history and supporting details.

Best For

  • Broad technical backgrounds
  • Several supporting resume sections
  • Side-by-side information review
  • Moderate content density
  • Structured visual balance
 

#6 Photo Header Two Column Format Resume Example

A photo header sits above a two-column body, giving recruiters a clear identity area before they scan career and supporting sections.
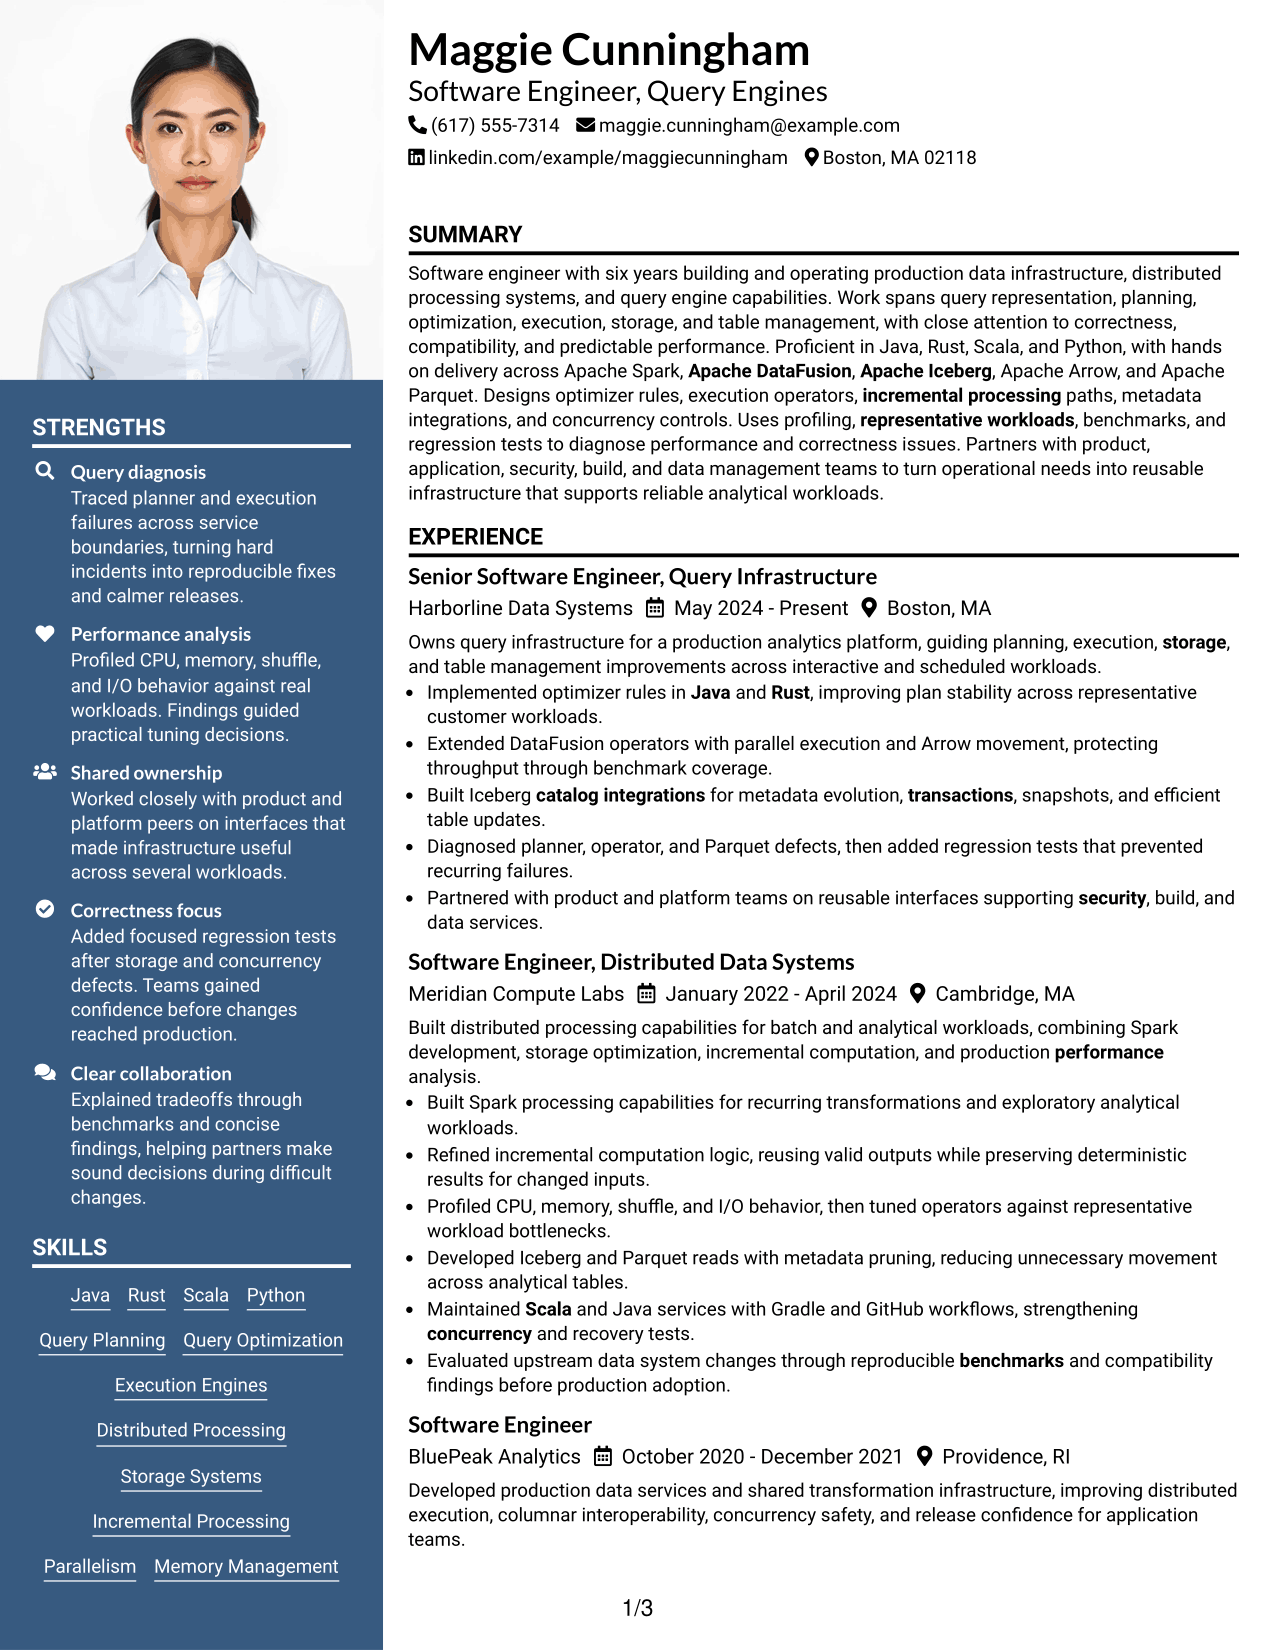
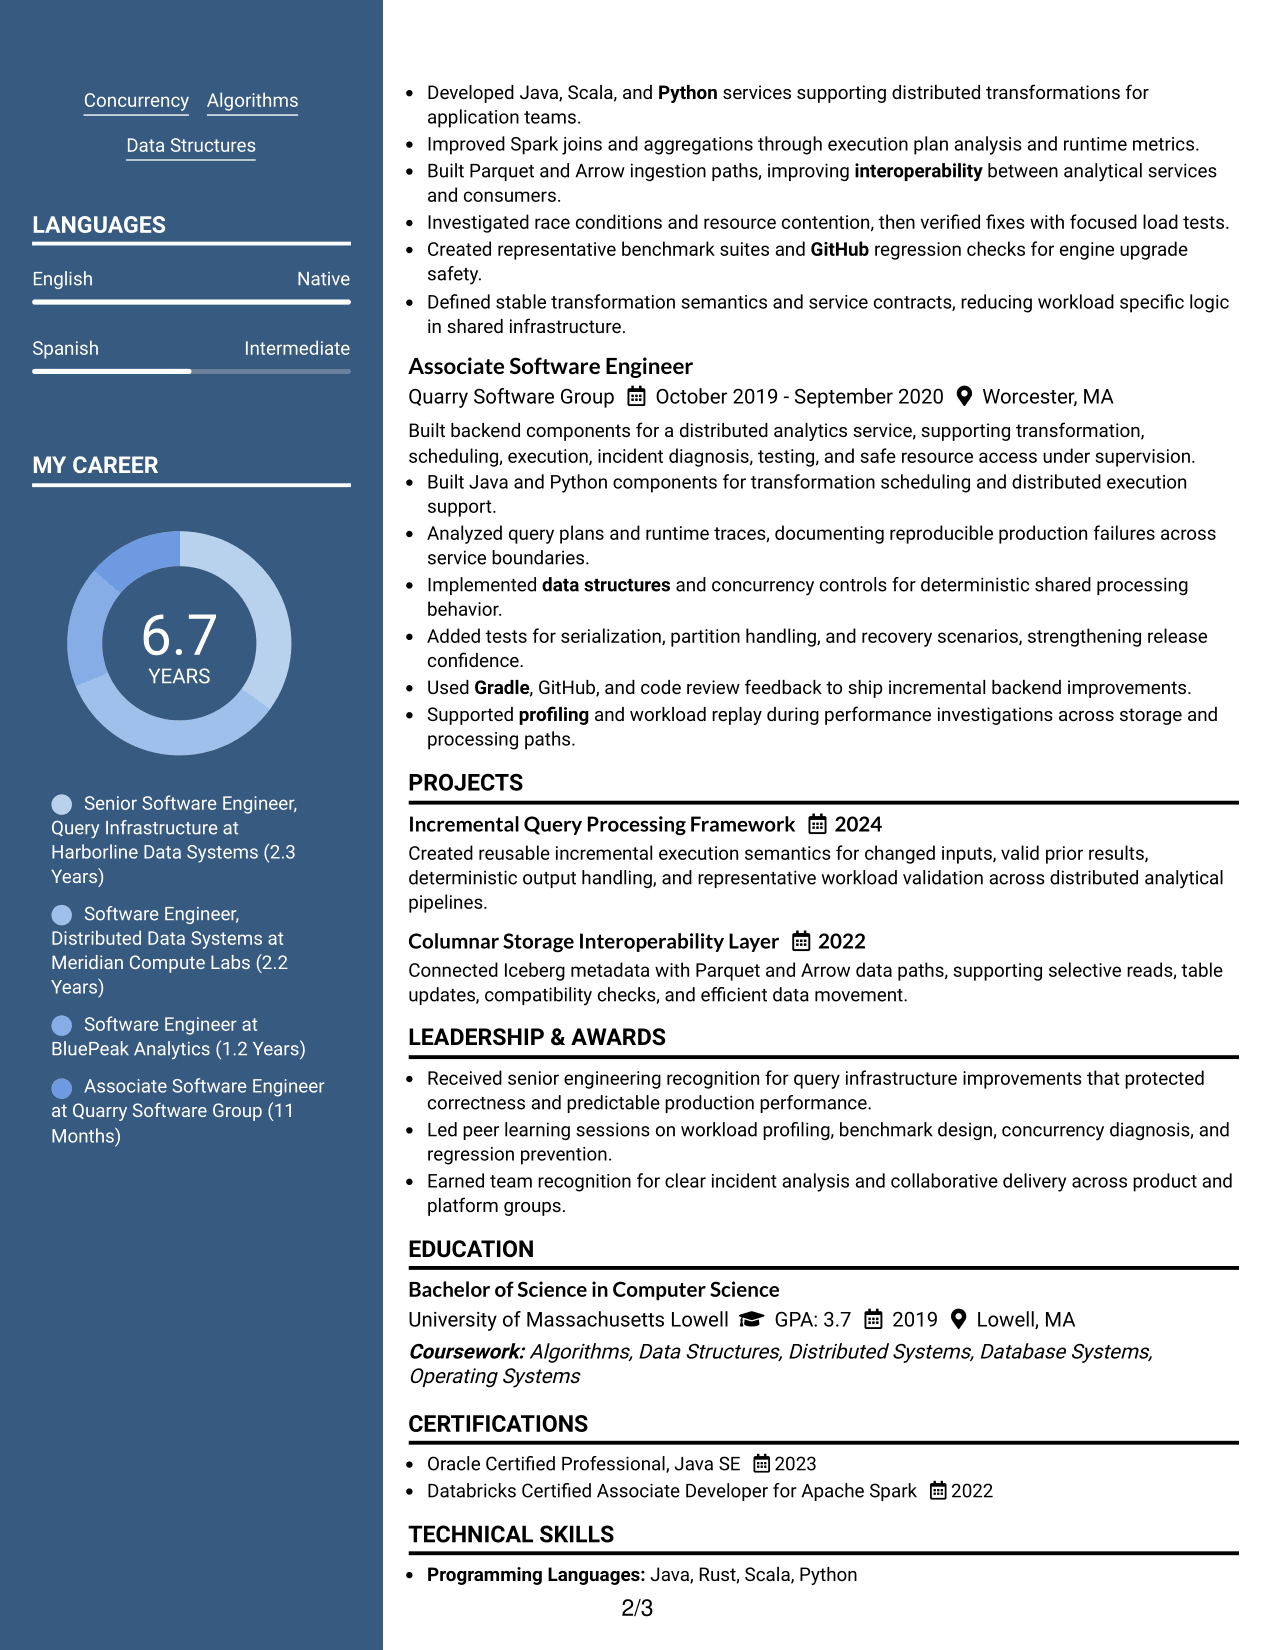
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • The header photo is separate from the two-column career content below.
  • Two body columns give experience and supporting qualifications distinct reading areas.
  • Section boundaries help recruiters move between achievements, skills, education, and credentials.

Best For

  • Regions where photos are expected
  • Resumes with varied supporting sections
  • Readers comparing main and secondary content
  • Professional profiles needing a strong header
  • Two-column career summaries
 

#7 Simple Two Column Format Resume Example

A simple two-column structure gives recruiters a compact way to review detailed experience beside shorter skills and credential sections.
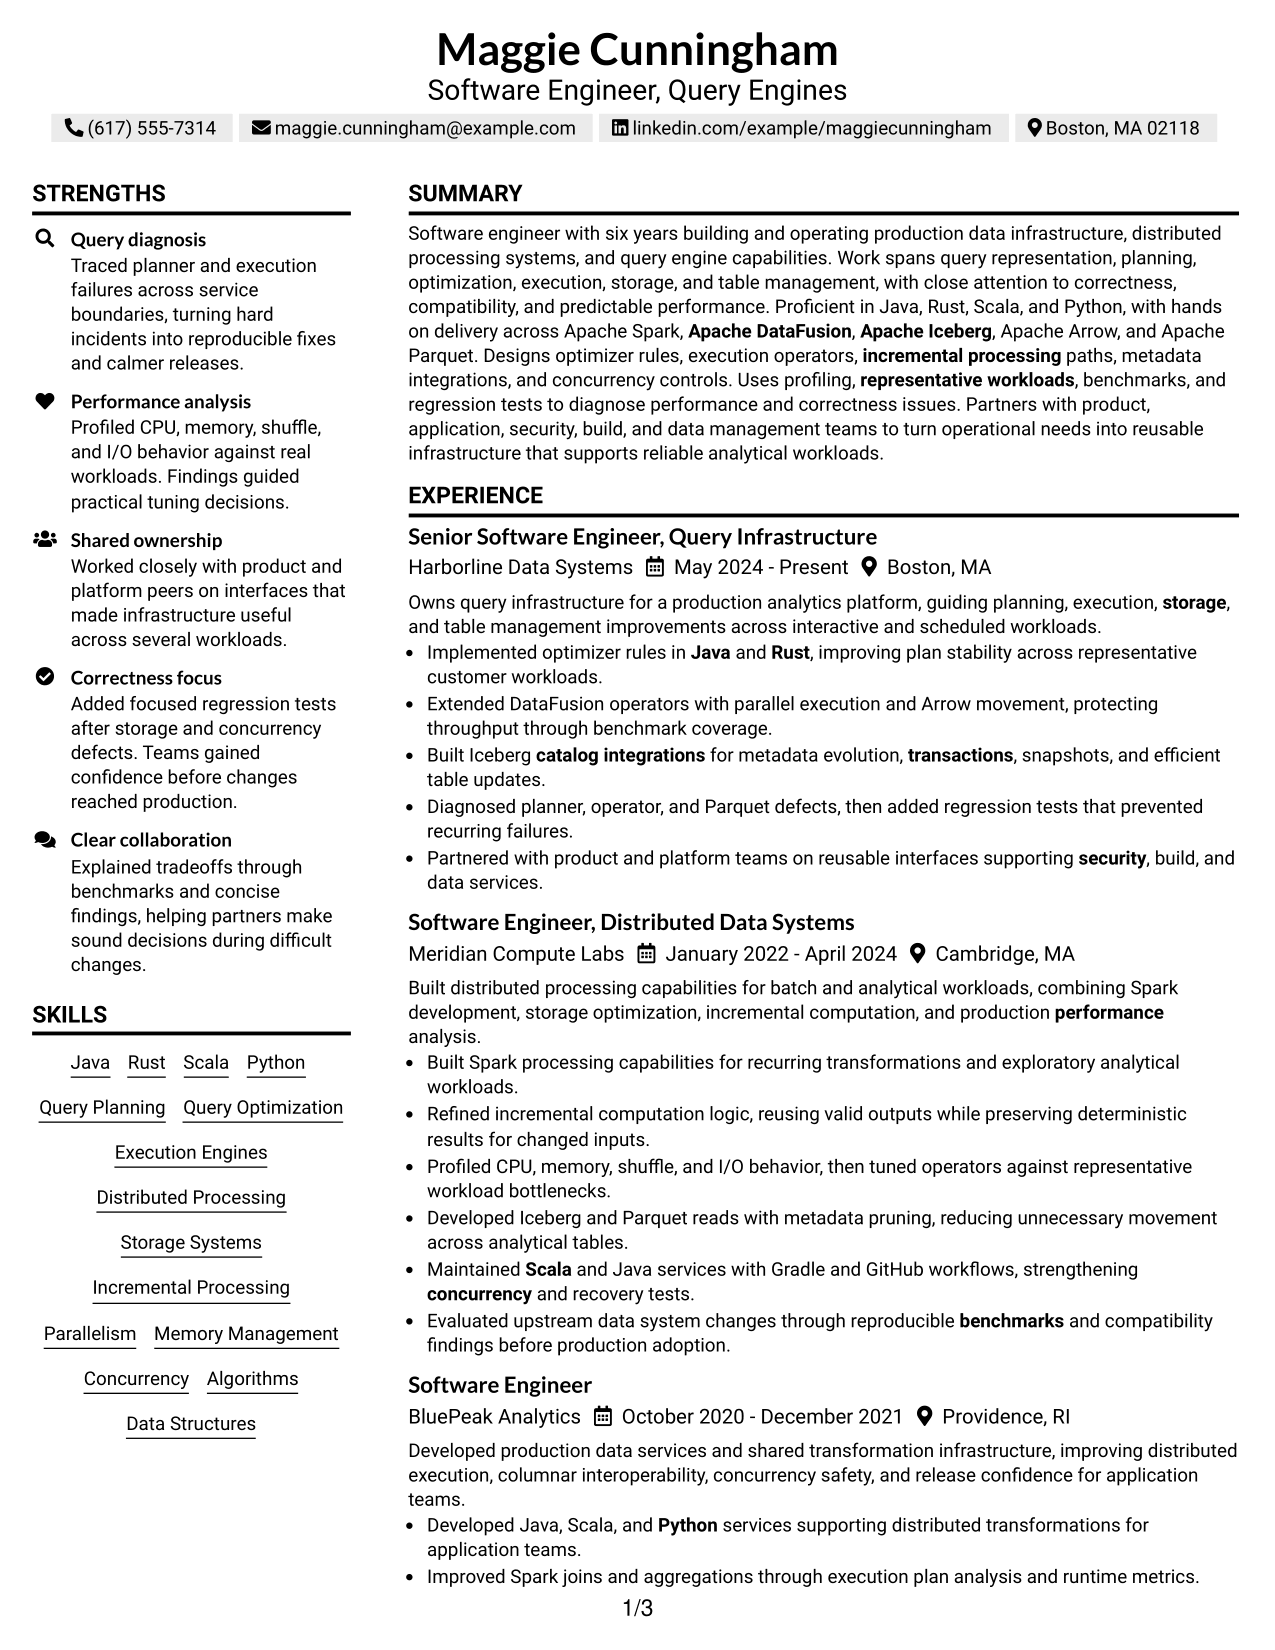
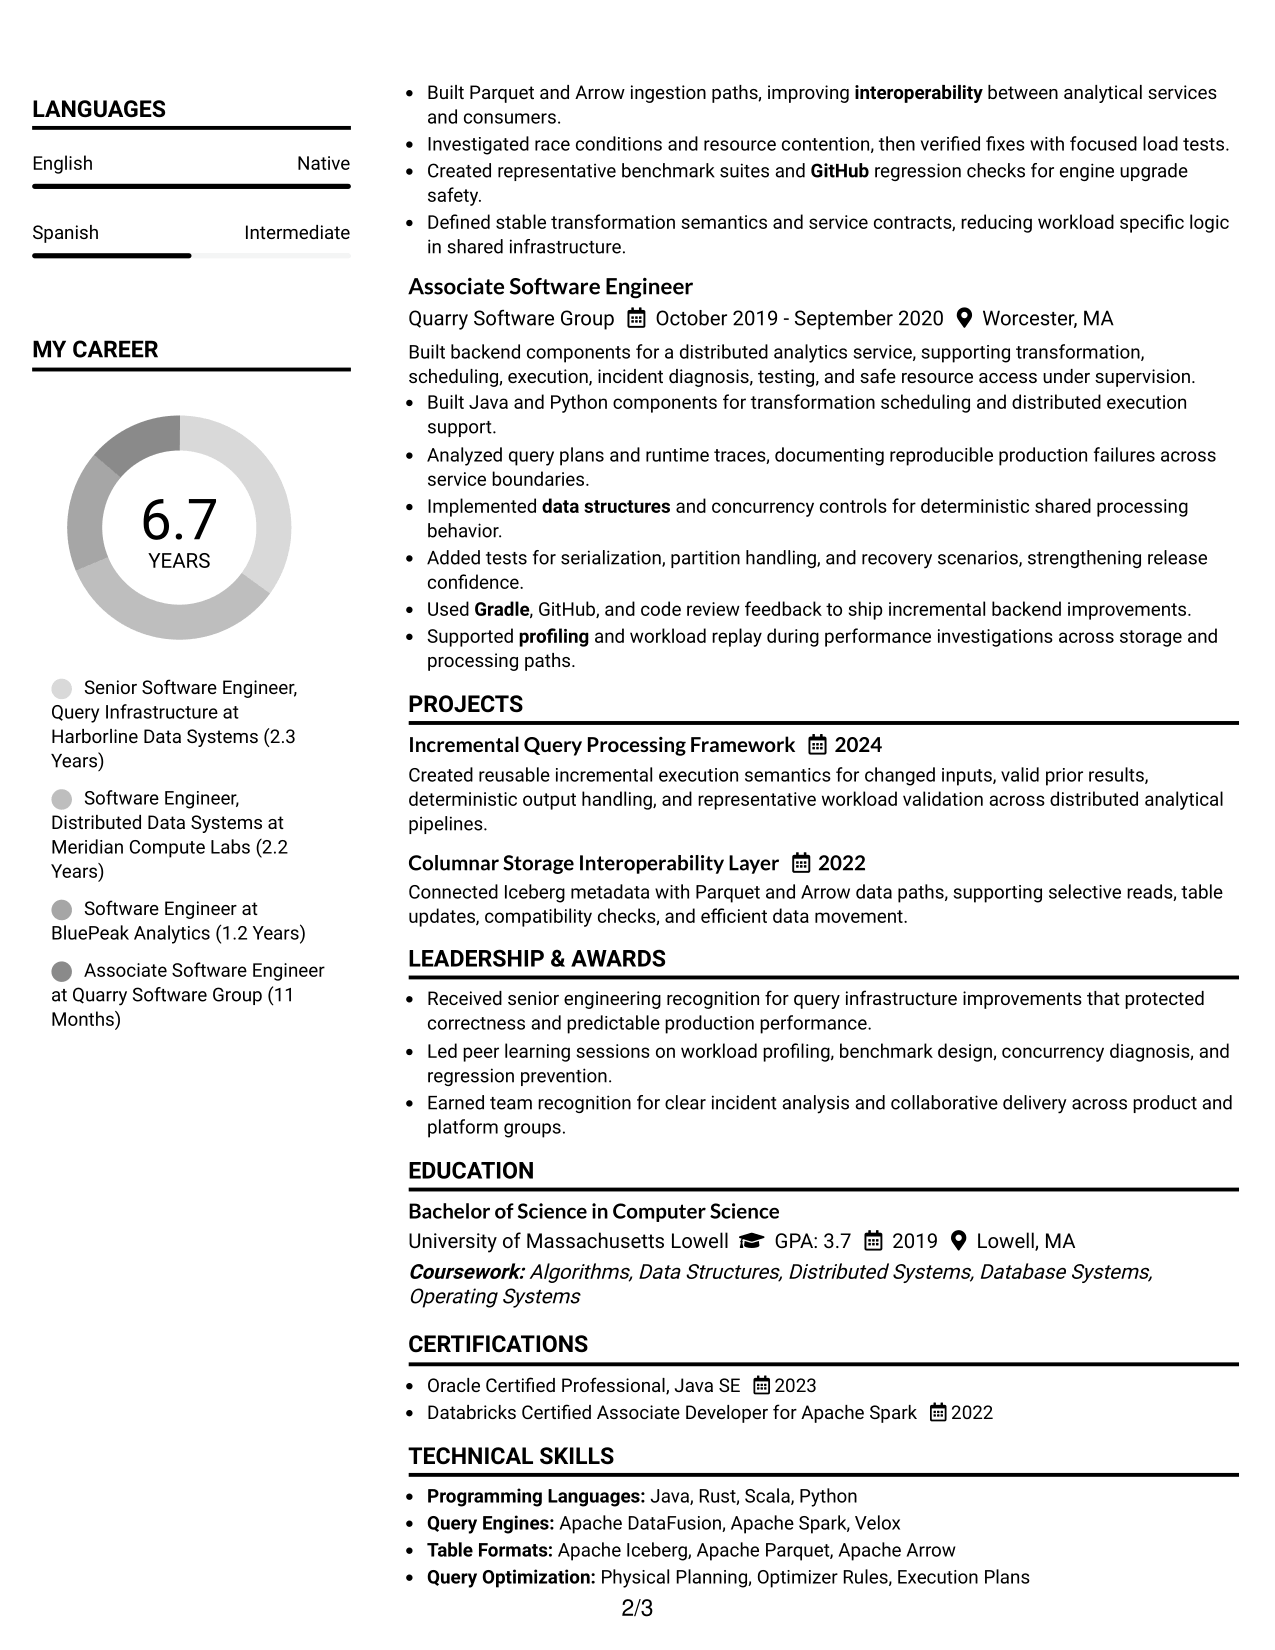
 
Resume Example Page 1   Resume Example Page 2

Why This Format Works

  • A wider career area keeps experience and achievements easy to read.
  • The second column can group shorter skills, education, and credential sections.
  • Simple section boundaries keep parallel content clear without heavy visual treatment.

Best For

  • Compact technical resumes
  • Short supporting sections
  • Experience-first reading
  • Minimal visual styling
  • Easy comparison across sections


Why Build Your Software Engineer - Query Engines Resume with ResumeInMinutes

ResumeInMinutes helps you organize technical experience, skills, projects, education, and credentials into sections that are easy to review and update.

  • ATS-friendly section structure
  • Keyword-focused resume content
  • Experience and achievement organization
  • Skills and tools grouping
  • Free PDF resume previews
  • Resume customization support

You can adjust the wording and format for a Software Engineer - Query Engines application while keeping the resume focused on supported technical evidence and clear career history.


See Also


Frequently Asked Questions

Are these Software Engineer - Query Engines resume templates ATS-friendly?

They use clear section structure and readable headings. For stronger ATS alignment, include accurate terms from your own work, such as query planning, distributed processing, storage systems, and performance engineering.

Are these different resumes?

No. The examples show the same Software Engineer - Query Engines resume in different visual formats, so you can compare structure without changing the underlying career facts.

What should a Software Engineer - Query Engines resume include?

Include a focused summary, professional experience, technical skills, education, and relevant projects or credentials. Show query planning, execution, storage, distributed systems, correctness, and performance work only when your background supports them.

Can I download the resume templates as PDFs?

Yes. Each resume style includes a free PDF preview so you can review the format before choosing one for your application.

Which resume format works well for a query engine software engineer?

A clear one-column format is useful when reading order is the main concern. A two-column format can help separate compact skills or credentials from detailed experience when the structure remains easy to follow.

How should I write technical experience bullets?

Start with the engineering action, then explain the system area and result. Use measured outcomes when you have them, and avoid numbers or claims you cannot support.

Should I include a photo on my resume?

Include a photo only when it is customary or expected in your country or region. For most U.S. applications, a no-photo resume is generally the safer choice.

Can I customize these resume templates?

Yes. You can adjust resume text, section order, layout, and PDF format while keeping the content accurate for your Software Engineer - Query Engines background.
ATS score 86%

How we calculate this score

  • Keywords: 60% of the total. AI extracts keywords from your job description. If you do not provide one, a standard job description for the title matching your resume is used. This is not a match to a specific vacancy.
  • Text-based resume: 20%. The text resume assessed here receives 100 for this part.
  • Resume quality: 20%. We start at 100 and subtract points for issues found by our resume checks, down to a minimum of zero.
  • Keyword coverage = 100 × (confirmed matches + 0.8 × possible matches) ÷ total keywords, rounded and capped at 100. Possible matches still need checking. Saved generation audits use their saved keyword percentage.
  • Final score = 60% of keyword coverage + 20% of the text score + 20% of the quality score, rounded to a whole number. Without keywords, no overall ATS score is available.

What this score means

Our scores are estimates, not employer ratings. They may contain errors and do not guarantee accurate parsing, a ranking, an interview, or a job. Check your document against the employer’s requirements. You are responsible for relying on this score.

Terms and Conditions

Score weights: Keywords 60% · Text based resume 20% · Resume quality 20%

Live keyword match: 37 of 48 (77%) · Resume quality: 100%

Resume quality 100% · Weight 20% · Issues (0)

Details
  • ✓Name present: Maggie Cunningham
  • ✓Email format: maggie.cunningham@example.com
  • ✓Phone format: (617) 555-7314
  • ✓Experience 1: Job title: Senior Software Engineer, Query Infrastructure
  • ✓Experience 1: Company name: Harborline Data Systems
  • ✓Experience 1: Employment dates: May 2024 - Present
  • ✓Experience 1: Description or achievements: Present
  • ✓Experience 2: Job title: Software Engineer, Distributed Data Systems
  • ✓Experience 2: Company name: Meridian Compute Labs
  • ✓Experience 2: Employment dates: January 2022 - April 2024
  • ✓Experience 2: Description or achievements: Present
  • ✓Experience 3: Job title: Software Engineer
  • ✓Experience 3: Company name: BluePeak Analytics
  • ✓Experience 3: Employment dates: October 2020 - December 2021
  • ✓Experience 3: Description or achievements: Present
  • ✓Experience 4: Job title: Associate Software Engineer
  • ✓Experience 4: Company name: Quarry Software Group
  • ✓Experience 4: Employment dates: October 2019 - September 2020
  • ✓Experience 4: Description or achievements: Present
  • ✓No placeholder fields
  • ✓No repeated achievement bullets
  • ✓No empty bullets

No issues found by the current checks.

Text Based Resume 100% · Weight 20%

Parsed text
Maggie Cunningham
(617) 555-7314
maggie.cunningham@example.com
linkedin.com/example/maggiecunningham
Boston, MA 02118
SUMMARY
Software engineer with six years building and operating production data infrastructure, distributed processing systems, and query engine capabilities. Work spans query representation, planning, optimization, execution, storage, and table management, with close attention to correctness, compatibility, and predictable performance. Proficient in Java, Rust, Scala, and Python, with hands on delivery across Apache Spark, Apache DataFusion, Apache Iceberg, Apache Arrow, and Apache Parquet. Designs optimizer rules, execution operators, incremental processing paths, metadata integrations, and concurrency controls. Uses profiling, representative workloads, benchmarks, and regression tests to diagnose performance and correctness issues. Partners with product, application, security, build, and data management teams to turn operational needs into reusable infrastructure that supports reliable analytical workloads.
EXPERIENCE
Senior Software Engineer, Query Infrastructure
Harborline Data Systems
May 2024 - Present
Boston, MA
Owns query infrastructure for a production analytics platform, guiding planning, execution, storage, and table management improvements across interactive and scheduled workloads.
Implemented optimizer rules in Java and Rust, improving plan stability across representative customer workloads.
Extended DataFusion operators with parallel execution and Arrow movement, protecting throughput through benchmark coverage.
Built Iceberg catalog integrations for metadata evolution, transactions, snapshots, and efficient table updates.
Diagnosed planner, operator, and Parquet defects, then added regression tests that prevented recurring failures.
Partnered with product and platform teams on reusable interfaces supporting security, build, and data services.
Software Engineer, Distributed Data Systems
Meridian Compute Labs
January 2022 - April 2024
Cambridge, MA
Built distributed processing capabilities for batch and analytical workloads, combining Spark development, storage optimization, incremental computation, and production performance analysis.
Built Spark processing capabilities for recurring transformations and exploratory analytical workloads.
Refined incremental computation logic, reusing valid outputs while preserving deterministic results for changed inputs.
Profiled CPU, memory, shuffle, and I/O behavior, then tuned operators against representative workload bottlenecks.
Developed Iceberg and Parquet reads with metadata pruning, reducing unnecessary movement across analytical tables.
Maintained Scala and Java services with Gradle and GitHub workflows, strengthening concurrency and recovery tests.
Evaluated upstream data system changes through reproducible benchmarks and compatibility findings before production adoption.
Software Engineer
BluePeak Analytics
October 2020 - December 2021
Providence, RI
Developed production data services and shared transformation infrastructure, improving distributed execution, columnar interoperability, concurrency safety, and release confidence for application teams.
Developed Java, Scala, and Python services supporting distributed transformations for application teams.
Improved Spark joins and aggregations through execution plan analysis and runtime metrics.
Built Parquet and Arrow ingestion paths, improving interoperability between analytical services and consumers.
Investigated race conditions and resource contention, then verified fixes with focused load tests.
Created representative benchmark suites and GitHub regression checks for engine upgrade safety.
Defined stable transformation semantics and service contracts, reducing workload specific logic in shared infrastructure.
Associate Software Engineer
Quarry Software Group
October 2019 - September 2020
Worcester, MA
Built backend components for a distributed analytics service, supporting transformation, scheduling, execution, incident diagnosis, testing, and safe resource access under supervision.
Built Java and Python components for transformation scheduling and distributed execution support.
Analyzed query plans and runtime traces, documenting reproducible production failures across service boundaries.
Implemented data structures and concurrency controls for deterministic shared processing behavior.
Added tests for serialization, partition handling, and recovery scenarios, strengthening release confidence.
Used Gradle, GitHub, and code review feedback to ship incremental backend improvements.
Supported profiling and workload replay during performance investigations across storage and processing paths.
PROJECTS
Incremental Query Processing Framework
2024
Created reusable incremental execution semantics for changed inputs, valid prior results, deterministic output handling, and representative workload validation across distributed analytical pipelines.
Columnar Storage Interoperability Layer
2022
Connected Iceberg metadata with Parquet and Arrow data paths, supporting selective reads, table updates, compatibility checks, and efficient data movement.
LEADERSHIP & AWARDS
Received senior engineering recognition for query infrastructure improvements that protected correctness and predictable production performance.
Led peer learning sessions on workload profiling, benchmark design, concurrency diagnosis, and regression prevention.
Earned team recognition for clear incident analysis and collaborative delivery across product and platform groups.
EDUCATION
Bachelor of Science in Computer Science
University of Massachusetts Lowell
GPA: 3.7
2019
Lowell, MA
Coursework: Algorithms, Data Structures, Distributed Systems, Database Systems, Operating Systems
CERTIFICATIONS
Oracle Certified Professional, Java SE
2023
Databricks Certified Associate Developer for Apache Spark
2022
TECHNICAL SKILLS
Programming Languages: Java, Rust, Scala, Python
Query Engines: Apache DataFusion, Apache Spark, Velox
Table Formats: Apache Iceberg, Apache Parquet, Apache Arrow
Query Optimization: Physical Planning, Optimizer Rules, Execution Plans
Distributed Systems: Parallel Execution, Data Movement, Incremental Processing
Performance Tools: Profiling, Workload Replay, Runtime Metrics
Build Systems: Gradle, Cargo, GitHub Actions
Testing Practices: Regression Testing, Load Testing, Compatibility Testing
Storage Systems: Columnar Storage, Metadata Pruning, Snapshot Reads
Concurrency Engineering: Data Structures, Memory Management, Failure Recovery
Development Workflows: GitHub, Code Review, Automated Testing
SKILLS
Java
Rust
Scala
Python
Query Planning
Query Optimization
Execution Engines
Distributed Processing
Storage Systems
Incremental Processing
Parallelism
Memory Management
Concurrency
Algorithms
Data Structures
PROFESSIONAL AFFILIATIONS
Member, Apache Software Foundation community discussions focused on Spark, Iceberg, Arrow, and data systems.
Participant, Boston data engineering community, sharing practical lessons on distributed processing and query performance.
LANGUAGES
English (Native)
Spanish (Intermediate)
ADDITIONAL INFORMATION
Work Status
: Authorized to work in United States. No sponsorship required.
REFERENCES
AVAILABLE ON REQUEST

Matched keywords (37)

  • query engine
  • Query Planning
  • Query Optimization
  • Execution Engines
  • Parallelism
  • Memory Management
  • data movement
  • Apache Iceberg
  • catalog integrations
  • transactions
  • interoperability
  • incremental processing
  • correctness
  • performance
  • storage
  • testing
  • benchmarks
  • Java
  • Scala
  • Rust
  • Python
  • Apache Spark
  • Apache DataFusion
  • Velox
  • Apache Arrow
  • Apache Parquet
  • Gradle
  • Cargo
  • GitHub
  • Algorithms
  • data structures
  • concurrency
  • profiling
  • representative workloads
  • Storage Systems
  • security
  • data management

Missing keywords (11)

  • data processing
  • physical execution
  • table metadata
  • open source data systems
  • Apache Comet
  • distributed data processing
  • production systems
  • performance engineering
  • cross team collaboration
  • communication
  • build infrastructure
Disclaimer: All names, images, contact information, employment histories, achievements, security clearances, military credentials, and other qualifications shown in this content are fictional and used for illustrative purposes only. Any resemblance to actual persons, living or deceased, is purely coincidental.

Resume and cover-letter examples and recommendations in this article reflect general best practices and professional experience and are provided for guidance only. Results may vary based on role, industry, region, and hiring organization.

Content Accuracy and Verification: To the fullest extent permitted by applicable law, we do not represent or warrant that resume or cover-letter guidance, examples, recommendations, or related information are accurate, complete, current, error-free, or suitable for any particular purpose. You are responsible for independently reviewing and verifying the information before relying on it.

ATS and Cover-Letter Scores: ATS scores are estimates calculated using our own formula, informed by publicly available guidance on resume formatting and keyword matching. They are not scores issued or endorsed by an ATS provider or employer. Cover-letter scores are also our own assessments. Parsing, weighting, screening criteria, and results vary between systems, employers, job descriptions, and document formats. No score guarantees successful parsing, a particular ranking, an interview, or employment. Use scores as general guidance and independently check your documents against the employer’s requirements. To the fullest extent permitted by applicable law, we accept no liability for errors in scores or parsing, or losses arising from reliance on these assessments. Nothing in this notice excludes liability or limits consumer rights that cannot lawfully be excluded or limited.

Terms and Conditions
 
> JP 1 1
PDF Footer and Margins Setup
The margins are applied to the document, and the footer shows up in the preview and the PDF

Footer Font Settings

Are you applying for a specific job
so we can tailor your resume to it?
Are you applying for a specific job
so we can tailor your cover letter to it?
Type your details as text to generate a personalized resume Type your details as text to generate a personalized cover letter
Website link found! Ready to create resume from:
Drag the into the box to verify you're human.
Drop here

My Resumes

Displaying {number_of_files} files (out of {total_of_all_files} total)
Name File Type Last Modified: Description:

Rename File

Filename already exists!

Delete Files

Warning: This action is irreversible. Once you click submit, the files will be permanently deleted.

Heading text
Upload From Computer Upload
Select From Existing
LinkedIn
Drag & Drop files anywhere in this tab, or

Uploaded Files

Delete Name Last Updated Use This File
Select this to use the file for generating your resume and cover letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

My Files

Resumes or cover letters you create will appear here. No files available yet.
Delete Name Last Updated Use This File
Select this to use the file for generating your resume and cover letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

Add LinkedIn Profile PDF

You can download your LinkedIn profile as a PDF by opening linkedin.com in a web browser, clicking your profile photo, selecting the “More” or “Resources” button, and choosing “Save to PDF.” You can then attach the PDF using the Upload From Computer tab.

Paste Your LinkedIn Profile Text

If you have copied the LinkedIn profile text, paste it below. See how to copy your profile from LinkedIn

Select this to use the LinkedIn profile text for generating your resume and cover letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

Try these controls

<
>